# Enterprise GPU Rental | H100, A100, B200, B300 On-Demand | Spheron Docs
> Rent NVIDIA H100, A100, B200 GPUs from $0.72/hr. No contracts. Instant deployment from Tier 3/4 data centers. Perfect for AI training, LLM inference & ML workloads. 99% uptime.
## API reference
This page covers the Spheron AI REST API for programmatic access to GPU instances, SSH keys, volumes, and account balance.
:::tip[Using an AI agent?]
Hand this API to Claude, ChatGPT, or any LLM with the ready-made [API skill for AI agents](/api-skill). The agent learns the full deploy flow, parameter rules, and error handling, and knows to request an API key. Download the skill file.
:::
### Table of contents
* [Quick start](#quick-start)
* [Authentication](#authentication)
* [Endpoints](#endpoints)
* [Providers](#get-providers)
* [GPU offers](#get-gpu-offers)
* [CPU offers](#cpu-offers)
* [Deployments](#deployments)
* [Instance lifecycle](#instance-lifecycle)
* [SSH keys](#ssh-keys)
* [Volumes](#volumes)
* [Teams](#teams)
* [Error reference](#error-reference)
* [Status values](#status-values)
* [Rate limits](#rate-limits)
* [Security](#security)
* [Common workflows](#common-workflows)
### Quick start
#### 1. Get your API key
Generate an API key from your [Spheron dashboard](https://app.spheron.ai/settings).
#### 2. Make your first API call
Test your connection by listing available providers:
```bash
curl -H "Authorization: Bearer " \
https://app.spheron.ai/api/providers
```
#### 3. List available GPUs
```bash
curl -H "Authorization: Bearer " \
"https://app.spheron.ai/api/gpu-offers?limit=5"
```
#### 4. Deploy your first instance
```bash
curl -X POST "https://app.spheron.ai/api/deployments" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{
"provider": "spheron-ai",
"offerId": "rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-22.04",
"instanceType": "DEDICATED",
"sshKeyId": "your_ssh_key_id"
}'
```
### Base URL
```
https://app.spheron.ai
```
### Authentication
Include your API key in the Authorization header for all authenticated requests:
```bash
Authorization: Bearer
```
**Security note:** Treat API keys like passwords. Never expose them in client-side code or public repositories. See [Security best practices](/security) for more information.
### Endpoints
#### Get providers
Get a list of all available GPU providers (public endpoint). Returns the subset of providers currently configured on the server.
**Method:** `GET`
**Path:** `/api/providers`
**Response example:**
```json
[
"data-crunch",
"massed-compute",
"sesterce",
"spheron-ai",
"spheron-es",
"spheron-ms",
"spheron-am"
]
```
***
#### Get GPU offers
Get available offers with filtering and pagination. Authenticate to see team discounts.
This endpoint returns both GPU offers and the single CPU Node row. Use `computeType` to narrow it to one or the other. See [CPU offers](#cpu-offers) for the CPU-specific shape.
**Method:** `GET`
**Path:** `/api/gpu-offers`
**Headers:**
* `Authorization`: Bearer `` (optional)
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :----------------------------------------------------------------------------------------------------------------- |
| `page` | number | No | Page number (default: 1) |
| `limit` | number | No | Items per page (default: 10) |
| `search` | string | No | Search term for GPU models |
| `sortBy` | string | No | Sort field (default: popularity) |
| `sortOrder` | string | No | asc or desc (default: asc) |
| `instanceType` | string | No | Filter by type: 'SPOT', 'DEDICATED', or 'CLUSTER' (case-insensitive) |
| `computeType` | string | No | Filter by silicon: `cpu` returns only the CPU Node row, `gpu` returns only GPU offers. Omit to list both (default) |
**Response example:**
```json
{
"data": [
{
"gpuType": "rtx-4090",
"gpuModel": "RTX 4090",
"baseGpuType": "rtx-4090",
"interconnectVariants": ["PCIe"],
"hasMultipleVariants": false,
"displayName": "RTX 4090",
"popularity": 85,
"totalAvailable": 12,
"lowestPrice": 0.45,
"highestPrice": 0.65,
"averagePrice": 0.55,
"providers": ["massed-compute", "spheron-ai"],
"offers": [
{
"provider": "massed-compute",
"offerId": "rtx-4090-massed-compute-1-dedicated",
"name": "RTX 4090",
"description": "High-performance gaming and AI GPU",
"vcpus": 8,
"memory": 32,
"storage": 100,
"gpuCount": 1,
"price": 0.50,
"available": true,
"clusters": ["us-east-1", "us-west-2"],
"gpu_memory": 24,
"os_options": ["ubuntu-20.04", "ubuntu-22.04"],
"maintenance": false,
"interconnectType": "PCIe",
"interconnectDescription": "PCIe interface",
"instanceType": "DEDICATED",
"supportsCloudInit": true,
"extras": {
"deployment_type": "vm",
"networking_type": "standard"
}
},
{
"provider": "data-crunch",
"offerId": "rtx-4090-data-crunch-1-spot",
"name": "RTX 4090 SPOT",
"description": "Cost-effective SPOT instance (lower price, may be interrupted)",
"vcpus": 8,
"memory": 32,
"storage": 100,
"gpuCount": 1,
"price": 0.25,
"spot_price": 0.25,
"available": true,
"clusters": ["us-east-1", "eu-west-1"],
"gpu_memory": 24,
"os_options": ["ubuntu-20.04", "ubuntu-22.04"],
"maintenance": false,
"interconnectType": "PCIe",
"interconnectDescription": "PCIe interface",
"instanceType": "SPOT",
"supportsCloudInit": true,
"extras": {
"deployment_type": "vm",
"networking_type": "standard"
},
"note": "For SPOT instances: price = spot_price (discounted rate with possible interruption)"
},
{
"provider": "spheron-ai",
"offerId": "baremetal_h100_sxm5_8",
"name": "H100 SXM5 8x GPU Bare Metal",
"description": "8x H100 SXM5 GPUs, 832 vCPUs, 8192GB RAM, 144000GB Storage. Bare Metal with NVLink between GPUs.",
"vcpus": 832,
"memory": 8192,
"storage": 144000,
"gpuCount": 8,
"price": 15.84,
"available": true,
"clusters": ["dalas-united states"],
"region": "dalas-united states",
"gpu_memory": 80,
"os_options": ["Ubuntu 20.04 LTS", "Ubuntu 22.04 LTS"],
"maintenance": false,
"interconnectType": "NVLink",
"interconnectDescription": "NVLink high-speed GPU interconnect",
"instanceType": "CLUSTER",
"supportsCloudInit": true,
"extras": {
"deployment_type": "cluster",
"networking_type": "ethernet"
}
}
]
}
],
"total": 50,
"page": 1,
"limit": 10,
"totalPages": 5
}
```
:::info[Discount information (authenticated only)]
**Without authentication:** Only the `price` field is included (original undiscounted price). No discount fields are returned.
**With authentication (your team):** Additional discount fields are included in each offer:
* `price`: Original undiscounted price per hour
* `originalPrice`: Same as `price` (for reference)
* `discountedPrice`: Final price after your team's best discount is applied (5-50%)
* `discountPercentage`: Your team's actual discount percentage
* `hasDiscount`: Whether your team has an active discount
Discounts are either volume-based or admin-assigned. The higher of the two is automatically applied.
:::
:::info[Lifecycle and deployment shape]
* `pauseUnsupportedReason`: Present on every offer. It is `null` when an instance from this offer can be stopped, and otherwise carries the reason it cannot, ready to show to a user. Read it before you promise a Stop control. See [Instance lifecycle](/concepts/instance-lifecycle).
* `extras.deployment_type`: `vm`, `baremetal`, or `cluster`. A bare metal offer supports neither stopping nor restarting.
:::
***
#### CPU offers
CPU Node is a CPU-only instance with no GPU attached. It is served by the same `/api/gpu-offers` endpoint as a single row, not as one entry per provider.
**Filter to CPU only:**
```bash
curl -H "Authorization: Bearer " \
"https://app.spheron.ai/api/gpu-offers?computeType=cpu"
```
`?search=cpu` returns the same row. Passing `computeType=gpu` excludes it, and omitting the parameter lists both.
**What the row looks like:**
* `gpuType` is `"CPU"` and `displayName` is `"CPU NODE"`.
* Every entry in `offers[]` reports `gpuCount: 0` and `gpu_memory: 0`.
* Size is described by `vcpus` and `memory` rather than a GPU model.
* `clusters` holds the region, `os_options` holds the deployable images, and `offerId` is what a deployment takes.
**Response example (one offer from the CPU Node row):**
```json
{
"data": [
{
"gpuType": "CPU",
"gpuModel": "",
"baseGpuType": "CPU",
"displayName": "CPU NODE",
"totalAvailable": 29,
"lowestPrice": 0.0862,
"providers": ["sesterce", "data-crunch", "spheron-ai"],
"offers": [
{
"provider": "data-crunch",
"offerId": "CPU.4V.16G_FIN-01_200_spot",
"name": "0x AMD EPYC",
"description": "0x AMD EPYC, 4 vCPUs, 16GB RAM.",
"vcpus": 4,
"memory": 16,
"storage": 200,
"gpuCount": 0,
"gpu_memory": 0,
"price": 0.0862,
"spot_price": 0.0862,
"available": true,
"clusters": ["Finland 1"],
"os_options": ["Jupyter", "Ubuntu 22.04", "Ubuntu 24.04"],
"maintenance": false,
"instanceType": "SPOT",
"supportsCloudInit": true,
"extras": {
"deployment_type": "vm"
}
}
]
}
],
"total": 1,
"page": 1,
"limit": 10,
"totalPages": 1
}
```
**Deploy a CPU offer:**
Send `gpuType: "CPU"` with `gpuCount: 0` to `POST /api/deployments`. Every other parameter works the way it does for a GPU offer.
```bash
curl -X POST "https://app.spheron.ai/api/deployments" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{
"provider": "data-crunch",
"offerId": "CPU.4V.16G_FIN-01_200_spot",
"gpuType": "CPU",
"gpuCount": 0,
"region": "Finland 1",
"operatingSystem": "Ubuntu 22.04",
"instanceType": "SPOT",
"sshKeyId": "your_ssh_key_id"
}'
```
Deployments created this way are stored as CPU nodes, so responses and usage records report a CPU node rather than an unnamed GPU.
:::warning[gpuType must match the offer]
Sending a GPU model name against a CPU `offerId` returns a `400` validation error naming the mismatch. Send `"CPU"`, or omit `gpuType` and let the platform resolve it from the offer.
:::
See [CPU Nodes](/concepts/cpu-nodes) for sizes, regions, and the dashboard flow.
### Deployments
#### Create deployment
Create a new GPU instance deployment.
**Method:** `POST`
**Path:** `/api/deployments`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :---------------- | :-------- | :------- | :-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `provider` | string | Yes | Provider name (e.g., `data-crunch`, `massed-compute`, `sesterce`, `spheron-ai`, `spheron-es`, `spheron-ms`, `spheron-am`). Call `GET /api/providers` for the live list of configured providers. |
| `offerId` | string | Yes | Unique offer ID from the GPU offers endpoint |
| `gpuType` | string | Yes | GPU type identifier (e.g., rtx-4090, h100). Send `CPU` for a [CPU Node offer](#cpu-offers). |
| `gpuCount` | number | Yes | Number of GPUs to deploy. Send `0` for a CPU Node offer. |
| `region` | string | Yes | Deployment region or cluster. Send the offer's `clusters` value back unchanged. |
| `operatingSystem` | string | Yes | Operating system (e.g., ubuntu-20.04, ubuntu-22.04) |
| `instanceType` | string | Yes | Instance type: 'SPOT', 'DEDICATED', or 'CLUSTER' (case-insensitive) |
| `sshKeyId` | string | No | SSH key ID from your saved keys (either this or ssh\_public\_key required) |
| `ssh_public_key` | string | No | Inline SSH public key content (either this or sshKeyId required). A temporary key will be created. |
| `teamId` | string | No | Team ID for team deployments (optional) |
| `name` | string | No | Optional name for the deployment |
| `cloudInit` | object | No | Cloud-Init configuration object. Supports fields: runcmd (string\[]), packages (string\[]), writeFiles (array of `{ path, content, owner?, permissions? }`). |
| `volumeIds` | string\[] | No | IDs of persistent volumes to attach at launch. Each volume must match the deployment's provider and region. Per-provider rules: Sesterce: single-item array, volumes attach at instance creation and cannot be attached or detached afterwards; Spheron AI: up to 10 volumes per instance, each volume can only be attached to one instance at a time (hot-detach and re-attach supported post-launch); Verda: up to 10 volumes per instance, each volume can be shared across multiple instances; Spheron ES: multiple volumes per instance, each volume can be shared across multiple instances read-write or read-only, and attaching at deploy time avoids the VM restart that a hot-attach causes; Spheron MS: single-item array, and the volume's region must equal the offer's region or the request is rejected before anything is created; Spheron AM: volumes are not available, and a request carrying `volumeIds` is rejected rather than created without them. |
**Request body example:**
```json
{
"provider": "massed-compute",
"offerId": "rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-20.04",
"instanceType": "DEDICATED",
"sshKeyId": "ssh_key_id_here",
"teamId": "team_id_optional",
"name": "My GPU Instance",
"note": "Alternatively, use 'ssh_public_key' instead of 'sshKeyId' to create a temporary SSH key",
"cloudInit": {
"runcmd": [
"echo 'Hello from cloud-init'",
"apt-get update"
],
"packages": ["curl", "git"],
"writeFiles": [
{
"path": "/etc/motd",
"content": "Welcome to your instance!",
"owner": "root:root",
"permissions": "0644"
}
]
},
"volumeIds": ["vol_abc123"]
}
```
**Response example:**
```json
{
"id": "deployment_id",
"name": "My GPU Instance",
"userId": "user_id",
"teamId": "team_id",
"gpuModelId": "rtx-4090-rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"offerId": "rtx-4090-spheron-ai-1",
"providerId": "spheron-ai",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-20.04",
"instanceType": "DEDICATED",
"sshKeyId": "ssh_key_id_here",
"tempSshKeyId": null,
"sshKeyName": "My SSH Key",
"sshKeyFingerprint": "SHA256:abc123...",
"ipAddress": null,
"user": null,
"status": "deploying",
"startedAt": null,
"stoppedAt": null,
"lastCreditDeduction": null,
"totalCost": 0,
"hourlyRate": 0.50,
"originalHourlyRate": 0.50,
"discountPercentage": 0,
"hasDiscount": false,
"vcpus": 8,
"memory": 32,
"storage": 100,
"sshCommand": null,
"sshPort": null,
"portForwards": [],
"createdAt": "2024-01-15T10:30:00Z"
}
```
#### Get deployments
Get a list of your deployments with optional filtering.
**Method:** `GET`
**Path:** `/api/deployments`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------- | :----- | :------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `userId` | string | No | Filter by user ID (must be your own) |
| `teamId` | string | No | Filter by team ID |
| `status` | string | No | Filter by status: `active` (running/deploying/stopped), `inactive` (terminated/failed), or a specific status value: `running`, `deploying`, `stopped`, `terminated`, `failed` |
**Response example:**
```json
[
{
"id": "deployment_id",
"name": "My GPU Instance",
"userId": "user_id",
"teamId": "team_id",
"gpuModelId": "rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"offerId": "rtx-4090-spheron-ai-1",
"providerId": "spheron-ai",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-20.04",
"instanceType": "DEDICATED",
"sshKeyId": "ssh_key_id_here",
"tempSshKeyId": null,
"sshKeyName": "My SSH Key",
"sshKeyFingerprint": "SHA256:abc123...",
"ipAddress": "192.168.1.100",
"user": "ubuntu",
"status": "running",
"startedAt": "2024-01-15T10:30:00Z",
"stoppedAt": null,
"lastCreditDeduction": "2024-01-15T11:30:00Z",
"totalCost": 12.50,
"hourlyRate": 0.50,
"stoppedHourlyRate": null,
"pausedAt": null,
"totalPausedHours": 0,
"supportsPause": true,
"supportsRestart": true,
"pauseUnsupportedReason": null,
"providerMinimumRuntimeMinutes": null,
"hasDiscount": false,
"discountPercentage": 0,
"originalHourlyRate": 0.50,
"vcpus": 8,
"memory": 32,
"storage": 100,
"sshCommand": "ssh ubuntu@192.168.1.100",
"sshPort": 22,
"portForwards": [],
"createdAt": "2024-01-15T10:30:00Z"
}
]
```
:::info[Lifecycle fields]
* `stoppedHourlyRate`: What the instance costs while stopped. `null` until it has been stopped at least once.
* `pausedAt`: When the instance was last stopped, or `null` if it is not stopped.
* `totalPausedHours`: Hours spent stopped across every stop and start cycle so far.
* `supportsPause` / `supportsRestart`: Whether this specific instance can be stopped or restarted, narrowed by its machine type and region.
* `pauseUnsupportedReason`: Why stopping is unavailable, or `null` when it is available. Show this to the user rather than deriving your own message.
* `providerMinimumRuntimeMinutes`: The machine type's own minimum reservation, when it declares one. `null` otherwise. The binding minimum is whichever is longer, this or your account's minimum.
See [Instance lifecycle](#instance-lifecycle) for the endpoints that use these fields.
:::
#### Get deployment details
Get details of a specific deployment by ID.
**Method:** `GET`
**Path:** `/api/deployments/{deploymentId}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :------------ |
| `deploymentId` | string | Yes | Deployment ID |
**Response example:**
```json
{
"id": "deployment_id",
"name": "My GPU Instance",
"userId": "user_id",
"teamId": "team_id",
"gpuModelId": "rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"offerId": "rtx-4090-spheron-ai-1",
"providerId": "spheron-ai",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-20.04",
"instanceType": "DEDICATED",
"sshKeyId": "ssh_key_id_here",
"tempSshKeyId": null,
"sshKeyName": "My SSH Key",
"sshKeyFingerprint": "SHA256:abc123...",
"ipAddress": "192.168.1.100",
"user": "ubuntu",
"status": "running",
"startedAt": "2024-01-15T10:30:00Z",
"stoppedAt": null,
"lastCreditDeduction": "2024-01-15T11:30:00Z",
"totalCost": 12.50,
"hourlyRate": 0.50,
"hasDiscount": false,
"discountPercentage": 0,
"originalHourlyRate": 0.50,
"vcpus": 8,
"memory": 32,
"storage": 100,
"sshCommand": "ssh ubuntu@192.168.1.100",
"sshPort": 22,
"portForwards": [],
"extras": {},
"createdAt": "2024-01-15T10:30:00Z"
}
```
#### Rename deployment
Update the display name of an existing deployment. Only the `name` field is mutable. Provider, region, GPU type, instance type, SSH key, attached volumes, and every other deployment attribute are immutable after creation. To change anything else, terminate this deployment and create a new one. The response is the full updated deployment in the same shape returned by `GET /api/deployments/{deploymentId}`.
**Method:** `PATCH`
**Path:** `/api/deployments/{deploymentId}`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :---------------------- |
| `deploymentId` | string | Yes | Deployment ID to update |
**Request body example:**
```json
{
"name": "Renamed Instance"
}
```
:::info[Update rules]
Only `name` is read from the body; any other fields are silently ignored. A request with no `name` is rejected with `404 Nothing to update`. The name is stored verbatim and returned on subsequent `GET` responses. There is no character or length restriction at update time.
:::
**Response example:**
```json
{
"id": "deployment_id",
"name": "Renamed Instance",
"userId": "user_id",
"teamId": "team_id",
"gpuModelId": "rtx-4090-rtx-4090-massed-compute-1",
"gpuType": "rtx-4090",
"offerId": "rtx-4090-massed-compute-1",
"providerId": "massed-compute",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-20.04",
"instanceType": "DEDICATED",
"sshKeyId": "ssh_key_id_here",
"tempSshKeyId": null,
"sshKeyName": "My SSH Key",
"sshKeyFingerprint": "SHA256:abc123...",
"ipAddress": "192.168.1.100",
"user": "ubuntu",
"status": "running",
"startedAt": "2024-01-15T10:30:00Z",
"stoppedAt": null,
"lastCreditDeduction": "2024-01-15T11:30:00Z",
"totalCost": 12.50,
"hourlyRate": 0.50,
"hasDiscount": false,
"discountPercentage": 0,
"originalHourlyRate": 0.50,
"vcpus": 8,
"memory": 32,
"storage": 100,
"sshCommand": "ssh ubuntu@192.168.1.100",
"sshPort": 22,
"portForwards": [],
"createdAt": "2024-01-15T10:30:00Z"
}
```
#### Terminate deployment
Terminate a deployment and its associated cloud instance.
**Method:** `DELETE`
**Path:** `/api/deployments/{deploymentId}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :------------------------- |
| `deploymentId` | string | Yes | Deployment ID to terminate |
**Response example:**
```json
{
"message": "Instance destruction initiated",
"deployment": {
"id": "deployment_id",
"status": "terminated",
"stoppedAt": "2024-01-15T12:30:00Z"
}
}
```
#### Check if deployment can be terminated
Check whether a deployment has met the minimum runtime and can be safely terminated. Use this before calling the terminate endpoint to avoid rejected requests.
**Method:** `GET`
**Path:** `/api/deployments/{deploymentId}/can-terminate`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :--------------------- |
| `deploymentId` | string | Yes | Deployment ID to check |
**Response example:**
```json
{
"canTerminate": true,
"runtime": 25,
"timeRemaining": 0,
"minimumRuntime": 20
}
```
:::info[Response fields]
* `canTerminate`: Whether the deployment can be terminated now
* `runtime`: Minutes since the deployment started
* `timeRemaining`: Minutes remaining until the minimum runtime is met
* `minimumRuntime`: Minimum runtime required before termination is allowed, in minutes
When `canTerminate` is `false`, a `reason` field explains why (e.g., "Instance status is deploying, not running" or "Minimum runtime not met").
`minimumRuntime` is the minimum that applies to this specific deployment: whichever is longer, your account's minimum (20 minutes by default) or the machine type's own `providerMinimumRuntimeMinutes`. Some providers hold a machine for a minimum reservation and charge it in full even when you terminate early, so this varies by machine type rather than by provider. Read it from the response rather than assuming 20.
Minimum runtime counts time actually spent running. Stopping an instance freezes that clock rather than advancing it.
:::
### Instance lifecycle
Stop an instance to pause GPU billing while keeping its disk, start it again, or reboot it in place. Support varies by provider, machine type, and region. See [Instance lifecycle](/concepts/instance-lifecycle) for the support matrix and the billing rules.
Every endpoint below acts on a deployment you own or that belongs to your team. Asking a provider for an action it cannot perform returns an error that names the limit rather than a generic failure.
#### Quote a stop
Return the current rate, the stopped rate, and the breakdown behind it. This endpoint changes nothing, so call it before `pause` to show the user the same number the stop will apply.
**Method:** `GET`
**Path:** `/api/deployments/{deploymentId}/pause-quote`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :------- | :------------------ |
| `deploymentId` | string | Yes | Deployment to quote |
**Response example:**
```json
{
"hourlyRate": 0.0412,
"originalHourlyRate": 0.0412,
"currentHourlyRate": 2.45,
"breakdown": [
{ "label": "Root disk (512 GB)", "amount": 0.0362 },
{ "label": "Public IP (retained)", "amount": 0.005 }
]
}
```
:::info[Response fields]
* `hourlyRate`: What the instance costs per hour while stopped, after any account discount
* `originalHourlyRate`: The stopped rate before any discount
* `currentHourlyRate`: What the instance costs per hour right now
* `breakdown`: Itemised list of what is still charged while stopped
:::
***
#### Stop deployment
Stop the instance. The GPU is released, the disk and its contents are preserved, and billing drops to the stopped rate. Only a running instance can be stopped.
**Method:** `POST`
**Path:** `/api/deployments/{deploymentId}/pause`
**Headers:**
* `Authorization`: Bearer ``
**Example request:**
```bash
curl -X POST "https://app.spheron.ai/api/deployments//pause" \
-H "Authorization: Bearer "
```
**Response:** The updated deployment object, with `status` set to `stopped` and `stoppedHourlyRate` populated.
:::warning[A stop can outlive the request]
Writing a machine's memory to disk routinely takes longer than the HTTP request allows. A timeout usually means the stop was accepted and is still running. Poll the deployment rather than retrying the stop.
:::
***
#### Start deployment
Start a stopped instance. It comes back on the same disk with the same contents and the same public IP. Only a stopped instance can be started.
**Method:** `POST`
**Path:** `/api/deployments/{deploymentId}/resume`
**Headers:**
* `Authorization`: Bearer ``
**Example request:**
```bash
curl -X POST "https://app.spheron.ai/api/deployments//resume" \
-H "Authorization: Bearer "
```
**Response:** The updated deployment object.
A start can be refused when the provider released the hardware while the instance was stopped and the machine type is currently out of stock. The refusal is not destructive: the instance and its disk are unchanged, so retry when stock returns.
***
#### Restart deployment
Reboot the instance in place. Billing does not change and the instance keeps its status. This is a hard reboot, so anything held in memory is lost. Only a running instance can be restarted.
**Method:** `POST`
**Path:** `/api/deployments/{deploymentId}/restart`
**Headers:**
* `Authorization`: Bearer ``
**Example request:**
```bash
curl -X POST "https://app.spheron.ai/api/deployments//restart" \
-H "Authorization: Bearer "
```
**Response:** The updated deployment object.
***
#### Get restart progress
Report whether a reboot is still in flight, asked of the provider rather than read from a cached record. Poll this while a restart runs.
**Method:** `GET`
**Path:** `/api/deployments/{deploymentId}/reboot-status`
**Headers:**
* `Authorization`: Bearer ``
**Response example:**
```json
{
"restarting": true,
"since": "2026-09-08T10:31:04Z"
}
```
`restarting` is `false` and `since` is absent when no reboot is in flight.
***
#### Lifecycle errors
| Status | Meaning | What to do |
| ------ | --------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------ |
| `400` | The provider, machine type, or region cannot perform this action, or the instance is in the wrong status for it | Read `error` for the specific limit. Do not retry. |
| `403` | The deployment belongs to another user or team | Check the deployment ID. |
| `404` | No deployment with that ID | Check the deployment ID. |
| `409` | Another change is still in flight on this instance, such as a volume change or an earlier restart | Wait a few minutes and retry. |
| `502` | The provider refused the action, or its stopped rate could not be determined | Read `error`. Nothing was changed. |
| `503` | A start was refused, usually because the machine type is out of stock | Retry later. The instance and its data are intact. |
| `504` | The provider is taking longer than usual | The request went through. Poll the deployment instead of retrying. |
Check `supportsPause`, `supportsRestart`, and `pauseUnsupportedReason` on the deployment object before offering a control, so a user is never shown a button that always fails.
### SSH keys
#### Get SSH keys
Get a list of your SSH keys.
**Method:** `GET`
**Path:** `/api/ssh-keys`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------- | :----- | :------- | :----------------------------------- |
| `userId` | string | No | Filter by user ID (must be your own) |
| `teamId` | string | No | Filter by team ID |
**Response example:**
```json
[
{
"id": "ssh_key_id",
"userId": "user_id",
"teamId": "team_id",
"name": "My SSH Key",
"publicKey": "ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAAB...",
"fingerprint": "sha256:abc123def456...",
"createdAt": "2024-01-15T10:30:00Z"
}
]
```
#### Add SSH key
Add a new SSH key.
**Method:** `POST`
**Path:** `/api/ssh-keys`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Request body:**
```json
{
"name": "My SSH Key",
"publicKey": "ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAAB... user@hostname",
"teamId": "team_id_optional"
}
```
**Response example:**
```json
{
"id": "ssh_key_id",
"userId": "user_id",
"teamId": "team_id",
"name": "My SSH Key",
"publicKey": "ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAAB...",
"fingerprint": "sha256:abc123def456...",
"createdAt": "2024-01-15T10:30:00Z"
}
```
#### Get SSH key details
Get a specific SSH key by ID.
**Method:** `GET`
**Path:** `/api/ssh-keys/{id}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--- | :----- | :------- | :---------- |
| `id` | string | Yes | SSH key ID |
**Response example:**
```json
{
"id": "ssh_key_id",
"userId": "user_id",
"teamId": "team_id",
"name": "My SSH Key",
"publicKey": "ssh-rsa AAAAB3NzaC1yc2EAAAADAQABAAAB...",
"fingerprint": "sha256:abc123def456...",
"createdAt": "2024-01-15T10:30:00Z"
}
```
#### Delete SSH key
Delete an SSH key.
**Method:** `DELETE`
**Path:** `/api/ssh-keys/{id}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--- | :----- | :------- | :------------------- |
| `id` | string | Yes | SSH key ID to delete |
**Response example:**
```json
{
"success": true
}
```
### Volumes
Supported providers: `data-crunch`, `sesterce`, `spheron-ai`, and `spheron-es`. Each provider has different rules around size limits, regions, attachment, and mutability. Before creating a volume, call `GET /api/volumes/regions?provider=` to discover valid regions (and for Sesterce, the required `cloudId`).
#### List volumes
List all persistent storage volumes for a team with pagination and status filtering.
**Method:** `GET`
**Path:** `/api/volumes`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------- | :----- | :------- | :------------------------------------------------------------------ |
| `teamId` | string | No | Filter by team ID (defaults to current team) |
| `page` | number | No | Page number (default: 1) |
| `limit` | number | No | Items per page (default: 20) |
| `status` | string | No | Filter by status: 'available', 'attached', 'deleting', or 'deleted' |
**Response example:**
```json
{
"volumes": [{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"name": "my-data-volume",
"userId": "user_id",
"teamId": "team_id",
"providerId": "data-crunch",
"sizeInGb": 100,
"usedCapacityBytes": 52428800000,
"virtualIp": "192.168.100.50",
"attachedToDeploymentIds": ["deployment_id_1"],
"attachedToOrderIds": ["order_123"],
"status": "attached",
"hourlyRate": 0.0137,
"lastPriceUpdate": "2026-02-07T10:30:00Z",
"createdAt": "2026-02-07T10:00:00Z",
"lastAttachedAt": "2026-02-07T10:15:00Z"
}],
"total": 5,
"page": 1,
"limit": 20,
"totalPages": 1
}
```
#### Create volume
Create a new persistent storage volume. Supported providers: `data-crunch`, `sesterce`, `spheron-ai`, `spheron-es`, `spheron-ms`. Optionally attach to an existing deployment during creation for `data-crunch`, `spheron-ai`, and `spheron-es`. Attaching a Spheron ES volume to a running instance restarts the VM. Sesterce and Spheron MS volumes bind at instance launch only, so they cannot be passed a `deploymentId` here and require a `region`.
**Method:** `POST`
**Path:** `/api/volumes`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :------------- | :----- | :---------- | :------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `name` | string | Yes | Volume name (lowercase alphanumeric with hyphens/underscores, max 60 chars) |
| `sizeInGb` | number | Yes | Volume size in GB. Per-provider limits: data-crunch 1-10000, sesterce 50-10000, spheron-ms 1-16000, spheron-es up to 262144 (256 TiB), spheron-ai up to 51200 (the cap can vary by region. Call `GET /api/volumes/regions?provider=spheron-ai` to read minSizeGb/maxSizeGb for the region you intend to use). |
| `provider` | string | Yes | Provider name: `data-crunch`, `sesterce`, `spheron-ai`, `spheron-es`, or `spheron-ms` |
| `region` | string | Conditional | Region for the volume. Required for `data-crunch`, `sesterce`, `spheron-ai`, `spheron-es`, and `spheron-ms`. Spheron MS has no default region, and a volume can only be mounted by an instance in the same region. Use `GET /api/volumes/regions?provider=` to list available options per provider. |
| `cloudId` | string | Conditional | Cloud provider identifier (required for Sesterce only). Use `GET /api/volumes/regions?provider=sesterce` to list available cloud providers. |
| `teamId` | string | No | Team ID (defaults to current team) |
| `deploymentId` | string | No | Deployment ID to attach to during creation. Supported for `data-crunch`, `spheron-ai`, and `spheron-es`. Attaching a Spheron ES volume to a running instance restarts the VM. Not supported for `sesterce` or `spheron-ms`. |
:::info[Size limits by provider]
* `data-crunch`: 1 to 10000 GB
* `sesterce`: 50 to 10000 GB
* `spheron-ai`: up to 51200 GB (varies by region; check `minSizeGb`/`maxSizeGb` from `GET /api/volumes/regions?provider=spheron-ai`)
* `spheron-es`: up to 262144 GB (256 TiB)
* `spheron-ms`: 1 to 16000 GB
:::
**Request body example:**
```json
{
"name": "my-data-volume",
"sizeInGb": 100,
"provider": "data-crunch",
"teamId": "team_id_optional",
"deploymentId": "deployment_id_optional",
"note": "For data-crunch: add 'region' (e.g. 'FIN-01'). For spheron-ai: add 'region' (e.g. 'CANADA-1', 'MON1', 'OSL1'). For sesterce: add 'region' and 'cloudId'. Use GET /api/volumes/regions to discover valid values."
}
```
**Response example:**
```json
{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"name": "my-data-volume",
"userId": "user_id",
"teamId": "team_id",
"providerId": "data-crunch",
"sizeInGb": 100,
"usedCapacityBytes": 0,
"virtualIp": "192.168.100.50",
"attachedToDeploymentIds": [],
"attachedToOrderIds": [],
"status": "available",
"hourlyRate": 0.0137,
"lastPriceUpdate": "2026-02-07T10:00:00Z",
"createdAt": "2026-02-07T10:00:00Z"
}
```
:::info[Provider-specific response fields]
* **Verda**: Response includes the NFS endpoint and pseudopath needed for mounting.
* **Spheron AI**: Response includes `extras.volumeType` (e.g. `Cloud-SSD`).
:::
#### Get volume details
Get volume details with fresh usage data from the provider.
**Method:** `GET`
**Path:** `/api/volumes/{volumeId}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :-------------------- |
| `volumeId` | string | Yes | Volume ID to retrieve |
**Response example:**
```json
{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"name": "my-data-volume",
"userId": "user_id",
"teamId": "team_id",
"providerId": "data-crunch",
"sizeInGb": 100,
"usedCapacityBytes": 52428800000,
"virtualIp": "192.168.100.50",
"attachedToDeploymentIds": ["deployment_id_1"],
"attachedToOrderIds": ["order_123"],
"status": "attached",
"hourlyRate": 0.0137,
"lastPriceUpdate": "2026-02-07T10:00:00Z",
"createdAt": "2026-02-07T10:00:00Z",
"lastAttachedAt": "2026-02-07T10:15:00Z"
}
```
#### Update volume
Update volume properties. Per-provider rules: `data-crunch` and `spheron-es` support size expansion (no shrinking); `spheron-ai` does not support rename or resize. The volume is immutable after creation, so create a new larger volume and migrate your data instead. Sesterce and Spheron MS volumes are immutable and reject all updates after creation.
**Method:** `PATCH`
**Path:** `/api/volumes/{volumeId}`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :------------------ |
| `volumeId` | string | Yes | Volume ID to update |
**Request body example:**
```json
{
"name": "renamed-volume",
"sizeInGb": 200
}
```
:::info[Update rules by provider]
* **Verda**: Supports rename and size expansion. Volumes cannot be shrunk.
* **Spheron ES**: Supports in-place size expansion without recreation or data migration. Volumes cannot be shrunk.
* **Spheron AI**: Does not support rename or resize. Volumes are immutable after creation. To change size, create a new larger volume and migrate data.
* **Spheron MS**: Does not support rename or resize. Size and name are fixed at creation. To change either, create a new volume and migrate data.
* **Sesterce**: Immutable. All update requests are rejected after creation.
All fields are optional. Only specify fields you want to update.
:::
**Response example:**
```json
{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"name": "renamed-volume",
"sizeInGb": 200,
"virtualIp": "192.168.100.50",
"hourlyRate": 0.0274,
"lastPriceUpdate": "2026-02-07T11:00:00Z"
}
```
#### Delete volume
Delete a volume. The volume must not be attached to any active deployments. Terminate the instance first, then delete the volume. This applies to all providers including Sesterce.
**Method:** `DELETE`
**Path:** `/api/volumes/{volumeId}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :------------------ |
| `volumeId` | string | Yes | Volume ID to delete |
**Response example:**
```json
{
"success": true
}
```
#### Attach volume
Attach a volume to a running deployment. Volume and deployment must be from the same provider and region.
:::info[Attachment rules by provider]
* **Verda**: Up to 10 volumes per instance. Each volume can be shared across multiple instances. Volumes and instances must be in the same region (`FIN-01`, `FIN-02`, or `FIN-03`). Cross-region attachment fails silently: the volume appears attached but data is not accessible. Always create the volume and deploy the instance in the same Verda region.
* **Spheron AI**: Up to 10 volumes per instance. Each volume can be attached to only one instance at a time. Hot-detach and re-attach is supported post-launch.
* **Spheron ES**: Multiple volumes per instance. A volume can be mounted on multiple instances simultaneously, read-write or read-only, within the same region. Hot-attach and hot-detach are supported but restart the VM; data is preserved. Attach at deploy time via `volumeIds` to avoid the restart.
* **Sesterce**: 1 volume per instance. Cannot be hot-attached via this endpoint; volumes must be selected at instance creation via `volumeIds` on `POST /api/deployments`. Calling this endpoint for a Sesterce volume returns 400.
* **Spheron MS**: 1 volume per instance, selected at instance creation via `volumeIds` on `POST /api/deployments`. There is no attach or detach for a running instance, so calling this endpoint for a Spheron MS volume returns an error. The volume's region must equal the offer's region, or the deployment is rejected before anything is created. Terminating the instance releases the volume for the next deployment.
:::
**Method:** `POST`
**Path:** `/api/volumes/{volumeId}/attach`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :------------------ |
| `volumeId` | string | Yes | Volume ID to attach |
**Request body example:**
```json
{
"deploymentId": "deployment_id_here"
}
```
**Response example:**
```json
{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"status": "attached",
"virtualIp": "192.168.100.50",
"attachedToDeploymentIds": ["deployment_id_here"],
"attachedToOrderIds": ["order_123"],
"lastAttachedAt": "2026-02-07T12:00:00Z"
}
```
#### Detach volume
Detach a volume from a deployment. Volume data is preserved and the volume can be attached to another deployment. Per-provider rules: Sesterce does not allow manual detach. The volume is released automatically when the instance terminates. Manual detach is only permitted for Sesterce if the deployment is in a terminal state (`failed`, `terminated`, or `terminated-provider`) so a stranded volume can be recovered.
:::info[Detach rules by provider]
**Sesterce** does not allow manual detach. Volumes are released automatically when the instance terminates. Manual detach is only permitted for Sesterce if the deployment is in a terminal state (`failed`, `terminated`, or `terminated-provider`) so a stranded volume can be recovered.
:::
**Method:** `POST`
**Path:** `/api/volumes/{volumeId}/detach`
**Headers:**
* `Authorization`: Bearer ``
* `Content-Type`: application/json
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :------------------ |
| `volumeId` | string | Yes | Volume ID to detach |
**Request body example:**
```json
{
"deploymentId": "deployment_id_here"
}
```
**Response example:**
```json
{
"id": "volume_internal_id",
"volumeId": "vol_abc123",
"status": "available",
"virtualIp": "192.168.100.50",
"attachedToDeploymentIds": [],
"attachedToOrderIds": [],
"lastDetachedAt": "2026-02-07T13:00:00Z"
}
```
#### Get volume pricing
Get storage pricing per GB per hour for a provider. The rate can vary by region. Pass `region` to get the rate for the specific region you intend to use; omitting it returns the provider's default rate. For Sesterce, also pass `cloudId` alongside `region` (Sesterce pricing varies significantly by AZ). Note: `GET /api/volumes/regions` already embeds `hourlyRatePerGb` on each region entry, so this endpoint is mainly useful when you don't need the full region list (e.g. lightweight provider-level price lookups or Sesterce per-cloudId rate refreshes).
**Method:** `GET`
**Path:** `/api/volumes/pricing`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `provider` | string | No | Provider name: `data-crunch`, `sesterce`, `spheron-ai`, or `spheron-es`. Pass it explicitly to select the provider whose regions you want. |
| `cloudId` | string | No | Cloud provider identifier (Sesterce only). Use alongside `region` to fetch the rate for a specific AZ. |
| `region` | string | No | Region identifier. Pass this when the provider's rate varies by region (e.g. `spheron-ai`). For Sesterce: use alongside `cloudId` for AZ-specific rate. |
**Response example:**
```json
{
"provider": "data-crunch",
"hourlyRatePerGb": 0.000137
}
```
#### Get volume regions
Get available regions and volume tiers for a given storage provider. Required before creating `data-crunch`, `sesterce`, `spheron-ai`, or `spheron-es` volumes to pick a valid region (and cloud) value. Each region entry includes `minSizeGb`, `maxSizeGb`, and `hourlyRatePerGb`, so if you're already listing regions you don't need to also call `GET /api/volumes/pricing`. `hasGpuOffers` indicates whether any GPU offers exist in that region; the top-level `hasAnyOffers` flag is true when the provider has any live GPU offers at all.
**Method:** `GET`
**Path:** `/api/volumes/regions`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :--------- | :----- | :------- | :---------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `provider` | string | No | Provider name: `data-crunch`, `sesterce`, `spheron-ai`, or `spheron-es`. Pass it explicitly to select the provider whose regions you want. Unknown values return a 400. |
All providers return the same shape. Sesterce entries also include `cloudId` and `cloudName`: pass both `region` (the `id`) and `cloudId` when creating a Sesterce volume. `hasGpuOffers` is per region; `hasAnyOffers` is true if at least one region has offers.
**Response example (`data-crunch`):**
```json
{
"hasAnyOffers": true,
"regions": [
{ "id": "Texas", "name": "Dallas, TX", "country_code": "US", "types": ["NFS"], "hasGpuOffers": true, "minSizeGb": 1, "maxSizeGb": 64000, "hourlyRatePerGb": 0.000137 }
]
}
```
**Response example (`?provider=data-crunch`):**
```json
{
"hasAnyOffers": true,
"regions": [
{ "id": "FIN-01", "name": "Finland 1", "country_code": "FI", "types": ["NVMe_Shared"], "hasGpuOffers": true, "minSizeGb": 1, "maxSizeGb": 10000, "hourlyRatePerGb": 0.000196 },
{ "id": "FIN-02", "name": "Finland 2", "country_code": "FI", "types": ["NVMe_Shared"], "hasGpuOffers": true, "minSizeGb": 1, "maxSizeGb": 10000, "hourlyRatePerGb": 0.000196 },
{ "id": "FIN-03", "name": "Finland 3", "country_code": "FI", "types": ["NVMe_Shared"], "hasGpuOffers": false, "minSizeGb": 1, "maxSizeGb": 10000, "hourlyRatePerGb": 0.000196 }
]
}
```
**Response example (`?provider=sesterce`):**
Sesterce entries include `cloudId` and `cloudName`. Pass both `region` (the `id`) and `cloudId` when creating a Sesterce volume.
```json
{
"hasAnyOffers": true,
"regions": [
{ "id": "eu-west-1", "name": "EU West 1", "cloudId": "668f9d8df664e3c028ce5de9", "cloudName": "Sesterce EU", "types": ["block-storage"], "hasGpuOffers": true, "minSizeGb": 50, "maxSizeGb": 10000, "hourlyRatePerGb": 0.000150 },
{ "id": "us-east-1", "name": "US East 1", "cloudId": "77af9d8df664e3c028ce5ef0", "cloudName": "Sesterce US", "types": ["block-storage"], "hasGpuOffers": true, "minSizeGb": 50, "maxSizeGb": 10000, "hourlyRatePerGb": 0.000175 }
]
}
```
**Response example (`?provider=spheron-ai`):**
Spheron AI exposes several regions; capacity and rate can vary by region and are returned per region in this response.
```json
{
"hasAnyOffers": true,
"regions": [
{ "id": "CANADA-1", "name": "Canada 1", "types": ["Cloud-SSD"], "hasGpuOffers": true, "minSizeGb": 1, "maxSizeGb": 40960, "hourlyRatePerGb": 0.000109 },
{ "id": "NORWAY-1", "name": "Norway 1", "types": ["Cloud-SSD"], "hasGpuOffers": false, "minSizeGb": 1, "maxSizeGb": 40960, "hourlyRatePerGb": 0.000109 },
{ "id": "MON1", "name": "Montreal 1", "country_code": "CA", "types": ["NVME"], "hasGpuOffers": true, "minSizeGb": 1, "maxSizeGb": 51200, "hourlyRatePerGb": 0.000168 },
{ "id": "OSL1", "name": "Oslo 1", "country_code": "NO", "types": ["NVME"], "hasGpuOffers": false, "minSizeGb": 1, "maxSizeGb": 51200, "hourlyRatePerGb": 0.000168 }
]
}
```
### Teams
#### Get balance
Get account balance. Returns all teams by default.
**Method:** `GET`
**Path:** `/api/balance`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------- | :------ | :------- | :------------------------------------------------------ |
| `teamId` | string | No | Get balance for a specific team ID only |
| `all` | boolean | No | Set to 'false' to get current team only (default: true) |
**Response example:**
```json
{
"teams": [
{
"teamId": "team_1",
"teamName": "My Personal Team",
"balance": 25.50,
"isCurrentTeam": true,
"role": "owner"
},
{
"teamId": "team_2",
"teamName": "Company Team",
"balance": 150.75,
"isCurrentTeam": false,
"role": "admin"
}
],
"currency": "USD"
}
```
#### List teams
List every team the authenticated caller belongs to, with each team's members, plan, owner, and real-time balance. If the caller has no team yet, a default personal team is created on first call and returned in the response, so this endpoint is safe to call after sign-up without a separate bootstrap step. Use the team `id` field when passing `teamId` into deployment, volume, or balance endpoints.
**Method:** `GET`
**Path:** `/api/teams`
**Headers:**
* `Authorization`: Bearer ``
**Response example:**
```json
[
{
"id": "team_id_1",
"name": "My Personal Team",
"slug": "my-personal-team-1707307200000",
"ownerId": "user_id",
"balance": 25.50,
"members": [
{
"userId": "user_id",
"email": "owner@example.com",
"name": "Owner Name",
"role": "owner",
"joinedAt": "2024-01-15T10:30:00Z"
}
],
"createdAt": "2024-01-15T10:30:00Z"
}
]
```
:::info[Response fields]
* `balance` is computed in real time and reflects the team's current USD credit balance after pending deductions.
* `members[].role` is one of `owner`, `admin`, or `member`.
:::
#### Get team details
Fetch a single team by ID. The authenticated caller must be a member of the team (owner, admin, or member); otherwise the request is rejected with `403`. Returns the same team shape that `GET /api/teams` returns for entries in its array, with one exception: the stored `balance` is returned as-is and is NOT recomputed in real time. For an up-to-date balance, use `GET /api/balance?teamId=` instead.
**Method:** `GET`
**Path:** `/api/teams/details/{teamId}`
**Headers:**
* `Authorization`: Bearer ``
**Parameters:**
| Name | Type | Required | Description |
| :------- | :----- | :------- | :---------------------------------------------- |
| `teamId` | string | Yes | Team ID to fetch. Obtain from `GET /api/teams`. |
**Response example:**
```json
{
"id": "team_id",
"name": "My Personal Team",
"slug": "my-personal-team-1707307200000",
"ownerId": "user_id",
"balance": 25.50,
"members": [
{
"userId": "user_id",
"email": "owner@example.com",
"name": "Owner Name",
"role": "owner",
"joinedAt": "2024-01-15T10:30:00Z"
}
],
"createdAt": "2024-01-15T10:30:00Z"
}
```
### Error reference
All error responses follow this format:
```json
{
"error": "Error message",
"code": "ERROR_CODE",
"details": {}
}
```
#### Common HTTP status codes
**200 OK**: Request succeeded
**201 Created**: Resource created successfully
**400 Bad Request**: Invalid parameters or request body
```json
{
"error": "Missing required field: gpuType",
"code": "VALIDATION_ERROR"
}
```
**401 Unauthorized**: Invalid or missing API key
```json
{
"error": "Invalid API key",
"code": "UNAUTHORIZED"
}
```
**403 Forbidden**: Insufficient permissions
```json
{
"error": "Insufficient permissions to access this resource",
"code": "FORBIDDEN"
}
```
**404 Not Found**: Resource does not exist
```json
{
"error": "Deployment not found",
"code": "NOT_FOUND"
}
```
**429 Too Many Requests**: Rate limit exceeded
```json
{
"error": "Rate limit exceeded. Try again in 15 minutes",
"code": "RATE_LIMIT_EXCEEDED"
}
```
**500 Internal Server Error**: Server error
```json
{
"error": "Internal server error",
"code": "INTERNAL_ERROR"
}
```
### Status values
#### Deployment statuses
**deploying**: Instance is being provisioned. Usually takes 30-60 seconds.
**running**: Instance is active and accessible via SSH.
**stopped**: Instance is parked. The GPU is released, the disk and its contents are preserved, and billing runs at `stoppedHourlyRate`. A stopped instance is part of the live set, so `?status=active` includes it. Start it with the [resume endpoint](#start-deployment).
**failed**: Deployment failed. Check error details in the deployment object.
**terminated**: Instance has been terminated by the user and is no longer accessible.
**terminated-provider**: Instance was reclaimed or stopped by the provider (e.g., a Spot instance was interrupted). No further action is needed.
#### Status lifecycle
```
deploying → running ⇄ stopped → terminated
↓ ↓
failed terminated-provider
```
**Transitions:**
* `deploying` to `running`: Successful deployment
* `deploying` to `failed`: Deployment error
* `running` to `stopped`: Stopped by the user, or parked by the provider
* `stopped` to `running`: Started again by the user
* `running` or `stopped` to `terminated`: Manual termination by user
* `running` to `terminated-provider`: Provider reclaimed the instance (Spot interruption)
* Any status can transition to `failed` if errors occur
A restart does not change the status. The instance stays `running` throughout, and [reboot-status](#get-restart-progress) reports whether the reboot is still in flight.
### Rate limits
All API endpoints are subject to rate limiting to ensure fair usage and system stability. Rate limits are tracked per IP address for unauthenticated requests and per user (Firebase UID) for authenticated requests.
#### Rate limit headers
All responses include these headers:
```http
X-RateLimit-Limit: 250
X-RateLimit-Remaining: 245
X-RateLimit-Reset: 2025-12-29T14:00:00.000Z
```
#### Rate limits by endpoint
##### GPU offers and providers
```
GET /api/providers
GET /api/gpu-offers
```
* **Limit**: 250 requests per 15 minutes
* **Scope**: Per IP address
* **Authentication**: Optional (authenticated users see team discounts)
##### Deployments
```
POST /api/deployments
```
* **Default limit**: 10 deployments per 15 minutes
* **Scope**: Per authenticated user
* **Custom limits**: Admins can increase limits for enterprise users
* **Authentication**: Required
```
GET /api/deployments
GET /api/deployments/{deploymentId}
PATCH /api/deployments/{deploymentId}
DELETE /api/deployments/{deploymentId}
GET /api/deployments/{deploymentId}/can-terminate
```
* **Limit**: 250 requests per 15 minutes
* **Scope**: Per IP address
* **Authentication**: Required
##### SSH keys
```
GET /api/ssh-keys
GET /api/ssh-keys/{id}
POST /api/ssh-keys
DELETE /api/ssh-keys/{id}
```
* **Limit**: 250 requests per 15 minutes
* **Scope**: Per IP address
* **Authentication**: Required
##### Balance and teams
```
GET /api/balance
GET /api/teams
GET /api/teams/details/{teamId}
```
* **Limit**: 250 requests per 15 minutes
* **Scope**: Per IP address
* **Authentication**: Required
#### Rate limit response
When the rate limit is exceeded (HTTP 429):
```json
{
"error": "Too many requests",
"message": "Too many requests from this IP, please try again later.",
"retryAfter": 900
}
```
#### Custom rate limits (enterprise)
Enterprise customers can request custom deployment creation limits:
* Contact: [info@spheron.ai](mailto\:info@spheron.ai)
* Configurable: Deployment creation limit (default: 10 per 15 min)
* Options: Custom limit or unlimited deployments
#### Quick reference
| Endpoint | Rate Limit | Window | Scope | Custom Limits |
| ----------------------- | ------------ | ------ | ----- | ------------- |
| General API | 250 requests | 15 min | IP | No |
| Deployment Creation | 10 requests | 15 min | User | Yes |
| All Other API Endpoints | 250 requests | 15 min | IP | No |
### Security
#### Best practices
Treat API keys like passwords:
* Never expose keys in client-side code
* Do not commit keys to version control
* Use environment variables for credentials
* Rotate keys regularly
Key management:
* Generate keys from [dashboard settings](https://app.spheron.ai/settings)
* Set expiry dates for keys
* Revoke compromised keys immediately
* Use separate keys for different environments
Connection security:
* All API requests must use HTTPS
* Verify SSL certificates
* Do not disable certificate validation
For comprehensive security guidelines, see [Security best practices](/security).
### Common workflows
#### Complete deployment flow
```bash
# 1. Check available GPU offers
curl -H "Authorization: Bearer " \
"https://app.spheron.ai/api/gpu-offers?search=rtx-4090&limit=5"
# 2. Add SSH key (if not already added)
curl -X POST "https://app.spheron.ai/api/ssh-keys" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{"name": "My Key", "publicKey": "ssh-rsa AAA..."}'
# 3. Deploy instance
curl -X POST "https://app.spheron.ai/api/deployments" \
-H "Authorization: Bearer " \
-H "Content-Type: application/json" \
-d '{
"provider": "spheron-ai",
"offerId": "rtx-4090-spheron-ai-1",
"gpuType": "rtx-4090",
"gpuCount": 1,
"region": "us-east-1",
"operatingSystem": "ubuntu-22.04",
"instanceType": "DEDICATED",
"sshKeyId": "your_ssh_key_id"
}'
# 4. Monitor deployment status
curl -H "Authorization: Bearer " \
"https://app.spheron.ai/api/deployments/deployment_id"
# 5. Terminate when done
curl -X DELETE "https://app.spheron.ai/api/deployments/deployment_id" \
-H "Authorization: Bearer "
```
### What's next
* [Getting Started](/getting-started): Account setup and first deployment
* [Security best practices](/security): API key management and security
* [Connecting to instances](/connecting): SSH and networking setup
* [Billing](/billing): Credits and usage monitoring
## API skill for AI agents
This page gives you a ready-made skill file that teaches an AI agent how to use the [Spheron GPU API](/api-reference). Hand it to Claude or ChatGPT, and the agent understands the full deployment flow: which endpoint to call, in what order, how each parameter works, and how to handle errors, provider rules, and instance lifecycles.
The skill is one self-contained Markdown file. It works as a Claude Agent Skill, a ChatGPT custom GPT instruction set, or a system prompt for any LLM that can make HTTP requests.
Download spheron-gpu-api-skill.md
### What the skill teaches the agent
* The full deploy flow: providers, GPU offers, SSH keys, deployment, status polling, stopping, restarting, and termination.
* A decision framework that maps a user request to the correct endpoint and call order.
* How every deployment parameter works, including which fields must all come from the same offer.
* How to deploy a [CPU Node](/concepts/cpu-nodes) when the workload never touches a GPU, and when to suggest one.
* Provider-specific rules for volumes and instance types.
* When an instance can be [stopped or restarted](/concepts/instance-lifecycle), how to quote the stopped rate first, and why a restart is never emulated with a stop and a start.
* Status values, the deployment lifecycle, error codes, and rate limits.
* That an API key is required, and that access comes from the [dashboard](https://app.spheron.ai/settings) or by contacting [info@spheron.ai](mailto\:info@spheron.ai).
### Prerequisites
* A Spheron API key. Generate one from your [dashboard settings](https://app.spheron.ai/settings). If you do not have API access yet, request it from [info@spheron.ai](mailto\:info@spheron.ai).
* An AI agent that can make HTTPS requests, or that you supply request output to manually.
:::warning
The skill instructs the agent to spend real money on your account when it deploys instances or creates volumes. Keep confirmation steps enabled and review any deploy or terminate action before approving it.
:::
### Use the skill with Claude
Choose the option that matches how you run Claude.
#### Claude Code or the Claude Agent SDK
1. Download spheron-gpu-api-skill.md.
2. Create a skill folder and rename the file to `SKILL.md` inside it:
```bash
mkdir -p ~/.claude/skills/spheron-gpu-api
mv spheron-gpu-api-skill.md ~/.claude/skills/spheron-gpu-api/SKILL.md
```
3. Start Claude Code. The skill loads automatically when your request matches its description (renting or managing GPUs on Spheron).
4. Save your API key once on your local system so the agent reads it automatically on every run instead of asking again:
```bash
# Persist the key for future shells
echo 'export SPHERON_API_KEY=""' >> ~/.zshrc
```
The skill instructs the agent to read `SPHERON_API_KEY` (or a local `~/.spheron/credentials` file) before each authenticated call.
#### Claude apps and Projects
1. Download the file.
2. Add it to a Project's knowledge, or paste its contents into the custom instructions or the start of a conversation.
3. Tell Claude your goal, for example: "Deploy a single H100 on Spheron and give me the SSH command." Provide your API key when asked.
### Use the skill with ChatGPT
#### Custom GPT
1. Open the GPT builder and go to Configure.
2. Open `spheron-gpu-api-skill.md`, copy its full contents, and paste them into the Instructions field.
3. Optionally enable Actions and import the API so the GPT can call endpoints directly. Add your API key as a Bearer token in the authentication settings.
#### Standard chat
1. Paste the contents of the file as your first message, or save it as a custom instruction.
2. Add your goal and your API key in the same conversation.
### Use the skill with any LLM agent
The file is plain Markdown with no tool-specific syntax. Load it as the system prompt for any agent framework that can issue HTTPS requests to `https://app.spheron.ai`. The agent then follows the decision framework and parameter rules in the file.
### Keep the skill current
The skill mirrors the [API reference](/api-reference). When the API changes, download the file again so your agent uses the latest endpoints, parameters, and provider rules.
### What's next
* [API reference](/api-reference): the complete endpoint documentation the skill is based on.
* [Getting started](/getting-started): account setup and your first deployment.
* [Security best practices](/security): how to store and rotate your API key safely.
* [Instance types](/concepts/instance-types): the difference between SPOT, DEDICATED, and CLUSTER.
* [CPU nodes](/concepts/cpu-nodes): CPU-only instances the skill can deploy with `gpuType: "CPU"`.
* [Instance lifecycle](/concepts/instance-lifecycle): the stop, start, and restart endpoints the skill calls.
## Billing
Manage credits, monitor usage, and track spending for GPU instances.
### Credit system
**How it works:**
* 1 Credit = $1 USD of GPU usage
* Credits never expire
* Credits are shared across team members
* Pay-per-second billing: credits are deducted continuously based on your hourly rate, so you pay only for the exact time your instance runs
* Your hourly rate tracks the provider's current price for the whole life of an instance. If the underlying price moves, charges from that point onward use the new rate. Usage already billed is never recalculated, and any discount on your account continues to apply
**Requirements:**
* Minimum deposit: $15
* Instant credit delivery
### Dashboard overview
The Overview section shows your balance and live GPU usage at a glance.
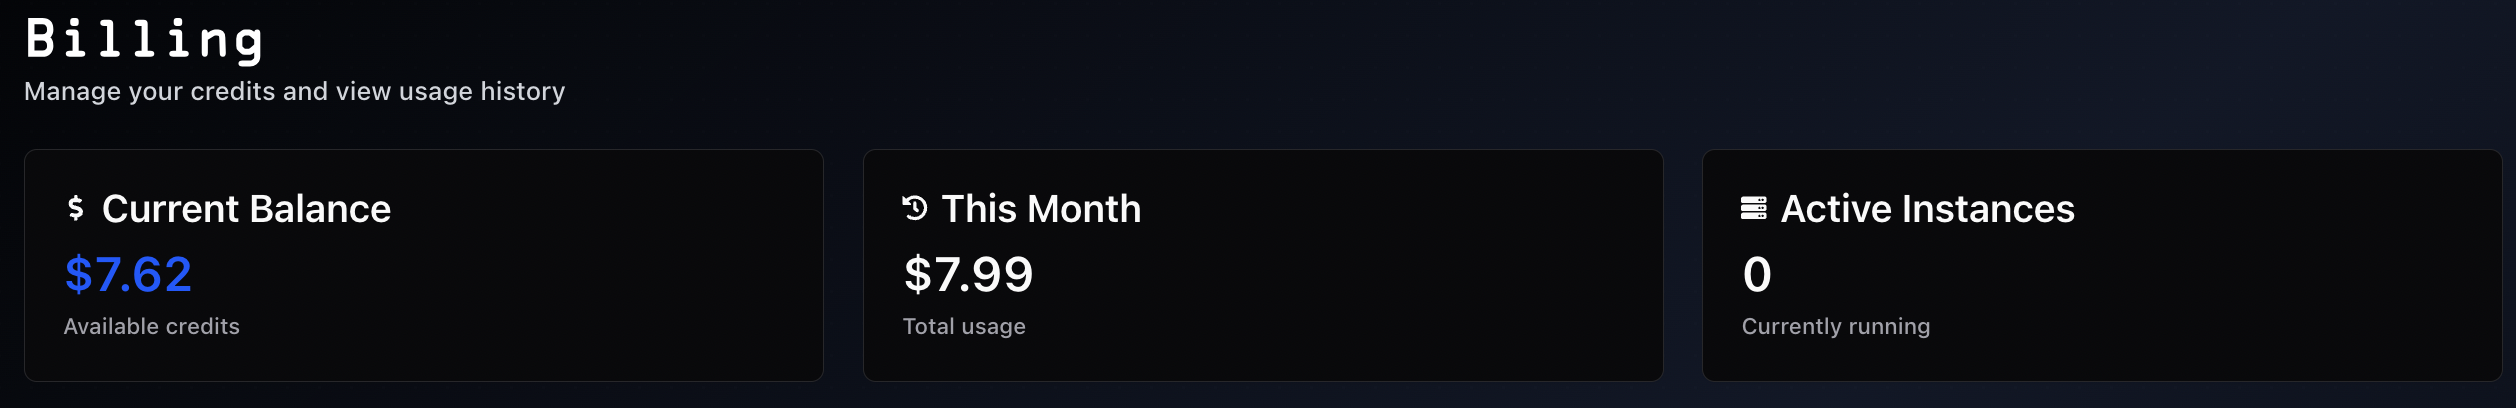
**Cards:**
* **Available Balance**: Credits ready to spend on GPU deployments. An account-status indicator (for example, "Account in good standing") sits below the value.
* **Total Spent**: All-time GPU and storage spend for the team.
* **Active**: Number of GPU instances currently running.
* **Burn Rate**: Current hourly cost across all running instances.
* **Est. Runtime**: Estimated time remaining at the current burn rate. Shows **N/A** when there is no active spending.
### Adding credits
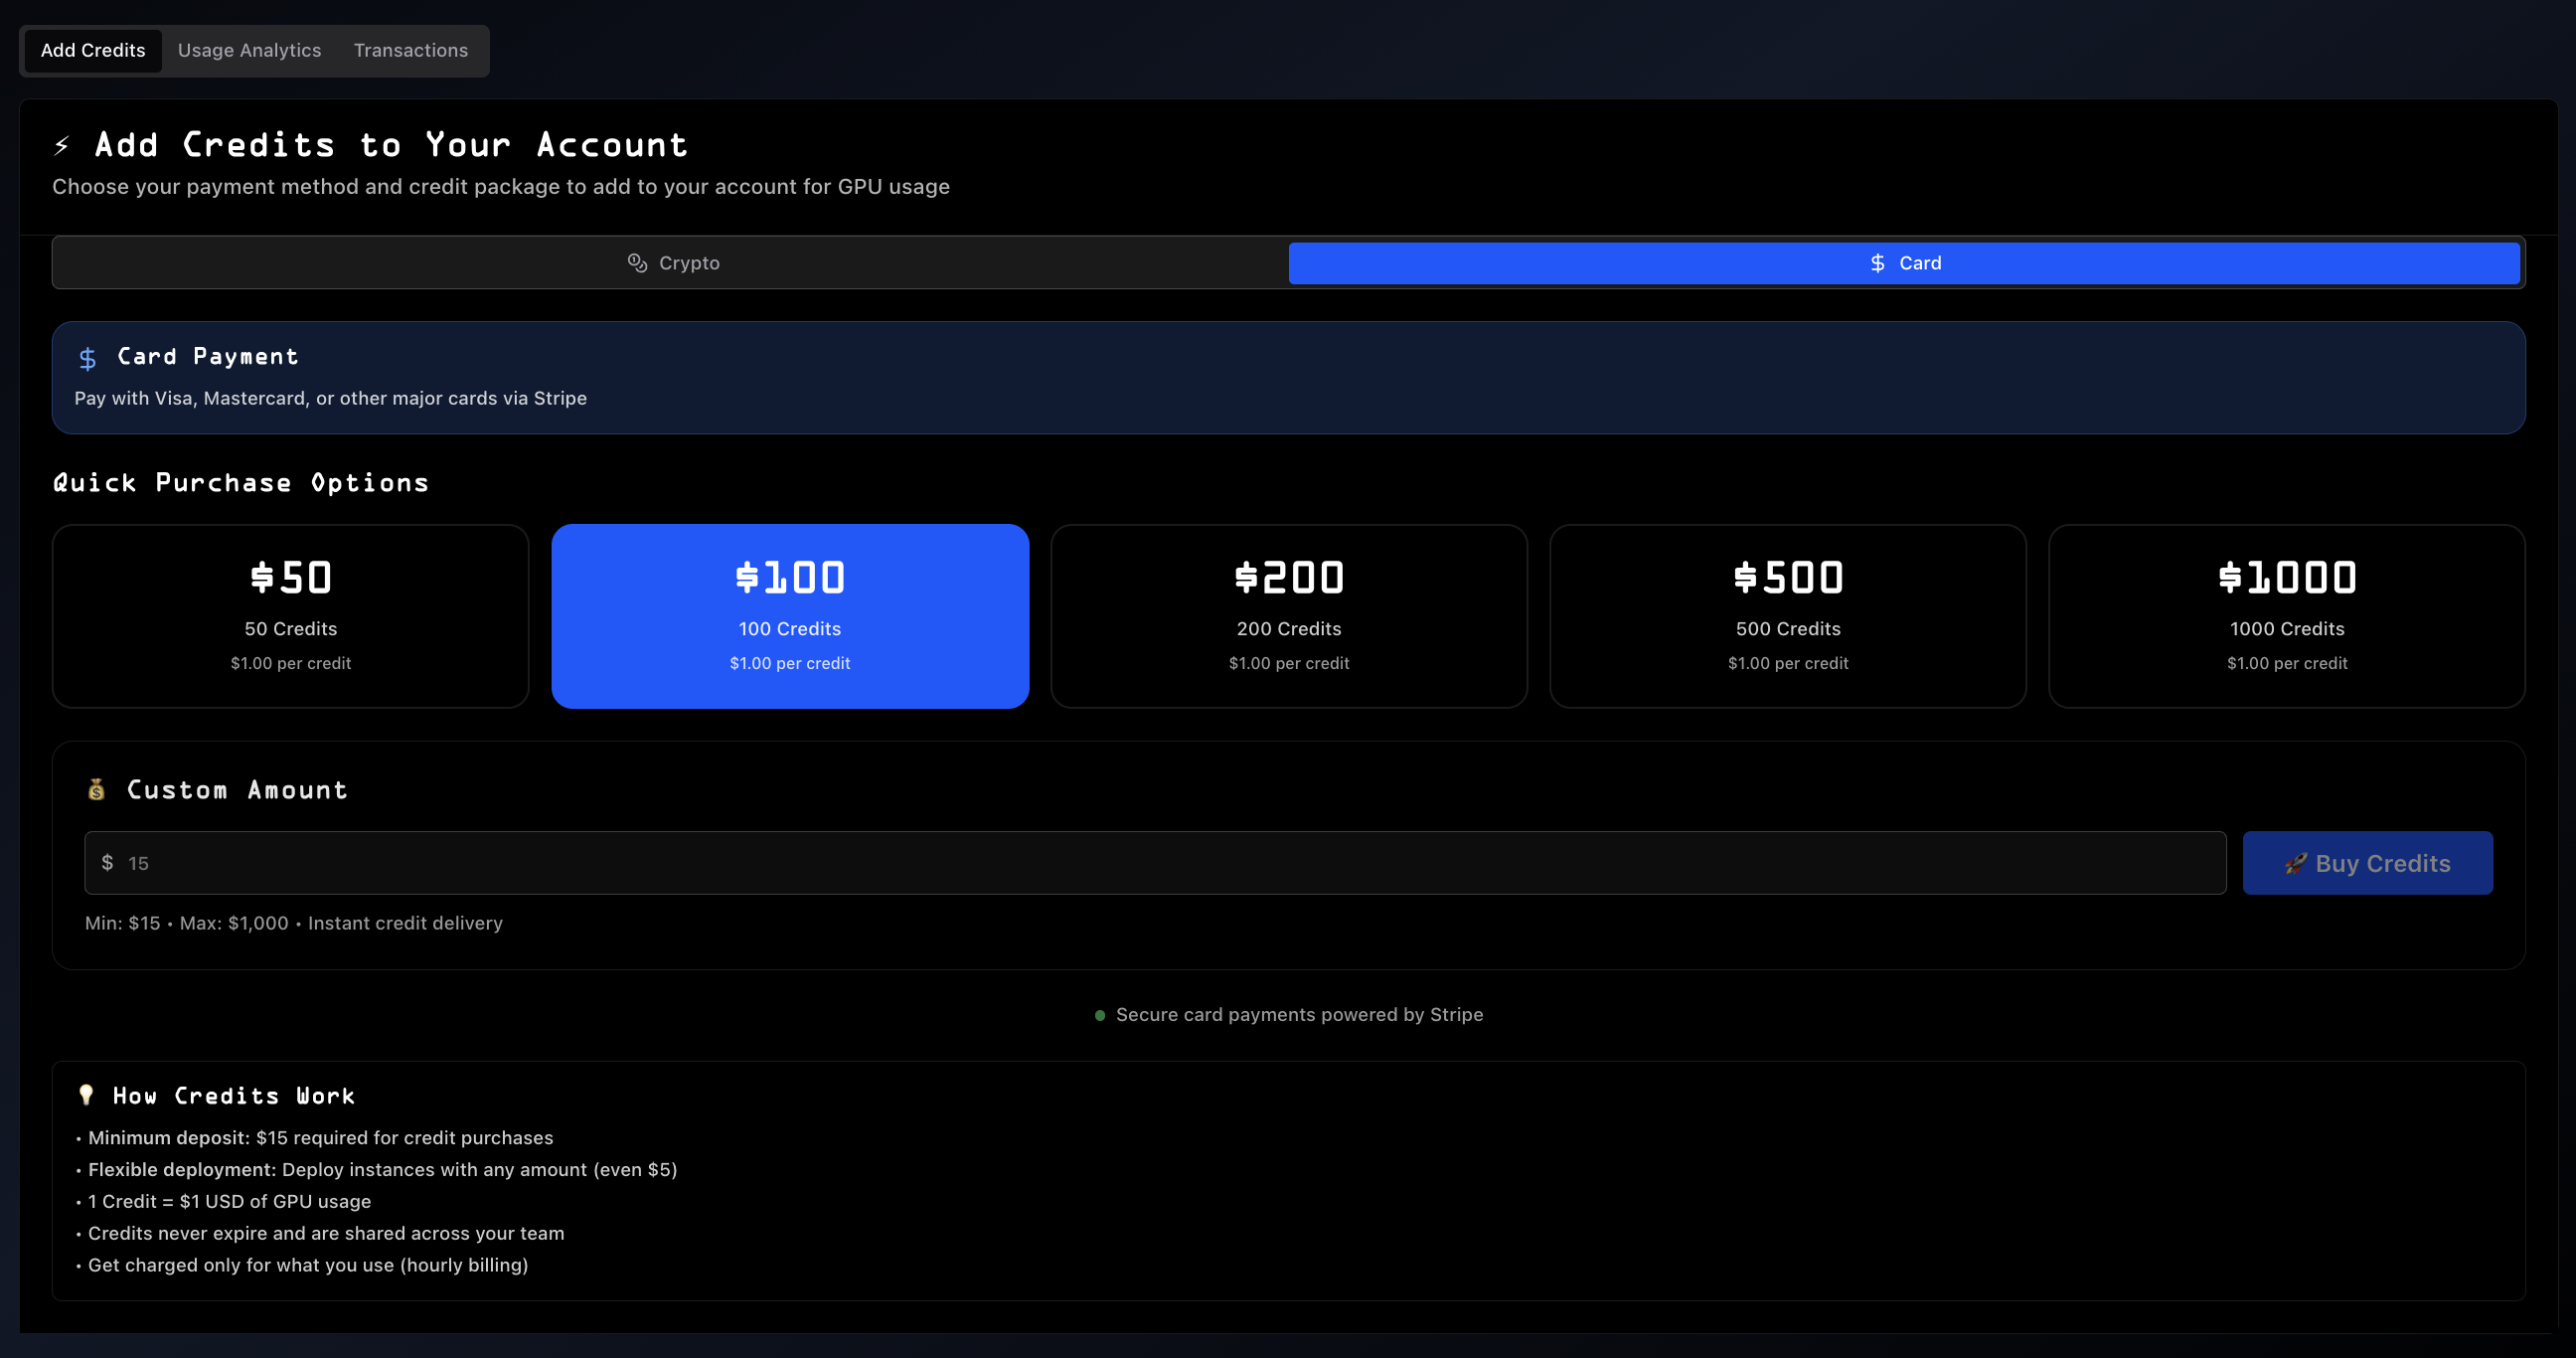
#### Payment methods
**Card payment** (powered by Stripe)
* Visa, Mastercard, and major cards accepted
* Secure processing via Stripe
* Instant delivery
**Stables payment** (powered by CopperX)
* USDC and USDT accepted
* Blockchain-secured transactions
* Instant delivery
#### Preset packages
| Amount | Credits | Rate |
| -------- | ------- | ---------------------------- |
| **$100** | **100** | **$1.00 / credit** (Popular) |
| $1,000 | 1,000 | $1.00 / credit |
| $5,000 | 5,000 | $1.00 / credit |
#### Custom amount
Enter any amount between $15 (minimum) and $5,000 (maximum) for instant delivery.
### Usage analytics
Track deployments, GPU spend, and volume costs in one place.
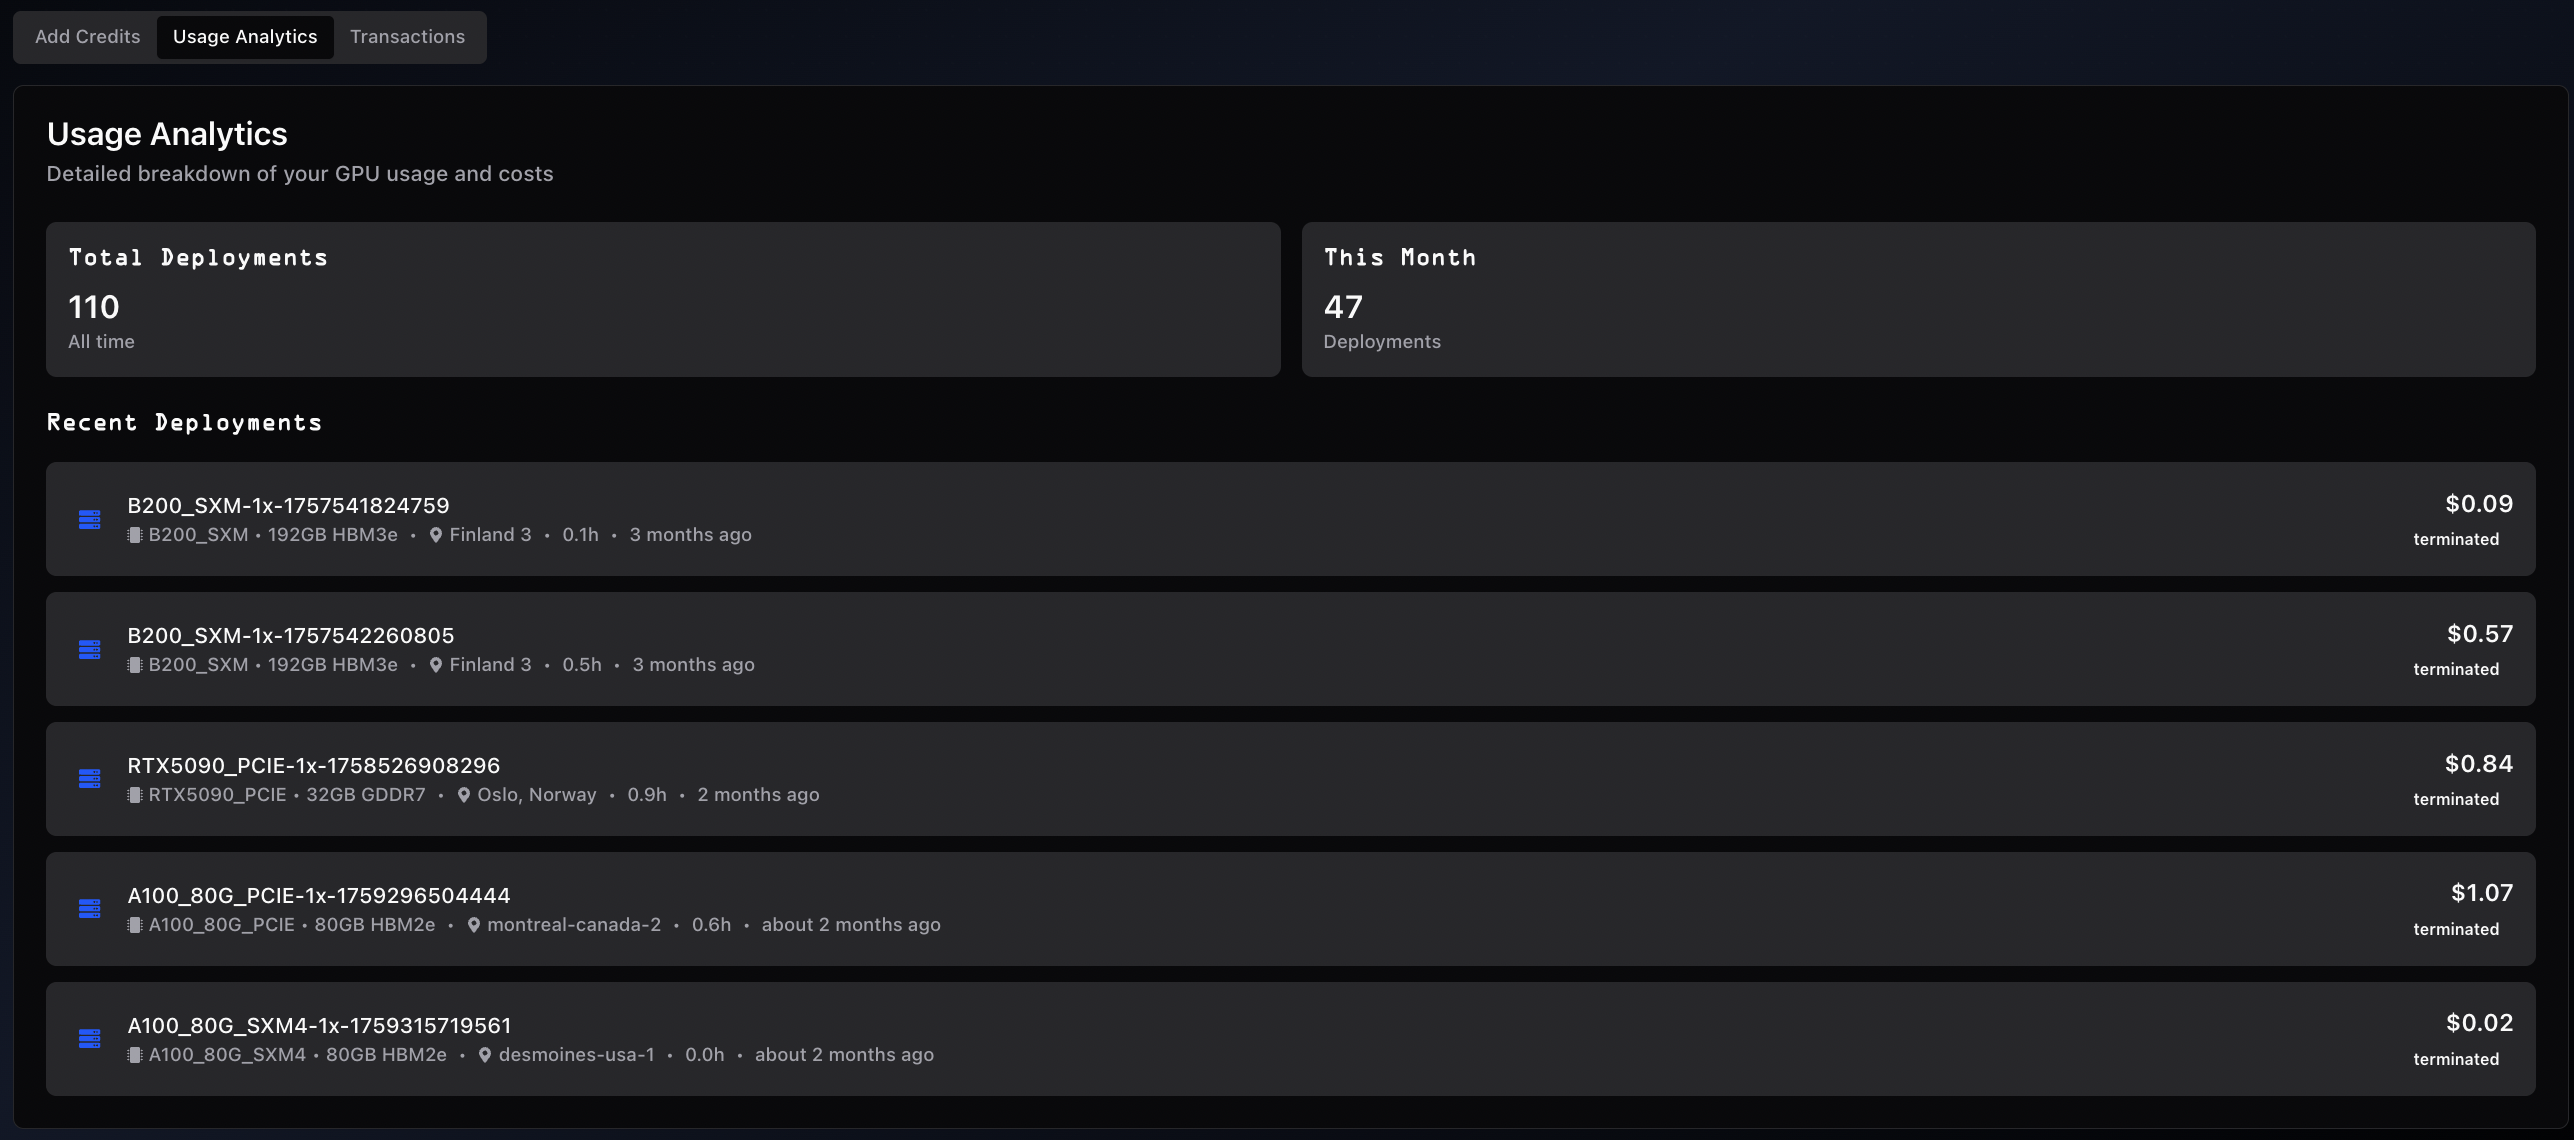
A time-range selector at the top of the panel (default: **All Time**) filters every metric and the deployment list below.
**Summary metrics:**
* **Deployments**: Total deployments in the selected range
* **GPU Spend**: GPU compute spend in the selected range (also shows the billed-instance count)
* **Active Volumes**: Currently active persistent volumes (also shows the total volumes ever created)
* **Volume Cost**: Accumulated storage spend in the selected range
**Per-deployment details:**
* GPU model, count, VRAM, and hourly rate (for example, `1x L40S PCIe - 48GB GDDR6 - $1.07/hr`)
* Instance ID
* Provider and region
* Duration and timestamp
* Total cost and status (active or terminated)
Use the analytics view for:
* Cost analysis by GPU type
* Spending pattern review across time ranges
* Project cost tracking
* Usage optimization
### Billing for a stopped instance
Stopping an instance keeps it and its disk while releasing the GPU. You are billed for the disk, not the GPU, for as long as it stays stopped.
* The stopped rate comes from the provider and covers the retained disk, plus the public IP where the provider charges for one.
* Any discount on your account applies to the stopped rate exactly as it does to the running rate.
* Charges run on a five minute cycle. Stopping and starting both settle the elapsed time at the outgoing rate first, so a stop landing mid-cycle is not billed at the wrong rate for that slice.
* Usage figures, invoices, and the deployment list pick stopped periods up with no change.
* When a provider parks your machine from its side, you are charged the stopped rate for that period, not the running rate.
Stopped rates are shown to four decimal places. At two decimal places most of them round to $0.00 and read as free, which they are not.
:::warning[Stopping is not the same as terminating]
A team that runs out of credit has every instance destroyed, stopped ones included. Stopping reduces the burn rate; it does not protect an instance indefinitely. Terminate an instance you have finished with. See [Instance lifecycle](/concepts/instance-lifecycle) for which providers support stopping.
:::
### Deposit history
View all credit deposits and top-ups for your team.
A time-range selector at the top (default: **All Time**) filters the summary metrics and the deposit list.
**Summary metrics:**
* **Total Deposited**: All-time deposit amount across the team
* **Avg Deposit**: Average value across completed deposits
* **Total Deposits**: Count of all deposits with a completed-vs-pending breakdown
**Per-deposit details:**
* Status badge: **Pending** or **Completed**
* Date and time of the deposit
* Source label: `Custom $X`, a preset package (e.g., `$100 Package`), or `Auto Top-Up`
* Payment provider: **Stripe** (card) or **CopperX** (stables)
* Amount in USD and the credits awarded
* **Receipt** button on completed deposits for downloading the invoice
A deposit that gets stuck pending because a confirmation was delayed or missed is detected and credited to your balance automatically, with no need to contact support. Deposits that were genuinely abandoned or expired are cleared from the list instead of lingering as pending.
Use the deposit history for:
* Payment verification
* Expense tracking
* Receipt downloads for accounting records
### Low-balance warnings
Warnings are based on how much runtime your balance buys at your current burn rate, not on a fixed dollar figure. The same alert means the same thing whether you run one small GPU or a large cluster.
Spheron emails you as your estimated remaining runtime crosses each of these thresholds:
| Band | Thresholds |
| ------- | --------------------- |
| Hours | 12 h, 6 h, 3 h, 1 h |
| Minutes | 30 min, 15 min, 5 min |
A balance-exhaustion notice follows if the balance actually runs out. These emails are always sent and are not affected by the marketing toggle in [User settings](/user-settings#notifications).
Enable [auto top-up](#auto-top-up) to recharge automatically instead of relying on the warnings.
### Auto top-up
Auto top-up prevents unexpected instance termination by automatically recharging your account when credits run low.
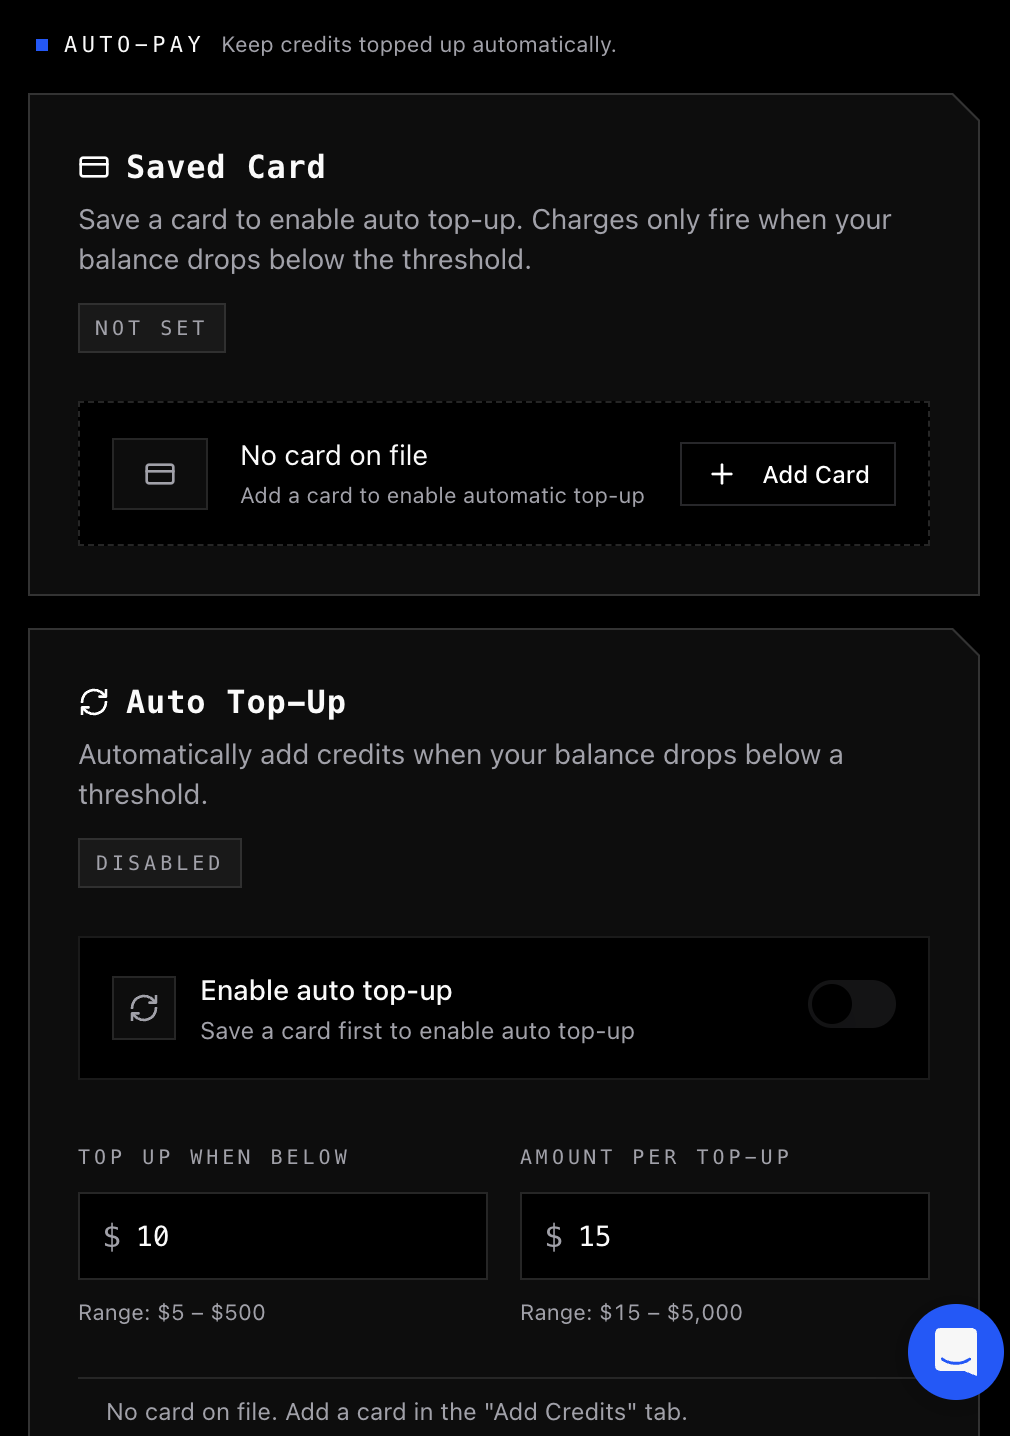
**Configure auto top-up:**
1. Add a payment card from the **Add Credits** tab. Once saved, it appears in the **Saved Card** panel under Auto-Pay.
2. Set **Top up when below** between $5 and $500 (for example, $10)
3. Set **Amount per top-up** between $15 and $5,000 (for example, $50)
4. Toggle **Enable auto top-up** on
**How charges work:**
* When your balance falls below the threshold, the platform charges your saved card for the top-up amount.
* A 5-minute cooldown between charges prevents duplicate billing.
* If a charge fails, the platform disables auto top-up and emails you a notification.
* Auto top-up charges appear in Deposit History labeled **"Auto Top-Up"**.
For long training runs, auto top-up prevents instance termination due to insufficient credits mid-job.
### Billing details
Add your company name, registered address, and tax ID to your account so they appear on every future card-payment invoice automatically. Stripe stores this information once and applies it to all subsequent charges.
:::info[Card payments only]
Billing details apply to card payments processed by Stripe. Stables payments (USDC/USDT via CopperX) are settled on-chain and do not generate invoices through this flow.
:::
**Use billing details for:**
* Issuing invoices with proper legal entity information for accounting and procurement
* Tax compliance: VAT, GST, EIN, or other regional tax identifiers
* Expense reimbursement and audit trails that require the registered business name and address
#### Configure billing details
:::steps
##### Open the Billing page
In the Spheron dashboard, navigate to **Billing**. Scroll to the **Billing Details** card (step 03 in the billing settings).
##### Open the Stripe billing portal
Click **Manage on Stripe**. Stripe hosts the form and stores the data on its own systems; Spheron does not store company billing details directly.
##### Enter your business information
Fill in the four fields:
| Field | Description |
| -------- | ------------------------------------------------- |
| Company | Legal entity name shown on the invoice |
| Address | Registered business address |
| Tax ID | VAT, GST, EIN, or other applicable tax identifier |
| Invoices | Email address that receives each invoice |
##### Save the changes
Save in Stripe. The portal links these details to your Spheron customer record. Every subsequent card-payment invoice includes the company name, address, tax ID, and is sent to the configured invoice email automatically.
:::
#### Update or remove details
Click **Manage on Stripe** at any time to change company information, update the address, swap the tax ID, or change the invoice email. Updates apply to **future invoices only**; previously issued invoices are not retroactively modified.
#### Access past invoices
Stripe emails each invoice to the configured invoice email address. Past invoices are also available in the Stripe billing portal via the same **Manage on Stripe** button.
### Team discounts
Volume-based and admin-assigned discounts apply automatically. The discounted price appears directly in the GPU listings on the dashboard when your team has an active discount.
* The higher of volume-based or admin-assigned discounts is applied automatically
* No action is required; discounts apply as long as you are authenticated
To inquire about discount eligibility for high-volume usage, use the chat widget on [app.spheron.ai](https://app.spheron.ai) or email [info@spheron.ai](mailto\:info@spheron.ai).
### Best practices
**Credit management:**
* Start with $50-$100 to understand usage patterns
* Monitor balance regularly for long-running instances
* Enable Auto Top-Up to avoid unexpected terminations
* Watch for the [low-balance warning emails](#low-balance-warnings) as your runtime drops
* Use custom amounts for precise budgeting
**Cost optimization:**
* Review usage analytics to identify expensive deployments
* Terminate unused instances promptly
* Stop an instance you will come back to, so the GPU stops billing while the disk is preserved
* Use [Reserved GPUs](/reserved-gpus) for long-term workloads (30-50% savings)
* See [Cost Optimization](/cost-optimization) for GPU tier selection and Spot strategies
**Security:**
* Card payments are Stripe-encrypted and PCI compliant
* Stables payments are settled on-chain via CopperX
* Card data is never stored on Spheron servers
### Frequently asked questions
**Q:** What happens if I run out of credits?
**A:** Instances terminate automatically to prevent overcharges. Add credits to resume.
**Q:** Does a stopped instance still cost credits?
**A:** Yes, at the stopped rate, which covers the retained disk and public IP rather than the GPU. See [Billing for a stopped instance](#billing-for-a-stopped-instance).
**Q:** Do credits expire?
**A:** No. Credits never expire and remain available indefinitely.
**Q:** Can team members share credits?
**A:** Yes. Credits are shared across all team members.
**Q:** How quickly are credits delivered?
**A:** Instantly upon payment confirmation, for both card and stables payments.
**Q:** What are the deposit limits?
**A:** Minimum: $15 per deposit. Maximum: $5,000 per deposit.
**Q:** Are there hidden fees?
**A:** No. 1 credit = $1 USD of GPU usage. No additional fees.
**Q:** Can I get a refund?
**A:** Credits do not expire, so they retain value. Contact support for specific refund inquiries.
### What's next
* [Getting Started](/getting-started): Deploy your first instance
* [Reserved GPUs](/reserved-gpus): Long-term GPU reservations
* [User Settings](/user-settings): Configure billing alerts
* [Cost Optimization](/cost-optimization): Reduce GPU spend
* [Instance Lifecycle](/concepts/instance-lifecycle): Stop an instance to pause GPU billing
* [API Reference](/api-reference): Programmatic billing access
## Changelog
All notable changes to **Spheron AI** will be documented in this file.
Track new features, improvements, bug fixes, and breaking changes across all releases. This changelog is automatically updated with each deployment to ensure you always have the latest information about platform updates and enhancements.
:::steps
### `v1.29.0` • 2026-09-10
#### AMD Instinct Arrives on the Marketplace
> Every GPU on the marketplace has been NVIDIA until today. Spheron AM is live with AMD Instinct MI300X, 192 GB of HBM3e per GPU, and offers now say which vendor made the silicon you are renting.
**Expansion**
* **AMD Instinct MI300X, the first AMD silicon in the catalogue.** Each GPU carries 192 GB of HBM3e, and the catalogue publishes 1x, 2x and 4x GPU configurations. They sort, filter, and deploy through the same wizard as everything else, so choosing AMD is a choice about the hardware and not about learning a second workflow.
* **A new provider: Spheron AM.** It appears in Choose Provider alongside the others, with hourly rates in USD. A machine that is out of stock reads as sold out rather than disappearing, so you can set an availability alert instead of wondering where it went.
* **A new region in Michigan, United States.**
**UX Improvements**
* **Offers and instance cards name the silicon vendor.** AMD, NVIDIA, and Intel each carry their own mark. A catalogue with more than one vendor in it should not make you infer the manufacturer from a model string, and a part we cannot place keeps a neutral icon rather than wearing the wrong vendor's logo.
* **The deploy wizard tells you when the provider sets the minimum runtime.** Some machine types are held for a minimum reservation that is longer than the platform's own floor. Where that happens, the wizard names the provider and shows the longer number before you deploy, and that is the same number enforced when you come to terminate.
**Behaviour Notes**
* **Spheron AM machines ship one image, Ubuntu with ROCm.** There is no image picker, because the machine type determines what it boots.
* **The boot disk comes with the machine type.** Its size is shown on the offer rather than being something you set.
* **Restart is available. Stopping is not.** A Spheron AM instance bills at the full hourly rate until it is destroyed, so there is no stopped state that costs less. An instance you have finished with should be terminated.
* **Volumes are not available on Spheron AM.** A deployment that asks for one is refused rather than created without it.
* **Each machine type carries a minimum reservation, and it is charged in full.** Terminating early does not reduce it. The figure is shown in the wizard before you deploy.
* **Spheron AM is on-demand only.** There is no spot option for these offers.
**API**
* `GET /api/gpu-offers-with-reserved?providers=spheron-am` returns Spheron AM offers. Send an offer's `region` value back unchanged as `region` on the deployment.
* `POST /api/deployments` rejects `volumeIds` for Spheron AM rather than ignoring it.
* Deployments carry `providerMinimumRuntimeMinutes` when the machine type declares one. `GET /api/deployments/:deploymentId/can-terminate` reports `minimumRuntime` as whichever is longer, the platform floor or that value, and refuses until it is met.
* `POST /api/deployments/:deploymentId/restart` is supported on Spheron AM. `POST /api/deployments/:deploymentId/pause` returns an error naming the reason.
### `v1.28.0` • 2026-09-06
#### A New Provider: Spheron MS
> A new GPU provider is live on the marketplace. Spheron MS brings a large catalogue across regions the marketplace has not covered before, with storage you attach at deployment time and a restart you can reach from the instance card.
**Expansion**
* **Spheron MS appears in Choose Provider.** Its offers sit alongside every other provider, sorted and filtered the same way, with hourly rates in USD. A machine that is out of stock shows as sold out rather than disappearing, so you can set a notification instead of wondering where a GPU went.
* **New regions.** Spheron MS lists GPUs in regions the marketplace has not offered before. Each offer names its region, and the region on the offer is the region you deploy into.
* **Bare metal alongside virtual machines.** Where an offer is a full physical server it is listed as bare metal and labelled on the card.
**New Features**
* **Volumes attach when you deploy.** Create a volume in the region you are about to deploy into, then pick it in the deployment wizard. It is mounted before the machine boots, so your data is there the first time you connect.
* **Restart from the instance card.** A restart reboots the machine in place. Your billing does not change and the instance keeps its status.
**Behaviour Notes**
* **A Spheron MS volume is chosen at deployment time, and only then.** There is no attach or detach for a machine that is already running. Terminating the instance releases the volume, and you can then select it for your next deployment.
* **One volume per instance on Spheron MS.**
* **Volume size and name are fixed at creation.** Spheron MS volumes cannot be resized or renamed afterwards. Create a new volume at the size you need and copy your data across.
* **A volume and its instance must be in the same region.** A volume created in one region cannot be attached to an instance in another, and the wizard will not offer it.
* **The boot disk comes with the machine type.** Each Spheron MS machine type ships a fixed boot disk, so its size is shown on the offer rather than being something you set. Pick a machine type with the disk you need, or attach a volume for the rest.
* **Stopping is not available on Spheron MS.** Restart is, on virtual machines. Bare metal instances support neither. An instance you have finished with should be terminated.
**API**
* `GET /api/gpu-offers-with-reserved?providers=spheron-ms` returns Spheron MS offers. Send an offer's `region` value back unchanged as `region` on the deployment.
* `POST /api/deployments` accepts `volumeIds` with exactly one volume for Spheron MS. The volume's region must equal the offer's region, or the request is rejected before anything is created.
* `POST /api/volumes` requires `region` for Spheron MS and has no default. `PATCH /api/volumes/:volumeId` and `POST /api/volumes/:volumeId/attach` return an error for Spheron MS volumes.
* `POST /api/deployments/:deploymentId/restart` is supported on Spheron MS virtual machines. `POST /api/deployments/:deploymentId/pause` returns an error.
### `v1.27.2` • 2026-09-05
#### Sold-Out GPUs Stay on the Page
> A GPU that is out of stock should read as sold out, not as something the provider never offered. Four ways it could vanish instead.
**Bug Fixes**
* **A sold-out variant no longer takes its Spot tile with it.** On Spheron ES the published floor price for L40S was worked out after the live quote and inside the same guard, so a failed quote lost the fallback and the Spot option disappeared from the L40S page entirely. The floor is applied first now, and only where a price has never been quoted, so a live price is never replaced by it.
* **A GPU that is out of stock everywhere keeps its provider listed.** A model with no stock anywhere has no cache row to carry forward, so one quiet fetch from an upstream erased that brand from Choose Provider while every other provider still showed it as sold out. Sold-out offers are merged with what is already known and held for 7 days after they were last seen.
* **Sold-out offers name the provider by brand.** Rows served from the sold-out cache carried raw upstream ids rather than the brand names used everywhere else in the same response.
**UX Improvements**
* **The CPU vendor is named on the configuration card.** Spheron ES ships L40S on both Intel and AMD hosts and separates them only by a slug you never see, so the host you found after connecting was not necessarily the host you picked.
### `v1.27.1` • 2026-09-05
#### Deployment Emails and Interface Repairs
> The deployment ready email printed markup at people and named GPUs that do not exist. Alongside it, a set of repairs to the surfaces this release touched.
**Bug Fixes**
* **The deployment ready email prints the path, not the markup.** The private key placeholder was escaped by hand and then again by the renderer, so the mail showed the escape sequence instead of the placeholder. Its plain text copy was run through the HTML renderer as well.
* **The email names the GPU you deployed.** The type was read out of the deployment name, which is `-x-` only when you did not choose a name yourself. Call an instance `my-training-box` and the email announced a GPU called `MY`. It uses the stored GPU type now, formatted the way the dashboard formats it, so the mail says `L40S PCIE`.
* **Cards in a grid no longer wear a pale band.** The card border is a padded wrapper, so the shortest card in a stretching row left a hairline of it uncovered along the bottom.
* **Instance and volume rows use one button.** Each action row built its own, so a row could hand off to a confirmation dialog styled like a different product. Both rows use the same button at one height, so labelled buttons and icon triggers cannot drift apart.
* **The SSH step gives its space to the fields.** The upload zone, the key fields, and the empty volumes state gave their largest blocks of space to their smallest jobs.
### `v1.27.0` • 2026-09-05
#### Stop an Instance Without Losing It
> Stopping an instance used to mean destroying it. Now it parks: the GPU stops billing, the disk and everything on it stays exactly where it was, and you start it again when you want it. Restart arrives alongside, for a machine that needs a reboot rather than a rebuild. Neither is available on every provider, and the two do not line up with each other, so the controls show up only where the upstream can actually honour them.
**New Features**
* **Stop and Start, on the card and in the details panel.** Stop parks the machine and keeps its disk. Start brings it back with the same disk, the same contents, and the same public IP, so the connection details you saved still work.
* **The stop dialog quotes both rates before you commit.** It shows what the instance costs running, what it will cost stopped, the saving as a percentage, a monthly figure for leaving it that way, and an itemised list of what is still being charged. Stopped rates are printed to four decimal places, because at two most of them round to $0.00 and read as free.
* **Restart, as a reboot.** A restart reboots in place. Your billing does not change and the instance keeps its status. It is offered only where the provider has a real reboot operation, which is a different list from the providers that can stop: Spheron AI reboots and Spheron ES does not, so restart is absent on Spheron ES even though stopping works there. It is never synthesised from a stop followed by a start, because that releases the GPU and carries a completely different risk under the same label.
* **Controls appear only where the provider can honour them.** Stopping is available on Spheron AI and Spheron ES, and nowhere else. On Spheron AI it also depends on the machine type and the region: roughly half of one upstream's catalog cannot hibernate, and one region refuses to shut instances down at all. Verda and Sesterce keep charging in full for a shut down instance, so the control is absent there. The deploy summary and the instance panel say which of the three is the reason, since the remedy differs: another machine type, another region, or another provider.
* **A warning where starting again depends on stock.** Some providers release the hardware while an instance is stopped, so a start can be refused while that machine is out of stock. The dialog says so before you commit, and how strongly depends on the provider. A refusal is not destructive: the instance and its disk stay as they are and you try again when stock returns.
**Billing**
* **A stopped instance is billed for its disk, not its GPU.** The stopped rate comes from the provider, read back from the upstream where it publishes one and quoted from the live pricebook where it does not. It covers the retained disk, plus the public IP where the provider charges for one. Any discount on your account applies exactly as it does while running.
* **The switch is settled at the rate you were on.** Charges run on a five minute cycle, so a stop landing mid-cycle would otherwise bill the whole slice at whichever rate happened to be stored when the cycle fired. Stopping and starting both settle the elapsed time at the outgoing rate first. Usage figures, invoices, and the billing page pick stopped periods up with no change.
* **A stop from the provider's side is billed as a stop.** When a provider parks your machine, the dashboard says stopped and you are charged the stopped rate. Previously the instance read as running at the full rate for hours and then vanished as a termination while the VM was still alive upstream. Where the stopped rate cannot be determined you are charged nothing rather than guessed at.
**Reliability**
* **A stopped instance is not cleaned up as an orphan.** Several sweeps decided what was alive from a list that meant running or deploying only. A stopped instance would have been destroyed about fifteen minutes in.
* **Rebooting is no longer mistaken for a preemption.** A reboot looks exactly like a stop from outside, and the existing protection covered dedicated instances only, so restarting a spot instance would have destroyed it. A restart now arms a guard that covers the boot, and the dashboard leaves RESTARTING as soon as the machine reports back rather than waiting out a fixed window.
* **A deliberate stop is never stalled out.** A machine wedged in a stopped state is closed out after three hours, which is right for a stuck VM and wrong for one you parked yourself. A stop you asked for is exempt. A provider side stop still starts that clock, so nothing can sit there forever.
* **A start no longer bounces back to stopped.** A freshly started instance can still report as stopped for a cycle or two, which read as the provider having parked it and flipped the instance straight back. The provider is believed only when it reports a settled state, and never in the tail of a start we asked for.
* **A stop still in progress is not reported as a failure.** Writing a machine's memory to disk routinely outlives the request, so a timeout usually means the work was accepted and is still running. It now says the request went through and to check back.
* **Failures say what went wrong.** A failed stop or start carries the provider's own words where they are safe to show, for example that a machine type has no hibernation or that an instance has not finished stopping yet. The full cause is logged with the deployment, instance, provider, and region.
**UX Improvements**
* **Buttons that would fail are not offered.** Stopping and starting take minutes upstream, and the provider refuses the opposite action throughout. The control reads Stopping, Start, or Starting, driven by when the provider confirmed the change settled rather than by a guess, and explains the wait on hover.
* **A stopped instance reads as stopped everywhere.** The badge is amber, between the running blue and the terminated grey, because a stopped instance is neither working nor gone and still costs something. The card and the details panel each carried their own copy of the rate and status logic and had drifted, so one instance could show its stopped rate on the card and the running rate, nearly ten times higher, in the panel. There is one copy now.
* **Sub-dollar rates are legible.** The price tile sets dollars large and cents small, which reads well for $1.29 and inverts below a dollar: every significant digit landed in the small text and the one large glyph was a zero. A stopped instance is always sub-dollar, so a paying instance read as free at a glance.
* **The public IP is shown while stopped.** The address is kept through a stop, so hiding it forced people to start an instance just to read it back. The SSH command stays hidden until the machine is running, since it will not connect otherwise.
* **Destroy stays available while stopped.** Starting an instance first, purely to earn the right to stop paying for it, would be backwards.
* **The stop dialog names the one way stopping can lose an instance.** A stopped instance still costs something, and a team that runs out of credit has every instance destroyed, stopped ones included. The dialog says so, and points at destroying the instance instead when you are finished with it.
* **Restart asks first.** It is a hard reboot on every provider we can verify, so anything held in memory is lost. Restart confirms and says that, where stop leads with the rates because that decision is about money.
**API**
* `POST /api/deployments/{id}/pause`, `POST /api/deployments/{id}/resume` and `POST /api/deployments/{id}/restart` stop, start, and reboot an instance. Asking a provider that cannot do one of them returns a refusal that names the limit rather than a generic failure.
* `GET /api/deployments/{id}/pause-quote` returns the current rate, the stopped rate, and the breakdown behind it, without changing anything.
* `GET /api/deployments/{id}/reboot-status` reports whether a reboot is still in flight.
* A stopped instance reports `status: "stopped"` and is part of the live set. It is included in `?status=active`, and `?status=stopped` narrows to the stopped ones. The unpaginated listing filtered on an exact status match, so a stopped instance disappeared from the live set without appearing in the terminated one.
### `v1.26.0` • 2026-08-13
#### Light Mode
> The whole console can now be read on a light background. Choosing the theme meant walking every page, so a long list of smaller repairs came with it.
**New Features**
* **Light mode, with the switch in the sidebar.** Sit the console on paper instead of black. Your choice is remembered and applied before the first paint, so a page no longer flashes the wrong theme while it loads. The switch is in the sidebar whether or not you are signed in, and on a phone it sits in the navigation drawer.
**UX Improvements**
* **One card for your discount.** The Discounts section on Billing stated the same code, percentage, and expiry twice. It is one card now.
* **The redeem box is offered only when a code can be redeemed.** A team holds one discount at a time, but the form took a code anyway, called it valid, and then failed. While a discount is running, the section names the code and the date you can redeem another.
* **Attached volumes and attached instances match.** The two lists describe one relationship from opposite ends and were drawn differently. They share a layout now: volume rows gained the status badge they were missing, and instance rows gained the hourly rate.
* **Copying confirms itself.** Copy buttons in the instance panel wrote to the clipboard silently, so nothing distinguished a copy from a dead button. They confirm the way the volume panel already did.
* **vCPU counts are labelled vCPU.** The instance panel quoted a vCPU count in cores, which is a different unit.
* **Docs reachable before you sign in.** The link sat in the navigation bar only once you had an account.
**Bug Fixes**
* **The copy icon no longer disappears when you point at it.** Hovering anywhere on a card turned the icon the colour of the button beneath it.
* **Badges no longer react to the pointer.** Every status chip lit up on hover as though it could be clicked. None of them can.
* **Destroy and delete warnings are readable.** The warning panel on those confirmations filled with a strong pink that pulled its own text to an uncomfortable contrast.
* **Wizards fit an iPad again.** At 1024px the deploy pages split to seat the order summary while the catalog kept the column count it chose for a full window. GPU offer cards, provider cards, and the reserved GPU heading were all squeezed, and the heading broke across four lines.
* **Back buttons sized on mobile.** Previous in the volume and reserved GPU wizards sat at content width beneath a full width primary button.
* **Voltage Park removed from the API reference.** The docs listed a provider that is no longer offered, along with the Kubernetes add-on that ran only on it.
### `v1.25.3` • 2026-08-11
#### Keep Your Filters
> Everything you set in the catalog toolbar survives a refresh and travels in the link.
**New Features**
* **Filters persist and can be shared.** Your search, sort, providers, and regions are kept in the address bar. Refreshing keeps the view you were looking at, and the link you copy opens the same filtered catalog for a teammate. Only what you changed appears in the link.
**Bug Fixes**
* **Search matches the name on the card.** Any search containing a space came back empty, so searching a full name such as `H100 SXM5` found nothing. Search now matches the name shown on the card, so multi word searches work.
* **Collapse label sized like the rest of the sidebar.** The Collapse control at the bottom of the sidebar was set smaller and in a different face from API Docs and Changelog above it, so it read as a heading rather than the third item in the list.
### `v1.25.2` • 2026-08-11
#### Deployment Emails, Volume Attach and Detach
> Deployment emails reach the people who asked for them, attaching and detaching a volume shows up straight away, and the catalog lists every provider again.
**Bug Fixes**
* **Deployment emails are sent to everyone who opted in.** Users who had turned on deployment notifications were not receiving them. Notification preferences are now honoured when a deployment succeeds or fails.
* **Attach and detach show immediately.** After attaching a volume to an instance, or detaching it, the volume panel kept showing the previous state until the page was reloaded. It updates as soon as the change completes.
* **Instances are named in the attach picker.** Choosing an instance to attach a volume to listed entries that were hard to tell apart. Each option now names the instance and what it is.
* **All providers listed in the catalog filter.** The provider filter could show only Spheron AI while offers from other providers were visible in the catalog behind it. Every provider with live offers is listed again.
* **Deployment progress heading readable.** The heading on the deployment progress card sat too dark against its own background to read comfortably.
### `v1.25.1` • 2026-08-10
#### Monthly Costs and a Tidier Interface
> The order summary quotes a month rather than a week, and the instance and volume panels have been evened out.
**UX Improvements**
* **Costs quoted per month.** The order summary projected spend for a week, which is rarely the unit anyone budgets in. It now quotes a full month, calculated from the hourly rate.
* **Usage on one line.** Instance usage was spread over several rows in the details panel and now reads as a single compact line.
* **Consistent panel typography.** Headings and body text in the instance and volume panels were larger than the rest of the interface and did not match each other. Both panels now use the same sizes.
* **Square corners throughout.** Several panels kept rounded corners that did not match the rest of the interface.
* **Cleaner copy.** Punctuation in the marketplace text has been made consistent.
**Reserved GPUs**
* **Reservation requests are for bulk capacity.** Reserved GPU requests now hold to a minimum quantity, so the form reflects what a reservation is actually for.
### `v1.25.0` • 2026-08-09
#### Not Every Job Needs a GPU
> Some workloads just need cores. Build steps, data prep, schedulers, API workers, control planes: none of them touch a GPU, and until now you had to rent one anyway. CPU Node has its own page in the sidebar, its own wizard, and prices from $0.09 per hour.
**New Features**
* **A Deploy CPU page.** CPU Node sits in the sidebar under Compute, next to Deploy GPUs, and opens whether or not you are signed in. There is no catalog to page through and nothing to search for. Every provider's CPU offer collapses onto a single option, so the page selects it for you and goes straight to the configuration.
* **Configuration first.** Step 1 asks for spot or dedicated, then the provider, then the instance size, then the region and operating system. GPU count, cluster networking, and the deployment type picker are absent, because a CPU node has no answer for any of them. Step 2 is unchanged: the SSH key, startup script, volumes, and order summary are the same ones the GPU wizard uses, so the two flows cannot drift apart.
* **Every CPU size in one place.** CPU Node collects the CPU instances from Verda, Spheron AI, and Sesterce into a single option rather than one entry per provider. Sizes run from 4 vCPU with 4 GB of memory up to 360 vCPU with 1440 GB, and the wizard shows the lowest available price for each size before you commit.
* **Spot pricing on CPU.** Verda CPU instances are available at spot rates as well as on demand, currently from $0.09 per hour. The spot and on demand toggle works exactly as it does for GPU offers.
* **Regions.** CPU Node is available in Finland 1, Finland 2, and Finland 3 on Verda, Norway 1 and Canada 1 on Spheron AI, and Austin, Oslo, and Montreal on Sesterce. Availability varies by size and region, and the wizard only offers sizes that a region can actually serve.
**UX Improvements**
* **The GPU catalog lists GPUs only.** CPU Node is deployed from its own page, so the catalog asks the server for GPU offers rather than filtering them out after they arrive. The result count and the number of pages are honest again.
* **No GPU driver images on a CPU instance.** The operating system list for a CPU node offered CUDA and other GPU driver images that cannot be used without a GPU. Only images that make sense on a CPU instance are listed.
* **CPU instances state their size.** Where a GPU instance names its model, a CPU instance names its vCPU and memory. This applies on the offer card, in the configuration and order summaries, on the instance card, in the details panel, and in the confirmation shown before terminating an instance. GPU count and video memory are left out entirely rather than shown blank.
* **Hardware is marked by an icon.** Instance cards carry a mark for the hardware they run on, so a CPU node and an accelerator can be told apart at a glance.
* **Even specification grid.** The machine configuration panel left gaps where a value was missing. It now lays out as a consistent grid.
* **Topping up mid deploy brings you back to Deploy CPU.** If your balance is short, the configuration you had built is held while you top up and restored when you return, the way it already worked for GPUs.
**Bug Fixes**
* **Two choices made at once no longer overwrite each other.** Every selection in the deploy wizard rewrote the whole configuration from a copy taken earlier in the render, so when two selections landed together one of them was dropped. A step's own default is applied before the page's, which meant the dropped one was reliably yours. Each choice now writes only the field it changed.
* **A deliberate choice of Spot is never overridden.** Where an offer is sold both ways, a default now fills an empty selection only. Where an offer is sold one way, a selection that cannot be deployed is still corrected for you.
* **The signed out wizard no longer flickers.** Moving between the GPU and CPU pages while signed out wrote to browser storage in a loop. It settles at once now.
**API**
* `GET /api/gpu-offers` lists CPU Node alongside the GPU offers, as a single row with `gpuType: "CPU"` and `displayName: "CPU NODE"`. Narrow the catalog to that row with `?search=cpu`. Every entry in its `offers` array reports `gpuCount: 0` and carries the `offerId` a deployment takes, along with `vcpus`, `memory`, `storage`, `price`, `os_options`, and the region in `clusters`.
* `POST /api/deployments` accepts CPU offers. Send `gpuType: "CPU"` with `gpuCount: 0`. Deployments created this way are stored with the same values, so responses and usage records report a CPU node rather than an unnamed GPU.
### `v1.24.1` • 2026-07-30
#### Rates That Track the Provider, Plus Deploy Wizard Fixes
> Your hourly rate now follows the provider's price for the whole life of an instance, not just at launch. Deploying a GPU alongside a volume no longer fails with a region you never picked, spot configurations are priced on the rate you actually pay, and the setup you return to after adding balance is re-checked against live offers.
**Billing**
* **Rates Track Current Provider Pricing:** Your hourly rate now stays in line with the provider's current price for a GPU you are already running. Previously this applied on only some providers, so an instance could hold its launch-day rate for its entire life even after the underlying price moved. Charges are calculated from the point the price changes onward, so usage you have already been billed for is never recalculated, and any discount on your account continues to apply
**Bug Fixes**
* **Correct Region When Deploying With a Volume:** Setting up an instance and a volume in the same region could fail with an error naming a region you never selected, for example reporting an offer in `EU North 1` when everything was set to `EU West 1`. This happened when two regions shared the same price. The wizard now keeps your selected region and the selected configuration in step, on Spheron ES and Verda alike
* **Cheapest Spot Region Selected by Default:** Spot configurations were ranked using the on-demand price rather than the spot price you are billed. The region chosen for you was not always the cheapest, and the region list could appear out of order against the prices shown next to it. Both now use the spot price
* **Setup Re-Checked When You Come Back:** After adding balance or signing in part-way through setup, the wizard could still show the price and availability from when you started. Your configuration is now re-checked against live offers when you return, so the order summary matches what you are charged. If the provider has withdrawn that configuration in the meantime, you are told directly instead of finding out when the deploy fails
***
### `v1.24.0` • 2026-07-14
#### Reboot-Proof Dedicated GPUs, Earlier Low-Balance Warnings & B300 on Spheron ES
> A dedicated GPU that reboots on the provider side now stays alive and recovers on its own, instead of being torn down while you are still using it. Low-balance warnings start hours earlier, Spheron ES adds B300 GPUs with visible memory specs, and a malformed SSH key now fails fast with a clear message.
**Expansion**
* **B300 Now on Spheron ES:** Spheron ES offers now include the B300 SXM. It is identified correctly in the deploy wizard, on GPU cards, and in the API, instead of surfacing under an unrecognized name
* **GPU Memory on More Offers:** Every Spheron ES and Spheron AI offer now shows its per-GPU memory (VRAM) on the GPU cards and in the order summary, matching the other providers. Offers that previously left memory blank now display it
**Reliability**
* **Dedicated GPUs Survive Provider Reboots:** When a dedicated GPU instance reboots on the provider side and briefly reports as stopped or offline, it is no longer terminated automatically. It stays running and recovers on its own once it comes back online, so a routine provider reboot can no longer destroy a machine you are still using. Spot instances keep their existing behavior
* **Cleaner Handling of Stuck Spheron ES Instances:** On Spheron ES, a dedicated instance that never actually started, or that stays stopped for an extended period, is now cleaned up instead of lingering, while genuine short reboots keep the instance alive
* **Steadier Sign-In:** Fixed a rare sign-in failure that could hit a brand-new account created from two near-simultaneous requests. Returning to the app after a page refresh is also faster, because it no longer re-runs the full sign-in flow
**Notifications**
* **Earlier Low-Balance Warnings:** Low-balance warnings now begin sooner, at roughly 12, 6, and 3 hours of estimated remaining runtime, on top of the existing 1 hour, 30, 15, and 5 minute alerts. You get more lead time to top up before your instances are affected, and the balance-exhaustion notice is unchanged
**API**
* **Clear Error for Invalid SSH Keys:** Creating a deployment with an `ssh_public_key` that is not a string (for example an object) now returns a `400` error that names the problem up front, instead of a generic provider failure reported after a dead deployment record was already created. Valid keys are unaffected
***
### `v1.23.0` • 2026-06-30
#### Faster Dashboards, Automatic Deposit Recovery & Consistent Rate Limits
> Your billing, instances, and volumes pages now load noticeably faster, deposits that get stuck pending are recovered or cleared on their own, and API rate limits are enforced consistently no matter how busy the service is.
**UX Improvements**
* **Faster Billing and Dashboard Loads:** The billing analytics, instances, and volumes pages now load noticeably faster, especially on repeat visits, so you spend less time waiting on spinners. Data still refreshes in the background, and if a fresh result is ever unavailable the page falls back to live data, so what you see stays accurate
**Reliability**
* **Automatic Recovery of Stuck Deposits:** If a credit deposit you paid for ever gets stuck in a pending state because a confirmation was delayed or missed, it is now detected and credited to your balance automatically, with no need to contact support. Deposits that were genuinely abandoned or expired are cleared from your history instead of lingering as pending forever. Automatic top-ups are unaffected and keep their own retry behavior
**API**
* **Consistent Rate-Limit Enforcement:** API rate limits are now enforced consistently across the entire service. The documented limits hold accurately even under heavy concurrent traffic, so requests above a limit are reliably throttled instead of occasionally slipping through
***
### `v1.22.0` • 2026-06-17
#### Email Notification Controls, Time-Based Low-Balance Alerts & Billing Fixes
> You now decide which marketing emails you receive, while account and billing emails always reach you. Low-balance warnings tell you how much runtime you have left instead of a flat dollar figure, and expired volume discounts correctly drop back to the standard rate.
**New Features**
* **Email Notification Preferences:** A new Notifications tab in Settings lets you turn marketing emails on or off. You are subscribed by default. Flip the toggle off and you stop receiving product and offer emails, while account and billing emails (deployment status, low-balance warnings, payment receipts) keep coming. Those essential emails are always on and the toggle does not affect them
* **One-Click Unsubscribe:** Every marketing email now carries an unsubscribe link that opens the Notifications tab directly, along with a short note explaining why you received it
**Notifications**
* **Time-Based Low-Balance Alerts:** Low-balance and balance-exhaustion warnings are now based on how much runtime you have left, not a fixed dollar amount. Spheron estimates your remaining time from your balance and current hourly burn rate, then warns you as you cross roughly 60, 30, 15, and 5 minutes of runtime. The same alert now means the same thing whether you run a single small GPU or a large cluster
**Bug Fixes**
* **Expired Volume Discounts Revert:** When a team's discount expires, volumes now return to their standard hourly rate on the next billing cycle, the same way instances already did. Previously an expired discount could keep applying to a volume's billed rate after it had lapsed
***
### `v1.21.6` • 2026-06-04
#### Out-of-Stock Notify-Me for Spot GPUs & Cleaner GPU Cards
> Out-of-stock notify-me now covers spot GPUs too, so a sold-out spot configuration sends you to the Notify CTA instead of a dead form. The same GPU no longer splits into duplicate cards, and the order summary now shows GPU memory.
**Notify-Me for Spot**
* **Spot Out-of-Stock Cards:** When a spot GPU is fully out of stock, the deploy wizard now hides Region and OS and shows the same Notify CTA you already get for dedicated GPUs, instead of dropping you into a half-configured flow that reported "No OS options available for this region"
* **Surfaces Right Away:** Spot configurations that had already sold out now show the Notify CTA immediately, with no waiting for the next stock refresh
**Cleaner GPU Cards**
* **No More Duplicate Cards:** The same GPU no longer fragments into duplicate cards or shows a doubled form-factor suffix. Listings like "A100 80G SXM4 SXM4", or "A30" and "A30 PCIE" appearing as two separate cards, are now collapsed into one
* **Sold-Out Counts Stay Actionable:** When a specific GPU count on Verda is out of stock, the wizard keeps the Notify-me CTA reachable and hides the storage selector, instead of dropping you into a dead configuration flow
* **GPU Memory on the Order Summary:** The order summary now shows each GPU's VRAM next to its name
* **Accurate Availability Header:** The available and guaranteed header copy now tracks live capacity, so it agrees with the GPU Count and Region sections
***
### `v1.21.5` • 2026-06-02
#### Accurate GPU Pricing & Broader SSH Key Support
> GPU prices in the deploy wizard and the API now reflect the right offer, with no sold-out offer undercutting the best available price. Deploys with ECDSA and FIDO security keys now work on Massed Compute and Verda.
**Accurate Pricing**
* **Correct Spot and Dedicated Counts:** Spot and dedicated offers are no longer double-counted against each other, so the lowest spot price, lowest dedicated price, and availability counts are accurate
* **Best Available Price Ignores Sold-Out Offers:** The best-price figure on a GPU card now comes from in-stock offers only, so a stale out-of-stock price can no longer win and mislead you
* **Cleaner Public API:** `GET /api/gpu-offers` no longer returns internal out-of-stock offers. Existing fields are unchanged, so existing integrations keep working
**Broader SSH Key Support**
* **ECDSA & FIDO Keys Now Work:** Deploying to Massed Compute or Verda with an ECDSA (`ecdsa-sha2-...`) or FIDO security key (`sk-ssh-ed25519@openssh.com`, `sk-ecdsa-...`) now succeeds. Previously only RSA and Ed25519 keys were accepted and other types failed with "SSH Key does not exist". Spheron AI, Spheron ES, Sesterce, and Voltage Park already accepted every key type
***
### `v1.21.4` • 2026-06-02
#### Billing: Cost-Saving Intelligence & Spend Visibility
> The billing page is now an actionable cost dashboard. See where you can save against other providers and the big hyperscalers, spot idle resources, and track spend trends and anomalies at a glance.
**Cost-Saving Signals**
* **Cross-Provider Price Comparison:** Each deployment row shows whether you are on the cheapest provider for that GPU, or how much more you are paying per hour than the cheapest option (`+$X/hr vs `)
* **Hyperscaler Comparison:** A line under each deployment compares your Spheron rate against AWS, GCP, and Azure list prices, with the percentage you are saving
* **Long-Running and Idle Flags:** An amber chip marks deployments running 7+ days, a callout flags volumes left unattached for 30+ days, and volume rows now show the cost accrued so far
**Spend Visibility**
* **Daily Spend Trend:** A sparkline of daily spend across the selected period, so trends are visible at a glance
* **Spend Breakdown:** Mini-charts break your spend down by GPU model, by provider, and by spot versus dedicated
* **Blended Rate and Month Projection:** New cards show your blended cost per GPU per hour and a projected total for the current month
* **Top Spenders and Reserved Hint:** A top-three deployments-by-spend callout, plus a hint when a GPU type's spend suggests a reserved commitment could save you money
**Discounts and Anomalies**
* **Discount Savings:** A running total of what your active discounts have saved you across the period
* **Spend Anomaly Alert:** An amber banner when a single day's spend spikes far above your recent average
***
### `v1.21.3` • 2026-05-29
#### Out-of-Stock Notify-Me Cards, Interconnect Display & UX Polish
> Sold-out GPUs now stay on screen as notify-me cards instead of disappearing, the GPU spec strip shows the interconnect bus, and a few rough edges around volume errors and confirmation dialogs are smoothed out.
**Out-of-Stock Notify-Me Cards**
* **Sold-Out GPUs Stay Visible:** Across Verda, Massed Compute, Spheron ES, Sesterce, and Voltage Park, out-of-stock GPUs now appear as dimmed "Out of stock" cards with a Notify-me CTA, instead of vanishing from the wizard
* **Sold-Out Offers Carry Forward:** Offers that briefly disappear upstream are remembered for up to 7 days, so a sold-out GPU still surfaces as a notify-me card rather than dropping off the marketplace entirely
**Interconnect Display**
* **Bus on the Spec Strip:** GPU cards now show the interconnect bus (NVLink, SXM, or PCIe) on the spec strip, so you can pick the interconnect that matches your workload
* **Clearer NVLink Labels:** NVLink-bridged GPUs are flagged consistently, and NVL models no longer carry a redundant "PCIE" suffix in their title
* **RTX PRO 6000 Corrected to Blackwell:** The RTX PRO 6000 now reads as Blackwell architecture, so you install the right driver
**UX Polish**
* **Dialogs Behave as Expected:** Confirmation dialogs now dismiss the way you expect, closing when you click outside them just like every other modal in the app, so they no longer trap you when you click away. They still stay open while an action is in progress, so you cannot dismiss one mid-operation
***
### `v1.21.2` • 2026-05-26
#### Billing & Volume Reliability
> Auto top-up now gets a chance to recover your balance before any instance is terminated for low credit, and a terminated instance's volumes return to Available instead of staying stuck, so you can reattach them.
**Billing**
* **Auto Top-Up Recovers Before Termination:** When your balance runs low, auto top-up is given time to charge your saved card and restore credit before instances are terminated. A momentary dip no longer costs you a running deployment
**Volumes**
* **Volumes No Longer Stick to Terminated Instances:** When an instance is torn down, its volumes return to Available so you can reattach them right away, instead of staying marked Attached to an instance that no longer exists
***
### `v1.21.1` • 2026-05-24
#### Confidential Compute on Verda RTX PRO 6000
> Verda's RTX PRO 6000 now offers a Confidential Compute variant that keeps your VM and GPU memory encrypted while in use.
**New**
* **Confidential Compute Variant:** Verda's RTX PRO 6000 now lists a separate Confidential Compute (CC) option alongside the standard card, so you can choose it directly in the deploy wizard
* **Confidential Compute Notice:** When you select the CC variant, the order summary explains that VM and GPU memory are encrypted in use and isolated from the hypervisor and the cloud provider itself
***
### `v1.21.0` • 2026-05-21
#### Mobile-Responsive Marketplace: Sidebar Drawer, Fluid Layouts, and Polished Wizards
> The marketplace is now usable on a phone. The desktop sidebar collapses behind a hamburger drawer on small screens, the deploy wizard reorders so the order summary stays in view above the form, instance and volume detail panels open full-screen on mobile, and every page (billing, API docs, volumes, settings, top nav) has been retuned so cards, headers, and dialogs reflow without horizontal overflow.
**Mobile Navigation**
* **Hamburger Sidebar Drawer:** On phones and small tablets the persistent sidebar is replaced by a hamburger button in the top nav. Tapping it slides a full nav drawer in from the left with an overlay dim. Tapping the overlay, hitting a nav item, or navigating away closes it. Background scrolling is locked while the drawer is open
* **One Source of Truth for Nav Links:** Desktop sidebar and mobile drawer now share the same nav definition, so a route added in one shows up in both
* **Resize-Aware:** Resizing the window from mobile to desktop closes the drawer, restores the desktop sidebar, and re-applies the layout without a reload
**Deploy Wizard on Mobile**
* **Order Summary at the Top:** On mobile the order summary now stacks above the configuration form (instead of being pinned to the right rail) so the running price and selected GPU stay visible without scrolling back up
* **Full-Width Step Buttons:** Next, Back, and Deploy buttons go full-width on mobile. The Back/Deploy pair stacks vertically with Deploy on top, so the primary action is always under your thumb
* **Truncating GPU Cards:** GPU offer cards truncate long titles and the results counter clips its parenthetical detail on narrow screens, so cards no longer push the layout sideways
**Instance and Volume Detail Drawers**
* **Full-Screen on Mobile:** Tapping an instance or volume card now opens its detail panel as a full-screen sheet (instead of a fixed-width side drawer that ran off the viewport). The panel reverts to the familiar right-side drawer on tablet and desktop
* **Safer Height on iOS:** Detail drawer height now accounts for Safari's dynamic address bar, so the bottom of the content is no longer covered
**Billing, API Docs, and Volumes**
* **Billing Page Reflow:** Balance cards, deposit packages, and the mini-metrics grid now stack cleanly on small screens, step up to a tighter grid on tablets, and keep the full layout on desktop. The tabs row scrolls horizontally on narrow screens instead of wrapping, and the saved-card section reflows for small viewports
* **API Docs Reflow:** Endpoint accordions, curl commands, the base URL section, and the quick-test panel all reflow on mobile without horizontal scroll. Long URLs and code blocks now wrap or scroll inside their cards
* **Volumes and Instances Pages:** Page headers, load-more buttons, attach/detach dialogs, and the create-volume wizard reflow for mobile widths. The load-more button is full-width on mobile and capped to a comfortable size on tablets and up
**Miscellaneous Polish**
* **Top Nav:** Logo, balance display, team switcher, deposit dialog, and user menu all retuned for narrow viewports so the bar stays single-line without overflow
* **Feature Announcement Modal:** Modal width adapts to the viewport on mobile instead of bleeding off the edge
* **Wizard Headers:** Pipe separators between header chips are hidden on narrow screens so you no longer see orphaned `│` characters
* **Reserved GPU Wizard, SSH Keys, Team Overview, GPU Alerts, Usage Analytics:** All retuned to flow into a single column on mobile with appropriately stacked actions and headers
**Accessibility**
* **Drawer Trigger:** The hamburger button now announces whether the drawer is open or closed for screen readers
* **Defensive Rendering:** The credit-package grid now guards against an empty package list, so an empty config never throws while the page is mid-render
***
### `v1.20.0` • 2026-05-15
#### GPU Availability Alerts, Smarter Stock Signals & Faster Capacity Refresh
> Never refresh the marketplace waiting for a GPU again. Subscribe to a sold-out GPU configuration directly from the deploy wizard and Spheron emails you the moment that exact GPU, count, and instance type is back in stock. The wizard now lets you navigate sold-out variants instead of hiding them, Spheron ES regions surface live stock signals before you commit, Spheron AI multi-GPU placements stay hidden while supply is too thin to deploy, and stock-out errors anywhere on the marketplace clear from the catalogue immediately instead of trailing the next user.
**New Features**
* **GPU Availability Alerts:** Subscribe to a sold-out GPU configuration directly from the configure step in the deploy wizard. You receive an email the moment that exact configuration (GPU type, count, provider brand, spot or dedicated) is back in stock. An optional price ceiling keeps the email scoped to your budget so you only get pinged when the offer is actually affordable
* **Alerts Tab in Settings:** A new Alerts tab under Settings lists every alert you have ever created. Unsubscribe a pending alert with one click, or Resubscribe a previously notified alert if you missed the window the first time
* **Brand-Wide Alert Coverage:** An alert scoped to a brand fires when any region under that brand has matching capacity. You do not have to pick a specific region to subscribe; one alert covers the entire brand
* **Navigate Sold-Out Configurations in the Wizard:** Sold-out GPU configurations now appear in the deploy wizard as dimmed cards instead of being suppressed entirely. Click through to inspect the count, networking, and provider options that are temporarily unavailable, then either subscribe to an alert or pick a live alternative without restarting the flow
**UX Improvements**
* **Per-Region Stock Signals on Spheron ES:** The region picker in the deploy wizard now shows a tiered stock pill (high, healthy, low, critical) next to each Spheron ES region, so you can see how thin supply is before committing to a region
* **Spheron ES Spot Listings Hide Low-Stock Configurations:** Spheron ES spot offers with too little stock to deploy reliably are no longer listed. This removes the failure path where a listing claimed availability but the deploy refused to allocate
* **Spheron AI Multi-GPU Stock Floor:** Spheron AI 4x and 8x configurations are only listed when the region has enough stock to fulfil them. Below the floor the configurations are hidden, so you no longer pick a placement that fails at create time
* **Collapsible Sidebar with Persisted State:** The navigation sidebar now collapses to an icon rail and remembers its state across reloads. Tooltips appear on hover when collapsed, so you can reclaim horizontal space for the dashboard, instance cards, and the deploy wizard without losing navigation
* **Reserved GPU Catalogue Updates:** The reserved GPU catalogue now includes R100 and GH200, and the GPU memory field is optional on request submissions
**Reliability**
* **Faster Capacity Detection on Dedicated Offers:** Dedicated GPU availability now refreshes every 5 minutes, so the deploy wizard and dashboard reflect real stock within minutes of an inventory change. When a pending alert exists, the marketplace forces an early refresh so the email lands while capacity is still live
* **Cache Refresh on Stock-Out Errors:** Deploy failures that signal out-of-stock now invalidate the marketplace's offer cache immediately. The next user no longer sees a just-sold-out GPU listed as available while the cache walks down its TTL
* **Availability Alert Emails:** Notification emails include a per-region capacity breakdown with brand labels, are tone-shaped for spot vs dedicated copy, and ship in both HTML and plain-text bodies so they render correctly in every client
***
### `v1.19.0` • 2026-05-11
#### Spheron ES (Spheron Extra Supply) Provider Launch, Spot Reliability & Faster Deployment Status
> Meet **Spheron ES** (Spheron Extra Supply), a new GPU provider on the marketplace with B200 SXM6, H100 SXM5, H200 SXM5, L40S, and RTX Pro 6000 across Finland, France, Middle East, and the United States. Both on-demand and spot are supported, and persistent volumes ship on day one with multi-instance attach, in-place resize, and a 256 TiB ceiling per volume. Alongside the launch, spot deployments now stay correctly labelled across the dashboard, preempted instances are reaped in seconds instead of minutes, and freshly created deployments flip to "Running" the moment the VM is live.
**New Provider**
* **Spheron ES (Spheron Extra Supply):** A new GPU provider is now live on the marketplace. Inventory currently spans B200 SXM6, H100 SXM5, H200 SXM5, L40S, and RTX Pro 6000
* **On-Demand and Spot:** Both instance types are available. Spot offers the same GPU configurations at a lower price with no uptime guarantee
* **Multiple Regions:** Spheron ES regions span Finland (EU North 1), France (EU West 1), Middle East (ME West 1), and the United States (US Central 1). They show up in the deployment and volume wizards, and in regions listings on the API
* **Country Filter Picks Up New Regions:** The country filter in the deployment wizard correctly groups EU North under Finland, EU West under France, and ME West.
* **Tier 3 DC Compliance Badge:** Spheron ES is flagged with the same Tier 3 DC compliance badge as the rest of the family
**Persistent Volumes on Spheron ES**
* **Volumes on Spheron ES:** Spheron ES is a supported volume provider from day one. Create and manage persistent storage from the `/volumes` dashboard with the same UX as the existing volume providers
* **Multi-Instance Attach:** A single Spheron ES volume can be attached to multiple instances at once, so a dataset can be fanned out across a cluster without duplication
* **Attach at Deploy Time Without Restart:** Pick a Spheron ES volume in the deployment wizard and it is wired into the instance before the VM boots. No post-boot mount step, no restart
* **Hot-Attach and Hot-Detach Supported:** Attach or detach a volume on a running instance from the dashboard or API. The instance briefly stops and restarts to apply the change; data is preserved
* **In-Place Resize:** Grow a Spheron ES volume after creation without recreating it or migrating data (shrinking is not supported)
* **Up to 256 TiB per Volume:** Spheron ES volumes can be created up to **256 TiB** in a single volume (`sizeInGb: 262144` on the API). The size slider in the wizard adapts to match
* **Volume Rules Dialog for Spheron ES:** The "Volume Rules" dialog accessible from the create-volume and attach flows now covers Spheron ES, spelling out the at-deploy attach, restart-on-hot-attach behaviour, multi-attach semantics, resize policy, and the no-rename restriction
* **Mount Tag on the Volume Card:** Each Spheron ES volume card now shows the mount tag for shared-filesystem volumes with a one-click copy, so you can grab it without opening the detail panel
**Reliability & UX**
* **Spot Type Preserved End-to-End:** Spot deployments created via the API or dashboard are now consistently labelled "Spot" on the instances page and across deployment responses. Previously a spot VM could fall through to "Dedicated" in the dashboard when the client did not pass `instanceType`. Commission, billing, and the instance card badge all derive the type from the offer catalog now
* **Faster Status Flip on New Deployments:** Newly created deployments now flip from "Deploying" to "Running" within seconds of the VM coming online, instead of the previous 30-90 second wait. The runtime counter on the dashboard tracks usage accurately from the first second
* **Faster Preemption Detection:** Spot instances that get preempted are now detected within \~10 seconds (one monitor cycle), down from the previous \~30 seconds. This shrinks the window where you might still be charged for a preempted VM's allocated disk and IP
* **Orphan VM Cleanup for Failed Spot Starts:** If a spot VM is preempted or fails to ever reach Running (for example when capacity is exhausted mid-create), the upstream VM is now reliably destroyed during cleanup. Previously the deployment was marked terminated on the marketplace side but the VM could linger and continue billing for disk and IP allocation
* **Safer Concurrent Volume Operations:** Attaching and detaching volumes back-to-back on the same instance is now race-safe. The instance monitor no longer flips a healthy VM to "Terminated" if it observes a transient stopped state during a hot-attach or hot-detach cycle
**API**
* **New `provider: "spheron-es"` Value Accepted:** `POST /api/volumes` and `POST /api/deployments` now accept `spheron-es` alongside the existing brand values. Use `GET /api/gpu-offers?providers=spheron-es` (note: `providers` is plural and comma-separated) to list GPU offers, and `GET /api/volumes/regions?provider=spheron-es` to discover regions at runtime
* **Storage Pricing on Spheron ES:** `GET /api/volumes/pricing?provider=spheron-es` returns the current hourly rate per GB. The endpoint accepts an optional `region` parameter for forward compatibility, but Spheron ES rates are currently flat across all regions
* **Multi-Instance Attach on `POST /api/volumes/{volumeId}/attach`:** Spheron ES volumes can be attached to multiple deployments concurrently. Each successful call adds the deployment to `attachedToDeploymentIds`; the same volume id can be reused on a different deployment without detaching first
* **`volumeIds` Wired in at Create:** When `volumeIds` is passed to `POST /api/deployments` for a Spheron ES deployment, the volumes are mounted as part of the create call rather than after the VM reaches Running. The response returns with the volume already marked attached
* **Volume Size Ceiling for Spheron ES:** `POST /api/volumes` accepts `sizeInGb` up to `262144` on Spheron ES (256 TiB). Read `maxSizeGb` from `GET /api/volumes/regions?provider=spheron-es` for the current cap
* **Correct `instanceType` on Deployment Responses:** `GET /api/deployments` and `GET /api/deployments/{deploymentId}` now return the correct `instanceType` for every deployment even when the client did not pass the field on create. The value is derived from the offer catalog and resolves to one of `SPOT`, `DEDICATED`, `BARE_METAL`, or `CLUSTER`. Existing fields are unchanged so existing integrations continue to work
***
### `v1.18.0` • 2026-05-07
#### More Spheron AI GPUs, More Regions, Per-Region Storage Pricing
> Spheron AI now ships with more GPU choices, more regions, and a larger storage ceiling. The volume wizard adapts size limits and price to the region you pick, region names read clearly across the dashboard, deployment failure messages are easier to act on, and Verda and Voltage Park now show the same post-create rules modal that Sesterce and Spheron AI already had.
**Expansion**
* **More Spheron AI GPUs:** Spheron AI offers now span a wider GPU lineup, including new H100 (SXM5, NVL, PCIE), A100 80GB (NVL, PCIE), A6000, RTX 4090, RTX 5090, L40, and L40S options. They appear in the deployment wizard and on `GET /api/gpu-offers` automatically with no client changes
* **More Spheron AI Regions:** Two new regions are available alongside Canada 1 and Norway 1: **Montreal 1** and **Oslo 1**. They show up in the deployment and volume wizards, and in regions listings on the API
* **Larger Volume Ceiling:** Spheron AI volumes can now be created up to **50 TB** in the new regions (up from 40 TB). The wizard adjusts the size slider's maximum based on the region you pick
**UX Improvements**
* **Friendlier Region Names:** Region picks across the deployment wizard, volume wizard, instance cards, and volume cards now display as "Canada 1", "Norway 1", "Montreal 1", "Oslo 1" instead of raw region codes
* **Country Filter Recognises New Regions:** The country filter in the deployment wizard correctly groups the new Montreal region under Canada and Oslo under Norway
* **Per-Region Storage Pricing in the Wizard:** When you change region in the create-volume wizard, the displayed hourly rate and the size slider's range update to match that region. No more clicking through and getting surprised at checkout
* **Volume Created Modal for Verda and Voltage Park:** Creating a volume on Verda or Voltage Park now shows the same post-create confirmation modal that Sesterce and Spheron AI already had. Each provider's modal summarises that provider's specific attachment and lifecycle rules and offers a one-click "Deploy GPU" shortcut to jump straight into the deployment wizard
* **Cleaner Failure Messages:** Deployment failure reasons and error messages across the dashboard, toast notifications, and deployment-failure emails now surface a single clean line instead of dense JSON payloads and status codes. The full original error is still retained internally for support requests
**Bug Fixes & Reliability**
* **Clearer Out-of-Stock Errors:** When a GPU is sold out in the chosen region, the deployment failure message now says so directly instead of returning a generic provider error
* **Friendlier 409 / Conflict Errors:** Volume delete and deployment errors that come back as a 409 (the volume is still attached, or it is being released after recent activity) now show an actionable next step instead of a generic conflict message
* **Region Switch Updates Size Cap:** Switching to a region with a different storage ceiling now resets the size slider correctly. Previously a stale cap could carry over from the previously selected region
* **Correct Volume Size Cap Per Region:** The create-volume slider now reads the maximum size of the region you actually picked. Previously the slider showed the brand's widest possible cap (50 TB) on every region, including regions that only support up to 40 TB
* **Consistent Provider Label in Errors:** Volume and deployment error toasts always show the Spheron AI label, including in a handful of rarer error paths where the wording previously slipped
* **Custom Deployment Names No Longer Fail at Create Time:** Deployments created via the API with a custom `name` (containing spaces, dots, emoji, or anything beyond letters and digits) no longer fail with a name-validation error at deploy time. Your `name` is preserved exactly as you sent it on `GET /api/deployments` and on the dashboard. See the API note below for details
**API**
* **Per-Region Size and Pricing on `GET /api/volumes/regions`:** Each region entry now includes `minSizeGb`, `maxSizeGb`, and `hourlyRatePerGb`. If you are already listing regions, you no longer need a second call to `GET /api/volumes/pricing` to render a complete picker. Existing fields (`id`, `name`, `country_code`, `types`, `hasGpuOffers`) are unchanged
* **Region-Aware Pricing on `GET /api/volumes/pricing`:** The pricing endpoint now accepts an optional `region` parameter. Spheron AI rates can vary by region, so pass the region you intend to use for an accurate rate. Calls without `region` keep returning the provider's default rate, so existing integrations continue to work
* **New Spheron AI Region IDs Accepted:** `POST /api/volumes` and `POST /api/deployments` now accept `MON1` (Montreal 1) and `OSL1` (Oslo 1) as `region` values, alongside the existing `CANADA-1` and `NORWAY-1`. Use `GET /api/volumes/regions?provider=spheron-ai` to discover the full list at runtime
* **Higher `sizeInGb` Ceiling:** `POST /api/volumes` accepts `sizeInGb` up to 51200 on Spheron AI's Montreal and Oslo regions (40960 on Canada and Norway). Read `maxSizeGb` from `GET /api/volumes/regions` for the per-region cap
* **Cleaner `error` Bodies:** Error responses across deployment, volume, SSH key, and Kubernetes endpoints now return a short, human-readable message instead of a dense JSON envelope. Existing fields are unchanged; only the message text is tidier
* **Cleaner `failureDetails` on Deployments:** `failureDetails` on `GET /api/deployments` and `GET /api/deployments/{deploymentId}` is now a single readable line on failed deployments. The classification in `failureReason` (e.g. out-of-stock, 409 conflict) is also more specific so retries and backoffs can branch on it
* **Deployment `name` is Now Display-Only:** The `name` you pass to `POST /api/deployments` is treated as a display label only. It is stored verbatim and returned unchanged on `GET /api/deployments`, `GET /api/deployments/{deploymentId}`, and the dashboard. There is no longer any character or length restriction enforced at create time, so names with spaces, dots, slashes, emoji, or longer than 63 characters are accepted. Your existing integrations keep working: there are no request changes required, and existing names continue to be returned exactly as stored
***
### `v1.17.2` • 2026-05-04
#### Deployment Response: First-Class `gpuType` and `offerId` Fields
> Deployment responses now return the canonical GPU type and the source offer ID as their own fields, so you no longer need to parse the legacy `gpuModelId` composite to render GPU details or correlate a deployment back to a GPU offer.
**API**
* **New `gpuType` field on deployments:** `POST /api/deployments`, `GET /api/deployments`, and `GET /api/deployments/{deploymentId}` responses now include a `gpuType` field with the canonical GPU type (for example `rtx-4090`, `h100`). Prefer this over splitting `gpuModelId` when rendering the GPU label. The existing `gpuModelId` field is unchanged so existing integrations continue to work.
* **New `offerId` field on deployments:** The same three endpoints now also return the `offerId` used at create time, so you can correlate a deployment back to the entry from `GET /api/gpu-offers` directly. Existing fields are unchanged.
* **No request changes required.** Both additions are response-only fields. Clients can opt in when ready and existing consumers keep working as-is.
***
### `v1.17.1` • 2026-04-28
#### API Reference & Referrals Page Refresh
> The API reference and referrals pages have been rebuilt to match the v1.17.0 design refresh, the deployment, volume, and reserved GPU wizards have picked up another round of polish, and Spheron AI spot offers now stay fresher in the marketplace.
**Design & UX Refresh**
* **New API Reference Page:** Endpoints are now grouped by category, with short descriptions, cleaner endpoint cards, refreshed request and response examples, and a tighter quick-test panel for easier scanning and testing
* **Refreshed Referrals Page:** Stats, the share link, share buttons, and the "how it works" section have been rebuilt with clearer hierarchy, step cards, and reward callouts, so it is easier to see your rewards and pass on your link
* **More Wizard Polish:** The deployment, volume, and reserved GPU wizards have picked up another round of spacing and typography tweaks across cards, selections, and order summaries
**Reliability**
* **Fresher Spheron AI Spot Pricing:** Spheron AI spot offers now refresh on the same fast cadence as other spot providers, so spot availability and pricing stay current without a manual reload
***
### `v1.17.0` • 2026-04-27
#### Marketplace Design Refresh, Volume Discounts & NVLink GPU Flagging
> A top-to-bottom visual refresh across billing, teams, volumes, API keys, SSH keys, deployment, and reserved GPU pages. Discounts now apply to volumes the same way they apply to deployments, the reserved GPU contact form captures more useful detail, and Spheron AI NVLink GPUs are clearly flagged in the marketplace.
**Design & UX Refresh**
* **Unified Visual Language:** Billing, teams, volumes, API keys, SSH keys, deployment wizard, and reserved GPU wizard have all been redesigned around a shared header, card, and table style for a calmer, more consistent look
* **New Team Switcher:** The team menu has been consolidated into a single switcher in the top navigation. Create, switch, and manage teams from one place instead of several disconnected dialogs
* **Refreshed Billing Page:** Balance, deposit history, usage analytics, discount overview, and the add-credits flow (custom amount, saved card, billing details) have all been rebuilt with clearer hierarchy and tighter spacing
* **Smoother Wizards:** Deployment, volume, and reserved GPU wizards share a common header treatment and improved step layouts. The order summary sidebar now stays put when dropdowns or dialogs open, so it no longer disappears mid-configuration
* **API Keys & SSH Keys:** Empty states, generation dialogs, the whitelist-required state, the quick reference, and the documentation card have all been updated to match the new style
* **Volume Cards & Sidebar:** Volume cards, the volume details sidebar, the resize dialog, and the create-volume order summary have been refreshed to read more clearly at a glance
**New Features**
* **Volume Discounts:** Active team discounts now apply to volume hourly rates at creation and at resize time, the same way they already apply to deployments. The discounted rate is locked in when the volume is created. If a team's discount later expires or is revoked, the volume automatically reverts to its standard rate on the next billing cycle
* **Spheron AI NVLink GPUs Flagged:** Spheron AI GPU offers that are NVLink-bridged variants (for example `H100 NVL`) are now clearly marked in the marketplace so you can pick the interconnect that matches your workload
* **Richer Reserved GPU Contact Form:** The reserved GPU request form now captures phone country and country code separately (with a country picker), preferred GPU model, requested GPU quantity, and an optional marketing consent, so the team can route inquiries faster
**Bug Fixes & Reliability**
* **Discount Preview No Longer Fails Silently:** The discount-code preview used in billing, the deposit flow, and the deployment and volume wizards now handles non-JSON error responses gracefully instead of failing in the background. Users see a clear error state instead of a stuck preview
* **Create Team Dialog Stays Open Until Done:** The create team dialog now stays open and shows its loading state until the team is actually created, matching the behavior of the invite member and add SSH key dialogs
* **Data Crunch Cleanup Safety:** The background cleanup that removes orphaned Data Crunch volumes now has additional safeguards so marketplace-tracked, idle, and shared user-owned volumes are never eligible. Only true orphans can be removed
* **Runtime Display:** Reserved runtime hours now display as `N/A` instead of `N.A` when no expiry is set
**API**
* **Volume Hourly Rate (all clients):** Volumes created or resized while a team has an active discount now bill at the discounted rate. The volume response from `GET /api/volumes` and `GET /api/volumes/:volumeId` reflects the locked-in discounted rate; the pre-discount rate is also returned for reference. If the team's discount later expires, the rate automatically reverts on the next billing cycle. No request changes are required for clients to benefit from this; pricing endpoints continue to return public list rates.
* **Spheron AI GPU Offers:** GPU offers from Spheron AI now include an `nvlink: true` flag in their metadata when the GPU model is an NVLink-bridged variant (for example `H100 NVL`, `A100 NVL`). Non-NVLink offers do not include the flag. Existing fields are unchanged, so existing integrations continue to work and can opt in to the new flag when ready.
***
### `v1.16.0` • 2026-04-24
#### Spheron AI Persistent Volumes & Provider Rules Dialogs
> Persistent storage, now on Spheron AI. Create a volume, attach it to a GPU instance at deploy time or while it's running, and move it between instances without losing data. Every volume provider now has a dedicated rules dialog so you know exactly how attachment and lifecycle work before you commit.
**New Features**
* **Spheron AI Volumes:** Spheron AI is now a supported volume provider. Create and manage persistent storage from the `/volumes` dashboard, backed by Cloud-SSD storage
* **Attach at Deploy Time or Later:** Pick a Spheron AI volume in the deployment wizard, or attach one to an already-running instance from the volume or instance sidebar. No need to tear down and redeploy to add storage
* **Hot-Detach Supported:** Detach a volume from a running instance and reattach it to a different instance without terminating either one. Your data moves with it
* **Up to 10 Volumes per Instance:** A single Spheron AI instance can have up to 10 volumes attached at once. The UI and API enforce the limit automatically so attach requests fail fast instead of in the middle of a deploy
* **Single-Attach Volumes:** Each Spheron AI volume can only be attached to one instance at a time. The dashboard hides incompatible volumes in the deploy wizard and shows a clear error if you try to double-attach
* **Persistent After Termination:** Volumes survive instance termination by default. Delete them explicitly from the dashboard when you're done
* **Large Storage Ceiling:** Create volumes from 1 GB up to 40 TB in a single volume
* **Data Crunch Multi-Volume Support:** Data Crunch instances can now attach up to **10 shared volumes** at a time, up from a single volume in v1.14.1. Each Data Crunch volume can still be mounted on multiple instances concurrently, so you can fan out shared data and mix storage pools on the same instance
**UX Improvements**
* **Provider Rules Dialogs:** Every volume provider (Spheron AI, Data Crunch, Sesterce, Voltage Park) now has its own "Volume Rules" dialog accessible from the create-volume and attach flows. Each dialog spells out per-provider limits: attach timing, concurrent-attach rules, resize policy, and lifecycle behavior, so you know what you're getting before you create a volume
* **Volume Created Success Modal:** After a Spheron AI volume is created, a confirmation modal summarizes the rules and offers a one-click "Deploy GPU" shortcut to go straight into the deployment wizard with the new volume pre-selected
* **GPU Offer Availability Warning:** The create-volume wizard now checks whether the selected provider and region actually have live GPU offers. If there's nothing to attach the volume to, a warning surfaces in the order summary before you confirm
* **Smarter Volume Matching in Deploy Wizard:** The attach step in the deployment wizard now respects per-provider constraints. Incompatible volumes are filtered, limit warnings appear when you hit the cap, and single-attach volumes already bound elsewhere are shown as blocked with an explanation
* **Smarter Region Default on Create Volume:** The create volume wizard now auto-selects the first region that actually has live GPU offers instead of blindly picking the alphabetical first. Regions without GPU offers are clearly labeled "No GPU offer present" in the Sesterce, Data Crunch, and Spheron AI dropdowns so you can see which ones to avoid before selecting. The Data Crunch dropdown is also cleaner, with decorative flag graphics removed
* **Consistent Region Name Formatting:** Massed Compute regions (for example `us-central-3`) now display as "Us Central 3" in the deployment wizard, order summary, and instance cards, matching the style used for Sesterce and Spheron AI
**Bug Fixes**
* **No In-Place Resize (Enforced):** Spheron AI volumes cannot be resized once created. The API now returns a clear error on resize attempts instead of silently succeeding. To grow storage, create a new larger volume and migrate your data
* **Accurate Region Codes in UI:** The dashboard now shows clean region codes (for example `CANADA-1`) regardless of the provider's internal naming
* **Stale Deployments No Longer Lock Volumes:** If a previous instance terminated without a clean detach, single-attach volumes are no longer permanently locked. Attach attempts skip terminated, failed, stopped, and deleted deployments when checking occupancy, so you can always reclaim the volume onto a new instance. Applies to both Spheron AI and Voltage Park volumes
* **Cleaner Single-Attach Error Messages:** When a single attach volume is genuinely in use, the error message now lists only the live conflicting instances instead of every instance the volume has ever been attached to. Terminated and failed deployments no longer clutter the list
* **Voltage Park Single-Attach Enforced Server-Side:** Voltage Park's one-volume-per-instance and one-instance-per-volume rules are now enforced by the API, not just the UI. Double-attach attempts are rejected even when the request bypasses the dashboard
**API**
Creating and using a Spheron AI volume involves three steps:
1. **Fetch available regions:** `GET /api/volumes/regions?provider=spheron-ai` returns a `regions` array. Each entry has an `id` (the region code to pass at creation time) and a `name`. Each region now also includes a `hasGpuOffers` boolean so you can check availability before creating a volume in a dead region.
2. **Create the volume:** `POST /api/volumes` with `provider: "spheron-ai"`, `region: ""`, `name` (max 50 characters), and `sizeInGb` (1–40960). The response includes the volume `id` you will use for all subsequent operations.
3. **Attach to an instance:** two options depending on your workflow:
* At deploy time: include `volumeIds: [""]` in your `POST /api/deployments` request
* After the instance is running: `POST /api/volumes/{volumeId}/attach` with `{ "deploymentId": "" }`
**Detaching and re-attaching:** `POST /api/volumes/{volumeId}/detach` with `{ "deploymentId": "" }` frees the volume to be attached elsewhere. Data is preserved. Detach and re-attach are supported without instance downtime.
**Limits:** Each Spheron AI instance supports up to 10 attached volumes. Each volume can be attached to only one instance at a time. Resize is not supported. Rename is not supported, so pick the name you want at creation.
**Pricing:** `GET /api/volumes/pricing?provider=spheron-ai` returns the current hourly rate per GB so you can estimate cost before creating a volume.
**Data Crunch limits (updated):** Each Data Crunch instance now supports up to **10 attached volumes** (was 1 in v1.14.1). Multi-instance attach is unchanged. A single Data Crunch volume can still be mounted on many instances at the same time.
**API Docs correction:** The API reference now uses `CLUSTER` as the `instanceType` for multi-node deployments, matching the v1.10.0 rename. Any request examples that still showed `BARE_METAL` have been updated.
***
### `v1.15.0` • 2026-04-04
#### Sesterce Persistent Volume Support
> Persistent storage is now available on Sesterce. Create volumes, pick your cloud provider and region, and attach them to instances at deploy time. Your data outlives any single session.
**New Features**
* **Sesterce Volumes:** Sesterce is now a supported volume provider. Create and manage persistent storage volumes from the `/volumes` dashboard
* **Cloud Provider + Region Picker:** When creating a Sesterce volume, choose your cloud provider and region from a dynamic dropdown so volumes are always deployed where your compute is
* **Deploy-time Attachment:** Select a compatible Sesterce volume in the deployment wizard. It attaches automatically when the instance starts, no extra steps needed
* **Automatic Compatibility Filtering:** The deployment wizard only shows volumes that match the region and cloud provider of your selected GPU offer. No risk of picking an incompatible volume
* **Volume Deletion:** Delete a Sesterce volume from the dashboard once the instance it was attached to has been terminated
**API**
Creating and using a Sesterce volume involves three steps:
1. **Fetch available cloud providers and regions:** `GET /api/volumes/regions?provider=sesterce` returns a `regions` array where each entry has an `id` (the region code), a `name`, a `cloudId`, and a `cloudName`. You need both `id` and `cloudId` when creating the volume. They must match the cloud provider and region of the instance you plan to deploy.
2. **Create the volume:** `POST /api/volumes` with `provider: "sesterce"`, `region: ""`, `cloudId: ""`, `name`, and `sizeInGb`. The response includes the volume `id` you will use when deploying.
3. **Attach at deploy time:** include `volumeIds: [""]` in your `POST /api/deployments` request. The volume attaches when the instance is created. Post-creation attach and detach are not supported for Sesterce. The volume is bound at launch.
**Compatibility:** the `cloudId` and region of your volume must match the cloud provider and region of your GPU offer. Use `GET /api/gpu-offers` to find offers and cross-reference the region before creating a volume.
**Pricing:** `GET /api/volumes/pricing?provider=sesterce` with optional `cloudId` and `region` query params returns the current hourly rate per GB for that specific location.
***
### `v1.14.6` • 2026-03-17
#### Spheron AI: Open All Inbound Ports by Default
> All ports are open out of the box. Spheron AI provider VMs now have full inbound access (TCP/UDP/ICMP, ports 1–65535, IPv4 and IPv6) applied automatically at creation time, with no manual firewall configuration required.
**Improvements**
* **Security rules at creation:** Six inbound rules (TCP 1–65535, UDP 1–65535, and ICMP for both IPv4 and IPv6) are now passed directly in the VM creation payload via the `security_rules` field, replacing the previous post-creation polling approach
* **Removed background firewall task:** Eliminated the `enableSSHFirewallWhenActive` polling loop (up to 10-minute wait) and the separate `enableSSHFirewall` method that made individual `POST /sg-rules` calls after the VM reached ACTIVE state
* **No more `sshFirewallError` tracking:** Removed the `sshFirewallErrorMap`, the `sshFirewallError` field on `VMInstance`, and all related error-surface logic. Firewall setup is now atomic with VM creation
***
### `v1.14.5` • 2026-03-16
#### GPU Count Validation Hardening
> Stricter GPU count validation. Deployment requests with a mismatched GPU count are now rejected reliably regardless of whether the value arrives as a string or a number, and validation errors are propagated correctly through the error-handling pipeline.
**Bug Fixes**
* **Type-safe GPU count comparison:** The GPU count check now coerces both the requested value and the offer config value to `Number` before comparing, preventing false validation failures caused by string/number type mismatches (e.g., `"2"` vs `2`)
* **GpuValidationError class:** Introduced a dedicated `GpuValidationError` subclass so that GPU validation errors are identified with `instanceof` rather than fragile `error.message.startsWith(...)` string matching, eliminating the risk of silently swallowing errors or misclassifying HTTP status codes if the message text changes
* **Route-level fix:** `deployment.routes.ts` now uses `instanceof GpuValidationError` to classify the error as an HTTP 400, replacing the previous `error.message.includes('Invalid GPU count:')` check
***
### `v1.14.4` • 2026-03-15
#### Feature Announcement Modal & Sidebar Changelog Link
> Stay up to date without leaving the dashboard. A new in-app feature announcement modal greets users with what's new since their last visit, and the sidebar now links directly to the changelog.
**New Features**
* **Feature Announcement Modal:** Automatically shows authenticated users any features released since their last visit. Slides through announcements newest-first with story-style progress bars, smooth slide transitions, and a 25-second auto-advance timer
* **Per-User Tracking:** Last-seen feature is persisted. The modal only re-appears when genuinely new features have shipped
* **Learn More Links:** Each announcement card links directly to the relevant docs or changelog section
* **Changelog Sidebar Link:** A compact "Changelog" entry with a "New" badge now lives in the sidebar bottom dock alongside the API Docs link, opening `docs.spheron.network/changelog` in a new tab
***
### `v1.14.3` • 2026-03-14
#### Sesterce Deployment Reliability Fix
> Sesterce deployments no longer fail on name collisions. A `409 Conflict` error that occurred when instance names clashed is now handled automatically with a unique suffix and retry logic.
**Bug Fixes**
* **409 Name Collision:** Sesterce's `/gpu-cloud/instances` API rejects duplicate instance names with a 409. Deployment names are now suffixed with a random 6-character hex string (`crypto.randomBytes(3).toString('hex')`) to prevent collisions
* **Retry Logic:** If a 409 still occurs (e.g. extremely unlikely suffix collision), the deployment automatically retries with a freshly generated name, up to 3 attempts before failing
* **Status Code on Errors:** `makeAuthenticatedRequest` now attaches `statusCode` to thrown errors, enabling reliable detection of 409 vs other failure types
* **SSH Key Cleanup:** If all retry attempts are exhausted, any provisioned temporary SSH key is deleted to prevent resource leaks
***
### `v1.14.2` • 2026-03-14
#### TensorDock Deployment Fix & Improved Error Reporting
> TensorDock deployments now work reliably. A `400 Bad Request` error that blocked all TensorDock deployments has been fixed, and deployment failures now show human-readable error messages in the dashboard.
**Bug Fixes**
* **TensorDock 400 Error:** Removed an incorrect JSON:API wrapper (`data.attributes`) that was wrapping the request payload. TensorDock's API v2 expects a flat JSON body
* **Field Name Casing:** Renamed `useDedicatedIp` (camelCase) → `use_dedicated_ip` (snake\_case) to match TensorDock's API contract
* **Cloud-Init Format:** Converted `cloud_init` from a JSON object to a YAML string, consistent with how other providers (e.g. Spheron AI provider) handle startup scripts
**Error Visibility**
* **Human-Readable Failure Reasons:** TensorDock JSON error responses are now parsed and classified into user-friendly categories (e.g. "Insufficient resources", "Invalid configuration") stored as `failureReason` on the deployment
* **Failure Details in Sidebar:** `InstanceDetailsSidebar` now surfaces `failureReason` and `failureDetails` so users can see exactly why a deployment failed without digging through logs
***
### `v1.14.1` • 2026-03-04
#### Data Crunch Shared Volume Support
> Shared NFS volumes on Data Crunch. Create persistent NFS-backed volumes, attach them to multiple instances simultaneously, and keep your data safe after instance termination.
**New Provider Support**
* **Data Crunch Volumes:** Data Crunch is now a supported volume provider. Create and manage shared NFS volumes from the dashboard or via the API
* **Multi-Instance Attachment:** A single Data Crunch volume can be attached to multiple GPU instances at the same time, unlike Voltage Park which restricts each volume to one instance
* **Region Selection:** Deploy volumes into FIN-01 (Finland 1), FIN-02 (Finland 2), or FIN-03 (Finland 3). Each volume is pinned to the region you pick at creation time
**Volume Lifecycle & Safety**
* **Persistent Volumes:** Data Crunch volumes survive instance termination by default. Only deleted on explicit user action
* **One Volume Per Instance:** Each Data Crunch instance supports at most one shared volume at a time, though that same volume can be attached to unlimited instances concurrently
**API**
Creating and using a Data Crunch volume involves three steps:
1. **Fetch available regions:** `GET /api/volumes/regions?provider=datacrunch` returns a `regions` array where each entry has an `id` (the region code to pass at creation time), a human-readable `name`, and a `country_code`. Use the `id` value as the `region` field when creating the volume.
2. **Create the volume:** `POST /api/volumes` with `provider: "datacrunch"`, `region: ""`, `name`, and `sizeInGb`. The response includes the volume `id` you will use for all subsequent operations.
3. **Attach to an instance:** two options depending on your workflow:
* At deploy time: include `volumeIds: [""]` in your `POST /api/deployments` request
* After the instance is running: `POST /api/volumes/{volumeId}/attach` with `{ "deploymentId": "" }`
**After attachment**, `GET /api/volumes/{volumeId}` returns the NFS mount command and mount path in the response. Copy these directly into your instance to mount the volume.
**Detaching and re-attaching:** `POST /api/volumes/{volumeId}/detach` with `{ "deploymentId": "" }` frees the volume to be attached elsewhere. Data is preserved.
**Pricing:** `GET /api/volumes/pricing?provider=datacrunch` returns the current hourly rate per GB so you can estimate cost before creating a volume.
***
### `v1.14.0` • 2026-03-03
#### New GPU Provider: Europe & North America Regions
> More GPUs, more regions. A new provider is now available on the Spheron AI marketplace, adding H200, H100, A100, L40S, A6000, and A4000 inventory across Canada, Norway, and the US.
**New GPU Inventory**
* **GPU Models:** H200 SXM, H100 SXM5 / NVL / PCIe, A100 SXM4 / NVL / PCIe, L40S, L40, A6000, RTX Pro 6000, A4000
* **Regions:** Canada (Montreal), Norway (Bergen), United States
* **On-Demand & Spot:** Both instance types are available. Spot instances offer the same GPU configurations at a lower price with no uptime guarantee
**Deployment Features**
* **Startup Scripts:** Cloud-init startup scripts are supported. Packages, run commands, and file writes all work on this provider the same as others
* **OS Options:** 11 OS images to choose from, including Ubuntu 22.04/24.04, AlmaLinux 9, Debian 12, and CUDA-enabled variants (R535, R550, R570). Defaults to Ubuntu Server 22.04 LTS with CUDA 12.8 and Docker
* **SSH Access:** Port 22 is automatically opened on every new instance. No manual firewall configuration needed
***
### `v1.13.1` • 2026-02-27
#### Password Complexity Enforcement on Signup
> Stronger account security. Signup now enforces password complexity rules before any Firebase call, giving users immediate, clear feedback.
**Bug Fixes**
* **Weak Password Allowed:** The signup form previously accepted any non-empty string as a password, including the user's own email address. This is now blocked
* **No Complexity Checks:** Passwords with no uppercase, no lowercase, or no digits were accepted without warning. All three are now required
**Password Rules (enforced client-side before Firebase)**
* Minimum **8 characters**
* Cannot be identical to your full email address (case-insensitive)
* Cannot be identical to the local part of your email (the portion before `@`)
* Must contain at least one **uppercase** letter
* Must contain at least one **lowercase** letter
* Must contain at least one **digit**
**UX Improvements**
* **Inline Error Messages:** Validation failures are shown immediately below the password field with a specific explanation. No generic Firebase errors
* **Live Clearing:** The error clears on every keystroke in the password field, and also when the email field is changed (prevents a stuck form if a "password too similar to email" error was triggered and the user updates their email instead)
* **Gated Submit:** The sign-up button stays disabled while a password validation error is active
***
### `v1.13.0` • 2026-02-27
#### Auto Top-Up Credits via Stripe
> Never run out of credits. Configure a balance threshold and Spheron automatically charges your saved card to keep your deployments running.
**Saved Card Management**
* **Save a Card:** Add a payment card via Stripe's hosted setup flow (no card numbers stored; only a Stripe PaymentMethod ID)
* **Card Details:** Saved card brand, last 4 digits, and expiry are shown in the billing page at all times
* **Remove Card:** Detach your saved card from Stripe entirely. This automatically disables auto top-up if it was enabled
* **Role-Gated Access:** Only team owners and admins can save or remove cards; members see card info in read-only mode
**Auto Top-Up Configuration**
* **Enable / Disable Toggle:** Turn auto top-up on or off from the billing page
* **Threshold Setting:** Set the balance level (min $5, max $500) that triggers an automatic charge
* **Top-Up Amount:** Choose how much to charge each time (min $15, max $5,000)
* **Immediate Check:** Enabling auto top-up immediately checks your balance and triggers a charge if already below threshold
* **Failure Banner:** A warning banner appears on the billing page if auto top-up was disabled due to a declined charge
**Automatic Charging**
* **Balance-Triggered Charge:** After each credit deduction cycle, if your team balance falls below the configured threshold, a Stripe off-session PaymentIntent is created and charged automatically
* **5-Minute Cooldown:** A distributed lock prevents double-charging. Top-ups cannot fire more than once every 5 minutes per team
* **Race Condition Safe:** Balance is re-fetched inside the lock before charging to prevent concurrent monitor cycles from triggering duplicate charges
* **Instant Credit:** Team balance is credited immediately on successful charge without waiting for a webhook
**Stripe Webhook Handlers**
* **`payment_intent.succeeded`:** Idempotent safety net. Credits the team if the service layer missed it (e.g. network failure mid-request)
* **`payment_intent.payment_failed`:** Automatically disables auto top-up and records `lastFailedAt` when a card is declined
**Transaction History**
* Auto top-up charges appear in Deposit History labeled **"Auto Top-Up"** with a distinct badge, clearly separated from manual credit purchases
**Email Notifications**
* **Success Email:** Confirms the charge amount and shows the new account balance
* **Failure Email:** Notifies the configuring user that their card was declined and auto top-up has been disabled, with a direct link to re-enable
***
### `v1.12.2` • 2026-02-27
#### Mandatory Phone Number on Reserved GPU Form
> Required contact info. Phone number is now enforced end-to-end so reserved GPU requests always include reachable contact details.
**Bug Fixes**
* **Mandatory Phone Field:** Phone number is now a required field on the Reserved GPU request form. The label, frontend validation, and server-side validation all enforce it
* **Format Validation:** Phone input is validated against a format check (supports `+`, digits, spaces, dashes, parentheses, e.g. `+1 555-123-4567` or `(555) 123-4567`) with a minimum of 7 digits, on both client and server
* **Review Step Gate:** If contact info (including phone) is incomplete when the user reaches the review step, the wizard redirects back to the contact form with a clear "Contact Info Required" toast notification
* **Backwards Compatibility:** Existing reservations without a phone number are unaffected. The schema change is non-breaking for legacy documents
***
### `v1.12.1` • 2026-02-23
#### Zero-Downtime Deployment & Faster Container Restarts
> Instant restarts, no build delays. App builds are now baked into the Docker image so containers spin up in seconds instead of minutes.
**Deployment Scripts**
* **Zero-Downtime Deploy:** New `script/deploy.sh` for all the apps. Builds the new image while the current container keeps serving traffic, then hot-swaps to the new container with no manual downtime
* **Health-Gated Rollout:** The deploy script waits for Docker's health check to pass (up to 120s) before declaring success, ensuring the new container is fully ready before traffic is handed off
**Docker Image Optimizations**
* **Build at Image Time:** `npm run build` now runs during `docker build` (image layer) instead of at container startup. Containers start in seconds rather than waiting for a full compile
* **Health Checks Added:** All app's Dockerfiles now include `HEALTHCHECK` directives with 10s intervals and 30s start periods so Docker and the deploy script can reliably detect readiness
***
### `v1.12.0` • 2026-02-23
#### Volume Management UI for Voltage Park
> Full persistent storage experience. Create, browse, attach, detach, resize, and monitor volumes directly from the dashboard.
**New Pages**
* **Volumes Page** (`/volumes`): Dedicated page to view and manage all your persistent storage volumes in one place, with status badges, provider/region info, hourly rates, and quick actions
* **Create Volume Page** (`/create-volume`): Step-by-step wizard to create a new volume. Select a provider, configure name, size, region, and lifecycle settings before reviewing the cost summary
**Volume Management**
* **Volume Cards:** Each volume displays its name, size, provider, region, status (available, attached, creating, deleting, error), and current cost, with one-click copy for Volume ID
* **Volume Details Sidebar:** Click any volume to open a detailed side panel showing overview, configuration, storage usage metrics, and attached instances
* **Attach to Deployment:** During the deployment wizard, an "Attach Volumes" step surfaces compatible volumes (same provider and region) and lets you select one to attach before launch
* Voltage Park instances support **1 volume per instance**. The UI enforces this limit automatically
* **Detach Volume:** Detach a volume from a running instance directly from the instance detail sidebar or the volumes page, without losing data
* **Resize Volume:** Expand a volume's storage size on-demand from the volumes page (shrinking is not supported)
* **Delete Volume:** Delete a volume (must be detached first) with a confirmation dialog
**Instance Detail Sidebar**
* New **Attached Volumes** card visible on each running instance showing all volumes currently mounted, their size, hourly cost, and a detach action
**Navigation**
* **Volumes** and **Create Volume** entries added to the sidebar for quick access
**Smart Behaviors**
* Volume selection resets automatically when you switch providers or networking type in the deployment wizard
* Volume size input clamps to the provider's supported min/max range and rounds to a whole number
* Region matching is normalized so minor formatting differences (e.g. `us-east-1` vs `US East 1`) don't prevent valid volumes from appearing
* Provider pricing is validated before allowing volume creation. A clear error is shown if pricing is unavailable for the selected provider/region
**Pricing & Cost Display**
* Hourly and monthly cost estimates shown in real-time while configuring volume size
* Order summary in the create wizard shows total hourly cost and projected 30-day cost before confirming
**API Endpoints (unchanged from v1.11.0, now fully surfaced in UI)**
* `GET /api/volumes`: list volumes (filterable by team, status, provider)
* `POST /api/volumes`: create volume
* `GET /api/volumes/:volumeId`: volume details with live usage data
* `PATCH /api/volumes/:volumeId`: rename, resize, or update lifecycle settings
* `DELETE /api/volumes/:volumeId`: delete volume
* `POST /api/volumes/:volumeId/attach`: attach to a deployment
* `POST /api/volumes/:volumeId/detach`: detach from a deployment
* `GET /api/volumes/pricing`: storage pricing by provider
### `v1.11.1` • 2026-02-13
#### Kubernetes Add-on for Voltage Park
> **Managed Kubernetes clusters** on bare-metal GPU instances with automatic provisioning, kubeconfig access, and health monitoring.
**New Features**
* **Kubernetes Cluster Deployment:** Deploy fully managed Kubernetes clusters on Voltage Park bare-metal GPU instances
* **Version Selection:** Choose from multiple Kubernetes versions (1.35, 1.34, 1.33, 1.32) with automatic validation
* **Automatic Provisioning:** Kubernetes clusters are automatically provisioned and configured during instance deployment
* **Kubeconfig Access:** Download kubeconfig files directly from deployments for immediate kubectl access
* **Cluster Health Monitoring:** Real-time health tracking for control plane nodes, worker nodes, and network components
* **Grafana Integration:** Built-in Grafana monitoring links for cluster observability and metrics
* **Custom Authentication:** Optional support for custom Kubernetes AuthenticationConfiguration YAML
* **Persistent Cluster State:** Cluster configurations persist independently from instance lifecycle
**Technical Implementation**
* **Provider Validation:** Automatic validation ensures Kubernetes add-ons are only used with Voltage Park bare-metal instances
* **Version Validation:** Server-side version checking against provider-supported Kubernetes releases
* **Base64 Encoding:** Secure transmission of authentication configurations via base64 encoding
* **Monitoring Service:** Background service updates cluster health and configuration data automatically
**API Endpoints**
* `GET /api/kubernetes/versions?provider=voltage-park`: List available Kubernetes versions
* `GET /api/kubernetes/:clusterId/health`: Get cluster health status with node and network component metrics
* `POST /api/deployments` with `kubernetesAddon` object: Create deployment with Kubernetes cluster
**Deployment Requirements**
* **Provider:** Voltage Park only (other providers not yet supported)
* **Instance Type:** CLUSTER deployments only for H100 SXM5
* **Operating System:** Compatible with TensorML and other Voltage Park OS images
### `v1.11.0` • 2026-02-07
#### Persistent Storage Volumes
> **Persistent storage for GPU instances** with flexible volume management and deployment attachment.
**New Features**
* **Volume Management:** Create, update, and delete persistent storage volumes independent of GPU instances
* **Flexible Attachment:** Attach and detach volumes to/from running deployments without losing data
* **Multi-Provider Support:** Volume storage available across supported providers (Voltage Park, etc.)
* **Size Flexibility:** Configure volumes from 1GB to 10TB with dynamic expansion support
* **Automatic Billing:** Hourly billing based on storage size with transparent pricing per GB
* **Usage Tracking:** Real-time monitoring of used capacity and storage metrics
* **Smart Lifecycle Management:** Choose whether volumes persist after instance termination or delete automatically
* **Credit Validation:** Automatic validation ensures sufficient credits before volume creation (24-hour minimum)
**Volume Features**
* **Independent Lifecycle:** Volumes persist independently from GPU instances by default
* **Cross-Instance Sharing:** Attach a single volume to multiple instances (provider-dependent)
* **Capacity Expansion:** Expand volume size on-demand (shrinking not supported for data safety)
* **Name Validation:** Alphanumeric naming with hyphens/underscores (max 60 characters)
* **Status Tracking:** Real-time status monitoring (available, attached, deleting, deleted)
* **Automatic Cleanup:** Orphaned volume references automatically cleaned from deployments
**API Endpoints**
* `GET /api/volumes`: List all volumes for a team with pagination and filtering
* `POST /api/volumes`: Create new persistent storage volume
* `GET /api/volumes/:volumeId`: Get volume details with fresh usage data
* `PATCH /api/volumes/:volumeId`: Update volume name, size, or lifecycle settings
* `DELETE /api/volumes/:volumeId`: Delete volume (must be detached first)
* `POST /api/volumes/:volumeId/attach`: Attach volume to a deployment
* `POST /api/volumes/:volumeId/detach`: Detach volume from deployment
* `GET /api/volumes/pricing`: Get storage pricing by provider
**Technical Improvements**
* **Provider Consistency:** Volumes and deployments must be from the same provider for attachment
* **Atomic Operations:** Provider updates happen before database updates to maintain consistency
* **Graceful Cleanup:** Automatic cleanup of volume references when deployments are deleted
* **Audit Logging:** Complete audit trail for all volume lifecycle events
### `v1.10.1` • 2026-01-14
#### Reserved Instance Management
> **Dedicated GPU leasing** for users who have contacted the team and secured reserved GPU nodes.
**New Features**
* **Reserved Instance Display:** Users who have leased GPU nodes directly with Spheron AI can now view their reserved instances in the marketplace
* **Direct Leasing Support:** Seamless integration for customers who have contacted the team for bulk GPU reservations
* **Dedicated Node Access:** Reserved instances provide exclusive access to pre-allocated GPU nodes with guaranteed availability
* **Custom Configurations:** Support for custom GPU configurations negotiated directly with the Spheron AI team
**Improvements**
* **Enhanced Visibility:** Reserved instances are clearly labeled and distinguished from on-demand offerings
* **Better Management:** Improved interface for tracking and managing leased GPU resources
* **Streamlined Experience:** Integrated workflow for users with both reserved and on-demand instances
### `v1.10.0` • 2026-01-08
#### Cluster Deployments & Baremetal GPU Offers
> **Multi-node cluster support** with enhanced baremetal GPU offerings and clearer deployment terminology.
**New Features**
* **Cluster Deployment Support:** Multi-node GPU clusters are now clearly labeled and supported throughout the platform
* **Baremetal GPU Offers:** New baremetal GPU configurations added to the marketplace for dedicated hardware performance
* **Improved Nomenclature:** Voltage Park's H100 SXM5 offerings now accurately labeled as "H100 SXM5 Cluster" instead of "Baremetal" for better clarity
* **Better GPU Classification:** Enhanced distinction between single-node baremetal instances and multi-node cluster deployments
**Improvements**
* **Clearer Labels:** Deployment types are now more accurately labeled to help users understand exactly what they're deploying
* **Enhanced Discovery:** Cluster and baremetal options are now easier to find and understand in the GPU marketplace
* **Consistent Terminology:** Standardized naming conventions across all providers for better user experience
### `v1.9.7` • 2026-01-06
#### Intercom Live Chat Support
> **Get instant help** with integrated Intercom messenger for real-time customer support and assistance.
**New Features**
* **Live Chat Widget:** Intercom messenger widget integrated throughout the platform for instant support access
* **Identity Verification:** Secure user authentication with HMAC-SHA256 hash-based identity verification to prevent user impersonation
* **User Context:** Automatic user data synchronization (name, email, account creation date) for personalized support experience
* **Anonymous Visitor Support:** Non-authenticated visitors can still access support through anonymous chat sessions
* **Smart Session Management:** Automatic session handling when users log in, log out, or switch accounts
* **Seamless Integration:** Support chat available on all pages without disrupting your workflow
### `v1.9.6` • 2025-12-30
#### Deployment Termination Controls
> **Critical Fix:** Strict termination controls prevent premature instance termination and ensure proper billing accuracy.
**Breaking Changes**
* **Status-Based Termination:** Only instances with `running` status can now be terminated manually
* `deploying` instances cannot be terminated (must wait until running or automatic failure)
* `failed`, `terminated`, and `terminated-provider` instances are already in final states
* **Minimum Runtime Enforcement:** Running instances must meet the 20-minute minimum runtime requirement before termination
**Bug Fixes**
* Fixed incorrect status semantics: Deployments that never started running are now marked as `failed` instead of `terminated`
* Fixed API key users being able to bypass minimum runtime checks by terminating during `deploying` status
* Fixed deployments showing "terminated" with N/A runtime and $0.00 cost (now correctly marked as `failed`)
* Added proper error messages for termination attempts on non-running instances
**New Features**
* **Improved Error Messages:** Status-specific error messages guide users on correct actions
* Clear explanations for why termination is blocked
* Helpful guidance on what to do next
* **Frontend Error Handling:** Enhanced UI feedback for termination failures
* Status-specific toast messages
* Better user experience during edge cases
**Technical Changes**
* Updated GET `/api/deployments/:id/can-terminate` endpoint with status validation
* Updated DELETE `/api/deployments/:id` endpoint with strict pre-termination checks
### `v1.9.5` • 2025-12-30
#### Flexible Storage Options for Data Crunch
> **Choose your storage size** when deploying Data Crunch dedicated instances with new 500GB and 1TB options.
**New Features**
* **Storage Size Selection:** Data Crunch dedicated instances now offer two storage options:
* **500GB Standard:** Default option with $0.137/hr storage pricing
* **1TB Extended:** Expanded storage option with $0.274/hr storage pricing
* **Clear Pricing Display:** Storage costs are shown separately in the deployment wizard for transparent pricing
* **Smart Defaults:** 500GB storage is automatically selected when configuring Data Crunch dedicated instances
* **Flexible Configuration:** Easily switch between storage sizes to match your workload requirements
**Technical Notes**
* Storage property is now included in GPU offer configurations for Data Crunch dedicated instances
* Pricing calculations properly account for storage costs in commission-adjusted totals
### `v1.9.4` • 2025-12-25
#### OTP Verification for Reserved GPU Requests
> **Enhanced security** for bulk GPU reservations with email-based OTP verification.
**New Features**
* **OTP Verification Flow:** Reserved GPU requests now require email verification via one-time password (OTP) for added security
* **Email OTP Delivery:** Receive a verification code via email when submitting a reserved GPU request
* **OTP Resend Option:** Didn't receive the code? Request a new OTP to be sent to your email
* **Session Management:** OTP verification sessions are securely managed with automatic expiration
* **Rate Limiting:** OTP requests are rate-limited to prevent abuse and ensure system stability
### `v1.9.3` • 2025-12-25
#### API Access Control & Runtime Policies
> **Controlled API access** with whitelist-based key generation and enforced minimum runtime for deployments.
**New Features**
* **API Key Whitelisting:** API key generation is now controlled through a whitelist system. Contact support to request API access
* **Whitelist Status Visibility:** Users can now see their API access status clearly in the settings interface
* **Minimum Runtime Enforcement:** Deployments now require a **20-minute minimum runtime** before termination to prevent accidental early shutdowns
* **Runtime Protection:** Destroy action is automatically disabled during the minimum runtime period with a helpful countdown timer
* **System Configuration API:** New endpoint (`GET /api/config/system`) exposes system configuration including minimum runtime requirements
* **Termination Validation:** New endpoint (`GET /api/deployments/:id/can-terminate`) checks if an instance can be safely terminated
**Improvements**
* **Enhanced Rate Limiting:** Deployment creation now limited to **5 deployments per hour per user** for better platform stability and abuse prevention
* **Better API Key Handling:** Improved handling of empty or undefined API keys in the UI
* **Deployment Wizard Updates:** SSH key step now displays minimum runtime requirements upfront
* **Clear User Feedback:** Disabled actions now include tooltips explaining why they're unavailable and when they'll be enabled
**API Changes**
* `GET /api/config/system`: Returns system configuration including minimum runtime settings
* `GET /api/deployments/:id/can-terminate`: Validates if deployment can be terminated
* `DELETE /api/deployments/:id`: Enforces minimum runtime checks before allowing termination
* `POST /api/deployments`: Enhanced with rate limiting
### `v1.9.2` • 2025-12-22
#### Christmas Promo & Active Discount Display
> **Time-limited promotional discounts** with automatic activation and clear discount visibility.
**New Features**
* **Christmas Promo:** Special time-limited discount offers appear automatically to eligible users with easy one-click activation
* **Active Discount Display:** Your current discount percentage and expiration date are now prominently shown on the billing page
* **Clear Savings:** See exactly how much you're saving with active discounts applied to your usage
### `v1.9.1` • 2025-12-20
#### Reserved GPU Offers
> **Smarter GPU reservation options** with detailed specifications.
**Reserved GPU Offers**
* **Two Display Modes:** Reserved GPU offers now support two presentation styles:
* **Tiers Mode:** Compare multiple pricing tiers (up to 3) with flexible commitment options, perfect for understanding pricing at different commitment levels
* **Specs Mode:** View detailed technical specifications including vCPUs, RAM, storage, connectivity type, and deployment method (Bare Metal or VM), ideal for understanding exact hardware configurations
* **Regional Availability:** GPU offers now display available regions, making it easier to choose deployments close to your users
* **Better Descriptions:** Hover over offer descriptions to see full details without cluttering the interface
* **Improved Reservation Flow:** When clicking "Reserve" on an offer, relevant details (specs, regions, pricing) are now pre-filled in the reservation form for faster booking
### `v1.9.0` • 2025-12-18
#### Major Frontend Refactor
> **Complete codebase modernization** with modular components, centralized hooks, and improved UX.
**Routing & Layout**
* Introduce new routing and layout components
* Split PublicLayout and Sidebar into components/shared
**Billing & Payments**
* Refactor AddCreditsTab into modular components
* Powered by new usePayment hook and usePaymentCallback
* Move deposit dialog to TopNavBar subcomponents
**API Documentation**
* Break ApiDocumentation into composable sections and utils/types
**Instances & Deployments**
* Modularize Card and Sidebar into subcomponents
* Rebuild pages/instances.tsx using new grid/header/empty/error components with infinite loading
**Shared Components & UI**
* Extract Sidebar and TopNavBar for reusability
* Normalize toast hook path (useToast)
**UX Improvements**
* All modals now wait for API completion before closing
* Fixed React Hooks violations with proper hook ordering
* Team switcher dropdown now works correctly
* Better loading states and error handling throughout
### `v1.8.2` • 2025-12-17
#### Higher Deposit Limits & New Credit Packages
> **Deposit up to $5,000** with new bulk credit packages for larger workloads.
**New Features**
* **Increased Deposit Limits:** Maximum deposit raised from $1,000 to **$5,000** for teams with larger GPU requirements
* **New Credit Packages:** Added **$500**, **$1,000**, and **$5,000** quick purchase options for bulk credits
* **Clear Limit Display:** Deposit limits are now prominently displayed in the UI for transparency
* **Package Validation:** UI automatically prevents purchases outside allowed limits with helpful error messages
* **Better Formatting:** Large numbers now display with proper comma formatting for easier reading
**Improvements**
* **Dynamic Configuration:** Deposit limits and referral rewards are now centrally managed for consistency
* **Referral Page Updates:** Referral reward amounts and minimum deposit requirements are now displayed accurately throughout
* **Enhanced UX:** Improved handling of edge cases when selecting credit packages
### `v1.8.1` • 2025-12-17
#### Search Improvements
> **Enhanced GPU search** with better filtering and improved reliability.
**Improvements**
* **Reserved GPU Search:** Search now properly filters reserved GPU offers. When you search for "H100", only H100 models will appear in results
* **More Accurate Results:** Improved search matching ensures you see only relevant GPU configurations
* **Better Performance:** Enhanced search processing for faster and more reliable results
* **Consistent Experience:** Search behavior is now unified across all GPU offer types
### `v1.8.0` • 2025-12-16
#### Referral Program Launch
> **Earn rewards by referring friends!** Get **$5** credit when your referral deposits **$100**.
**New Features**
* **Referral Dashboard:** Access your unique referral link and track your referrals
* **Shareable Links:** Easy sharing via Twitter, LinkedIn, and direct link copying
* **Automatic Tracking:** Referrals are automatically tracked when someone signs up using your link
* **Instant Rewards:** Credits are automatically added to your account when referrals make qualifying deposits
* **Discount Codes:** New ability to validate and apply discount codes to your account
* **Enhanced Transaction History:** Referral bonus deposits are now clearly labeled in your transaction history
### `v1.7.0` • 2025-11-20
#### Email Notifications & Credit Monitoring
> **Stay informed with professional email notifications** and proactive balance alerts.
**New Features**
* **Enhanced Email Notifications:** Improved email design for welcome messages, deployment updates, and account alerts
* **Smart Low Balance Alerts:** Receive notifications when your balance reaches **$50**, **$20**, **$10**, or **$5** to avoid service interruption
* **Balance Exhaustion Alerts:** Get notified when your balance reaches **$0** and deployments are automatically stopped
* **Rate-Limited Notifications:** Smart notification system prevents email spam with 6-hour intervals between similar alerts
* **Priority Notification Delivery:** Account owners and admins receive critical balance alerts first
### `v1.6.0` • 2025-10-29
#### Transaction Receipts & Improved Navigation
> **Download payment receipts** and enjoy **faster page loading** with improved pagination.
**New Features**
* **Receipt Downloads:** Download official receipts for all completed deposits (Stripe & CopperX payments)
* **Deposit History:** Renamed transaction view to "Deposit History" for better clarity
* **Paginated Views:** Faster loading with pagination across deployment history and usage analytics
* **Load More Button:** Browse through your instances with easy "Load More" functionality
* **Documentation Access:** Quick access to API documentation directly from the navigation menu
**Improvements**
* **Loading States:** Better visual feedback with loading skeletons while data loads
* **Error Handling:** Improved error messages and handling throughout billing and instances pages
* **Performance:** Faster page loads with optimized data fetching
### `v1.5.0` • 2025-10-18
#### Complete UI Redesign
> **Modern dark theme** with sleek blue gradients and enhanced user experience throughout the platform.
**Visual Overhaul**
* **Modern Dark Theme:** New dark interface with blue gradient accents and improved contrast
* **Redesigned Cards:** Sleek card designs with unique clipped borders for a futuristic look
* **Enhanced Buttons:** Modern call-to-action buttons with hover effects and smooth transitions
* **Improved Typography:** Updated fonts and text hierarchy for better readability
**Page Improvements**
* **Billing Dashboard:** Completely redesigned with clear balance overview, streamlined deposit flow, and organized transaction history
* **Instance Management:** Improved instance cards with better status indicators and enhanced SSH key management
* **Settings Interface:** Modern tabbed navigation with refreshed profile, SSH key, and API key management sections
* **Deployment Wizard:** Enhanced GPU browsing experience with improved provider, region, and configuration selection
* **Reserved GPU Portal:** New design for bulk GPU reservation requests with better quote workflow
**User Experience**
* **Faster Loading:** Optimized loading and redirect screens
* **Better Navigation:** Improved top navigation and sidebar with clearer menu organization
* **Enhanced Dialogs:** Modern confirmation dialogs with better visual feedback
* **Consistent Design:** Unified design language across all pages and components
### `v1.4.0` • 2025-09-28
#### Reserved GPU Pricing & Compliance
**New Features**
* **Reserved GPU Pricing:** Special pricing model for long-term GPU reservations
* **Provider Compliance Status:** View compliance and certification status for each provider during deployment
* **Flexible SSH Key Options:** Enhanced SSH key support for programmatic deployments
**Improvements**
* **Better Pricing Display:** Improved GPU offer pricing calculations and display
* **Enhanced Security:** Stronger SSH key validation and processing
* **System Stability:** Improved reward processing reliability
### `v1.3.0` • 2025-09-02
#### Onboarding & Discounts
**New Features**
* **Welcome Onboarding:** New user onboarding flow to help you get started quickly
* **Discount Codes:** Support for promotional and discount codes
* **Reserved GPU Marketplace:** New page for requesting bulk GPU reservations from our provider network
**Improvements**
* **Accurate Billing:** Fixed credit deduction and monitoring for precise billing
* **Better Calculations:** Improved accuracy in usage cost calculations
### `v1.2.0` • 2025-08-12
#### API Access & New Provider
**New Features**
* **API Key Management:** Create and manage deployments programmatically using API keys
* **Massed Compute Provider:** New provider option for more GPU choices and competitive pricing
* **Multi-Node Deployments:** Deploy multiple GPU nodes simultaneously with Voltage Park for larger workloads
### `v1.1.0` • 2025-07-25
#### Startup Scripts & Discounts
**New Features**
* **Startup Scripts:** Add custom initialization scripts that run automatically when your instance starts
* **Usage Discounts:** Discount system for reduced pricing on GPU usage
**Improvements**
* **Real-Time Pricing:** Fixed spot pricing updates for accurate availability and costs
* **Accurate GPU Selection:** Improved pricing calculations during GPU selection
### `v1.0.0` • 2025-07-04
#### Initial Release
**Welcome to Spheron AI GPU Marketplace!**
The easiest way to rent high-performance GPUs on-demand from multiple providers.
**Core Features**
* **Multiple GPU Providers:** Access GPUs from Voltage Park, Data Crunch, Sesterce, and TensorDock
* **Simple Authentication:** Sign in with Google, GitHub, or email
* **Team Management:** Create and manage teams for collaborative work
* **Flexible Billing:** Pay with crypto or credit card
* **Usage Analytics:** Track your GPU usage and spending in real-time
* **Transaction History:** Complete history of all your deposits and usage charges
:::
## Cost optimization
This page covers strategies for reducing compute costs on Spheron, including moving non-GPU work to CPU nodes, GPU tier selection, instance type trade-offs, reserved GPU savings, and spend monitoring.
### Move non-GPU work to CPU nodes
The largest saving is not renting a GPU at all. Data preprocessing, ETL, build steps, schedulers, queue workers, and API front ends never touch CUDA, and running them on a GPU instance wastes the accelerator you are paying for.
[CPU Node](/concepts/cpu-nodes) starts at **$0.09/hr** on Verda spot, against \~$0.25/hr for the cheapest GPU spot instance and several dollars per hour for an H100. Sizes start at 4 vCPU with 4 GB of memory. Check the [Deploy CPU page](https://app.spheron.ai/deploy-cpu) for the sizes on offer right now.
**Split a pipeline across both:**
1. Preprocess and shard the dataset on a CPU node, writing to a [persistent volume](/connecting/volume-mounting).
2. Attach the same volume to a GPU instance and run training.
3. Terminate the GPU instance the moment training finishes; leave the CPU node running for postprocessing if needed.
Deploy CPU nodes from **Deploy CPU** in the dashboard sidebar, or through the API with `computeType=cpu`.
### GPU tier selection matrix
Choose the right GPU tier based on how much VRAM your workload needs:
| VRAM needed | GPU | Type | Approx. $/hr | Best for |
| --------------- | ---------------------- | -------------- | ------------ | ------------------------------------------ |
| None | CPU Node (from 4 vCPU) | Dedicated/Spot | From $0.09 | Data prep, builds, schedulers, API workers |
| Less than 16 GB | RTX 4090 (24 GB) | Dedicated/Spot | \~$0.25-0.55 | Dev, inference, fine-tuning |
| 40 GB | A100 40 GB | Dedicated/Spot | Variable | Mid-scale training |
| 80 GB | A100 80 GB / H100 | Dedicated | Variable | Large model training |
| 640 GB+ | 8x H100 NVLink | Cluster | \~$15+/hr | Distributed training, K8s |
Check current prices in the dashboard; prices vary by provider and availability.
### Instance type strategy
#### Spot (lowest cost)
Spot instances are 30-60% cheaper than Dedicated. The trade-off: the provider can reclaim them at any time.
**Use Spot for:**
* Experiments and hyperparameter search
* Batch training jobs with checkpoint saving enabled
* Any workload under 4 hours that can tolerate interruption
**Handling interruption:** Save checkpoints to a persistent volume every N steps. If the instance is reclaimed, resume from the latest checkpoint on a new instance without losing progress.
```python
# Save checkpoint every 100 steps
if step % 100 == 0:
torch.save(state, '/checkpoints/checkpoint_latest.pt')
```
#### Dedicated (guaranteed)
Dedicated instances cannot be reclaimed. Use them when interruption would be costly:
* Production inference servers
* Multi-day training runs
* Interactive workloads and demos
#### Cluster (largest scale)
Full physical servers with NVLink interconnects. Use for:
* Multi-GPU distributed training (PyTorch DDP, DeepSpeed)
* Workloads requiring maximum GPU-to-GPU bandwidth
* Jobs sensitive to virtualization overhead
### Stop an instance instead of leaving it running
An instance you are coming back to does not have to keep paying for its GPU. Stopping releases the GPU, keeps the disk and everything on it, and bills only for the retained disk plus the public IP where the provider charges for one. Starting it again returns the same disk, the same contents, and the same public IP.
This is the cheapest option for work that pauses rather than ends:
* An environment you spent hours building and will use again tomorrow
* A dataset already downloaded to the boot disk that you do not want to fetch twice
* An overnight or weekend gap in an otherwise active project
Stopping is available on Spheron AI and Spheron ES, and on Spheron AI it depends on the machine type and region. Verda, Sesterce, Spheron MS, and Massed Compute keep billing at the full rate until an instance is destroyed. Check the note in the deploy summary before you commit.
:::warning[Stopped is not free, and not permanent]
A stopped instance still costs its disk rate, and a team that runs out of credit has every instance destroyed, stopped ones included. Terminate an instance you are genuinely finished with. See [Instance lifecycle](/concepts/instance-lifecycle).
:::
### Reserved GPUs for long-term work
For multi-week or multi-month projects, Reserved GPUs offer significant savings:
* Submit requests via dashboard > **Reserved GPU**
* Multiple providers compete to offer the lowest price
* Typical savings: 30-50% vs on-demand hourly rates for 3-12 month commitments
* Select "Any Location" to maximize provider competition
See [Reserved GPUs](/reserved-gpus) for the request form.
### Team discount program
Teams with active discounts automatically see reduced prices on the dashboard. The discounted price is applied at deployment without any additional steps.
* Discounts are either volume-based or admin-assigned; the higher of the two is applied automatically
To inquire about discount eligibility for high-volume usage, use the chat widget on [app.spheron.ai](https://app.spheron.ai) or email [info@spheron.ai](mailto\:info@spheron.ai).
### Monitoring burn rate
#### Check remaining balance
View your current credit balance on the **Billing** page in the dashboard. The balance updates in real time as instances run.
#### Track per-instance spend
Open the instance details drawer from the **Instances** page to see the hourly rate and total cost accumulated for a running deployment.
#### Stop or terminate when done
Terminate instances from the dashboard as soon as your workload finishes to stop charges immediately. Navigate to **Instances**, select the instance, and click **Terminate**.
When you will return to the same environment, click **Stop** instead where the provider offers it. The GPU stops billing, the disk is preserved, and you start it again without rebuilding. The dialog quotes both rates before you commit.
Set up balance alerts in [User Settings](/user-settings) to receive a notification before credits run out.
### Practical tips
**Use persistent volumes for datasets and model weights.** Avoid re-downloading multi-GB datasets on every deployment; mount a volume with data pre-loaded. This saves both time and egress costs.
**Prefer Spot for short jobs.** Any job under 4 hours that can be checkpointed is a good Spot candidate. Switch to Dedicated for multi-day runs requiring uninterrupted time.
**Batch GPU use.** Avoid leaving instances running idle. Terminate immediately when your job finishes, or stop the instance when you will return to the same environment, and re-deploy from a checkpoint when neither applies.
**Use RTX 4090 for development.** The RTX 4090 is the most cost-effective GPU for code iteration, small model experiments, and inference serving at low traffic. Move to A100/H100 only when VRAM or compute requirements demand it.
### What's next
* [Instance Types](/concepts/instance-types): Detailed Spot/Dedicated/Cluster comparison
* [Regions & Providers](/concepts/regions-providers): Provider capabilities and GPU tiers
* [Reserved GPUs](/reserved-gpus): Long-term GPU reservation form
* [Instance Lifecycle](/concepts/instance-lifecycle): Stop and start an instance to pause GPU billing
* [Billing](/billing): Credit management, auto top-up, and team discounts
* [Volume mounting](/connecting/volume-mounting): Persistent storage for datasets and checkpoints
## General information
This page lists official Spheron channels, support options, and answers to common questions.
### Official channels
#### Social media
* **X (Twitter)**: [https://x.com/spheronai](https://x.com/spheronai)
* **LinkedIn**: [https://www.linkedin.com/company/spheron-ai/](https://www.linkedin.com/company/spheron-ai/)
* **GitHub**: [https://github.com/spheron-core](https://github.com/spheron-core)
* **Blog**: [https://blog.spheron.network](https://blog.spheron.network)
#### Official sites
* **Main website**: [https://spheron.ai](https://spheron.ai)
* **Platform app**: [https://app.spheron.ai](https://app.spheron.ai)
* **Documentation**: [https://docs.spheron.ai](https://docs.spheron.ai)
:::warning
Always verify URLs before entering credentials. Spheron will never ask for your passwords, API keys, or private SSH keys.
:::
### Support
* **Chat support**: Use the chat widget on [spheron.ai](https://app.spheron.ai) for real-time assistance
* **Documentation**: Browse guides and tutorials on this site
* **Official contact**: Fill out the contact form on [spheron.ai](https://spheron.ai/contact) for specific inquiries
### Quick navigation
* **Getting started**: [Getting Started Guide](/getting-started) | [Quick Start](/quick-start)
* **Platform info**: [Overview](/overview) | [Concepts](/concepts) | [CPU Nodes](/concepts/cpu-nodes)
* **Technical**: [API Reference](/api-reference) | [Connecting to instances](/connecting)
* **Resources**: [Deploy Guides](/quick-guides) | [Reserved GPUs](/reserved-gpus) | [Billing](/billing)
### FAQs
**Q:** How do I get started?
**A:** See the [Getting Started](/getting-started) guide to deploy your first instance in 5 minutes.
**Q:** Where can I get help?
**A:** Use the chat support on [spheron.ai](https://app.spheron.ai) or check the documentation for guides and troubleshooting.
**Q:** What is the pricing?
**A:** Check [Billing](/billing) for detailed pricing. Spheron is 60-80% cheaper than traditional clouds.
**Q:** Is there an API?
**A:** Yes. See [API Reference](/api-reference) for full documentation.
### Important links
* [Platform overview](/overview): Learn about Spheron
* [Security best practices](/security): Keep your account secure
* [User Settings](/user-settings): Manage your account
* [Terms of Service](https://www.spheron.ai/SpheronAI_Website_Terms_of_Use.pdf): Available on [spheron.ai](https://spheron.ai)
### What's next
* [Getting Started](/getting-started): Deploy your first GPU instance
* [Overview](/overview): Platform features and use cases
* [Security best practices](/security): Protect your account and instances
* [Billing](/billing): Credits, pricing, and payment methods
## Getting started
This guide takes you from account creation to a deployed and verified GPU instance in about 10 minutes.
**Already have an account?** Jump to [Quick Start](/quick-start) for fast deployment.
### Prerequisites
Before deploying, complete these setup steps:
* A Spheron AI account (created in Step 1 below)
* An SSH key pair (generated in Step 3 below)
* Credits added to your account (added in Step 2 below)
### Step 1: Create your account
#### Sign up
1. Visit [app.spheron.ai](https://app.spheron.ai)
2. Click **Sign Up**
3. Choose a sign-up method:
* Google account
* GitHub account (recommended for developers)
* Email and password
4. Complete email verification if using email signup
#### Navigate the dashboard
Once logged in, the sidebar groups every page under three headings:
**Compute**
* **Deploy GPUs**: Browse the GPU catalog and launch a GPU instance
* **Deploy CPU**: Launch a [CPU-only node](/concepts/cpu-nodes) for work that never touches a GPU
* **Create Volume**: Provision persistent storage
* **Reserved GPUs**: Request long-term reserved capacity
**Manage**
* **Instances**: Manage active deployments
* **Volumes**: Manage persistent volumes
**Account**
* **Billing**: Add credits, view balance, and track usage
* **Team**: Invite members and set roles
* **Settings**: Profile, SSH keys, API keys, alerts, and notifications
A theme switch at the bottom of the sidebar toggles between light and dark mode. Your choice is remembered across sessions.
### Step 2: Add billing
#### Add credits
1. Open **Billing** from the sidebar under **Account**
2. Choose a payment method:
* Credit/Debit Card
* Stables (USDC/USDT)
3. Add initial credits (minimum $15, maximum $5,000 per transaction)
**Pricing:** Pay-per-second billing with no hidden fees. See [Billing](/billing) for detailed pricing.
:::tip
Start with $15-$50 for testing. RTX 4090 costs \~$0.52/hour. Minimum deposit is $15.
:::
### Step 3: Set up SSH access
SSH keys are required to access your GPU instances securely.
#### Generate SSH key
**On Linux/Mac:**
```bash
# Generate new SSH key
ssh-keygen -t ed25519 -C "your_email@example.com"
# Press Enter to save to default location
# Set a passphrase (optional but recommended)
# Display your public key
cat ~/.ssh/id_ed25519.pub
```
**On Windows (PowerShell):**
```bash
# Generate new SSH key
ssh-keygen -t ed25519 -C "your_email@example.com"
# Display your public key
type $env:USERPROFILE\.ssh\id_ed25519.pub
```
#### Upload SSH key to Spheron
1. Go to [User Settings](https://app.spheron.ai/settings)
2. Navigate to the **SSH Keys** section
3. Click **Add SSH Key**
4. Paste your public key (the one ending in `.pub`)
5. Give it a memorable name (e.g., "My Laptop")
6. Click **Save**
:::warning
Never share your private key. Only upload the public key (`.pub` file) to Spheron.
:::
### Step 4: Deploy your first instance
#### Navigate to deploy
1. Click **Deploy GPUs** in the left sidebar under **Compute**
2. Browse the GPU catalog
Your search, sort, provider, and region filters persist in the address bar. Refreshing keeps the view you were looking at, and copying the link opens the same filtered catalog for a teammate.
:::tip[Not every job needs a GPU]
If your workload never touches CUDA, deploy a [CPU node](/concepts/cpu-nodes) instead, from $0.09/hr. Click **Deploy CPU** in the sidebar.
:::
#### Select your GPU
For a first deployment, use:
* **GPU:** RTX 4090 (24 GB VRAM)
* **Cost:** \~$0.52/hour
* **Good for:** Learning, testing, small models
Click on the RTX 4090 to proceed.
#### Configure instance
1. **Region:** Choose the region closest to you for lower latency
2. **Operating System:** Select **Ubuntu 22.04 LTS** for the most stable GPU driver support
3. **Storage:** Keep the default (usually sufficient)
4. **SSH Key:** Select the key you uploaded earlier
5. **Startup Script (optional):** Leave blank for now. See [Startup Scripts](/connecting) for advanced automation.
#### Review and deploy
1. Check the **Order Summary** on the right:
* Hourly cost
* Current balance
* Instance configuration
2. Click **Deploy Instance**
3. Wait 30-60 seconds for provisioning
### Step 5: Connect to your instance
#### Get connection details
Once deployed, the instance dashboard shows:
* IP address
* Username (usually `root`, `ubuntu`, or provider-specific)
* SSH connection command
#### Connect via SSH
```bash
ssh root@
```
If using a custom SSH key location:
```bash
ssh -i ~/.ssh/id_ed25519 root@
```
On first connection, type `yes` to accept the host fingerprint. Enter your SSH key passphrase if you set one.
### Step 6: Verify your setup
Once connected, verify everything is working.
#### Check GPU
```bash
nvidia-smi
```
Expected output shows GPU model (RTX 4090), memory (24 GB), driver version, and GPU utilization.
#### Check CUDA
```bash
nvcc --version
```
The output shows the CUDA compiler version.
#### Check system
```bash
# Check CPU and memory
htop
# Check disk space
df -h
# Check OS version
cat /etc/os-release
```
#### Test GPU access
```bash
# Simple GPU test
python3 -c "import torch; print(f'CUDA available: {torch.cuda.is_available()}')"
```
PyTorch does not need to be pre-installed. Install it when needed for your workload.
### Troubleshooting
#### Issue: Cannot connect via SSH
**Symptoms**: Connection refused or timeout when running `ssh`
**Diagnosis**: Verify the SSH key is loaded:
```bash
ssh-add -l
```
**Resolution**: If the key is not listed, add it:
```bash
ssh-add ~/.ssh/id_ed25519
```
Additional checks:
* Verify you uploaded the correct public key
* Check that firewall rules allow SSH (port 22)
* Try with an explicit key path: `ssh -i ~/.ssh/id_ed25519 @`
#### Issue: GPU not detected
**Symptoms**: `nvidia-smi` returns an error
**Diagnosis**: Drivers may still be loading after provisioning
**Resolution**: Wait 30 seconds and run `nvidia-smi` again. If the error persists, reboot the instance with `sudo reboot`.
#### Issue: Instance deployment failed
**Symptoms**: Deployment status shows "failed"
**Resolution**:
* Check that your account balance has sufficient credits
* Try a different region (some may be at capacity)
* Contact support if the issue persists
### Stop or terminate your instance
When you are finished for now but will come back to the same environment, stop the instance:
1. Go to the instance dashboard
2. Click **Stop**
3. Review the quoted stopped rate and confirm
The GPU stops billing, the disk and everything on it is preserved, and starting it again returns the same public IP. Stopping is available on Spheron AI and Spheron ES. See [Instance lifecycle](/concepts/instance-lifecycle) for the full support matrix.
When you are finished entirely, terminate the instance:
1. Go to the instance dashboard
2. Click **Terminate** or **Delete**
3. The instance stops and all data is permanently deleted
:::warning
Back up important data before terminating. Terminated instances and their data cannot be recovered. A stopped instance is also destroyed if your team runs out of credit, so terminate anything you are genuinely done with.
:::
### What's next
* **[Quick Start](/quick-start)**: Condensed deployment flow for users already set up
* **[CPU Nodes](/concepts/cpu-nodes)**: Deploy CPU-only compute for non-GPU workloads
* **[Instance Lifecycle](/concepts/instance-lifecycle)**: Stop, start, and restart an instance
* **[SSH Connection Guide](/connecting/ssh-connection)**: Advanced SSH setup and troubleshooting
* **[Jupyter Notebook](/connecting/jupyter)**: Browser-based development via SSH tunnel
* **[VS Code Remote](/connecting/vscode-remote)**: Remote development directly on the instance
* **[Security Best Practices](/security)**: Keep your account secure
## Spheron overview
Spheron is an aggregated GPU cloud that pools capacity from multiple providers and exposes it through a single API and dashboard, at 60-80% lower cost than traditional cloud providers.
### What is Spheron?
Spheron is not a blockchain network. It is a GPU cloud platform that aggregates capacity from multiple providers across North America, Europe, and Asia Pacific and exposes it through a unified API and dashboard. You get a single interface across every provider without managing separate accounts, contracts, or billing relationships. Alongside GPUs, Spheron offers CPU-only nodes for workloads that need cores rather than accelerators.
### Key features
#### VM access
Get full root access to your instances from the moment they are deployed. You can install custom drivers, configure the operating system, and set up your software stack exactly the way you need it, with no container restrictions or sandboxed environments.
#### Bare metal performance
Bare metal instances give your workloads direct access to the physical hardware, with no hypervisor or virtualization layer in between. This means consistent, predictable performance and full utilization of GPU memory and compute resources for your training and inference jobs.
#### Multi-GPU hosts with high-speed interconnects
Deploy multi-GPU bare-metal instances with NVLink or NVSwitch between the GPUs on a host. SXM offers are purpose-built for large-scale distributed training workloads that require fast GPU-to-GPU communication and low-latency gradient synchronization.
#### Aggregated provider network
Access GPUs and CPU nodes from multiple providers including Verda, Sesterce, Spheron AI, Spheron ES, Spheron MS, and Massed Compute through a single dashboard and API. Switching between providers does not require separate accounts, contracts, or billing relationships.
#### Hardware variety
Choose from a wide range of GPU hardware to match your workload:
* **High-end:** B300 SXM6, B200 SXM6, and H100 SXM5 machines with NVLink and InfiniBand for large-scale training
* **Largest GPU memory:** AMD Instinct MI300X with 192 GB of HBM3e per GPU, running [ROCm](/connecting/rocm-amd)
* **Mid-tier:** A100 GPUs for production workloads
* **Cost-effective:** RTX 4090 and other PCIe GPUs for development and testing
Offers and instance cards carry an AMD, NVIDIA, or Intel mark, so the vendor is visible before you deploy.
#### Shared volumes and persistent storage
Create persistent storage volumes that exist independently from your instances. Attach a volume to a running instance, detach it without losing data, and reattach it to a different instance later. Volumes support multi-instance attachment for shared datasets and model checkpoints across your team.
#### CPU nodes for work that needs no GPU
Not every job needs an accelerator. **CPU Node** is a CPU-only instance for build steps, data preparation, schedulers, API workers, and control planes, priced from $0.09 per hour. It has its own page in the dashboard sidebar and its own wizard, with sizes from 4 vCPU with 4 GB of memory across Verda, Sesterce, Spheron AI, and Massed Compute. Spot pricing is available on Verda.
#### Reserved GPU nodes
Reserve dedicated GPU nodes for long-term commitments to get better rates and guaranteed availability. Reserved instances are suited for teams with predictable, sustained compute needs who want to lock in access and reduce per-hour costs compared to on-demand pricing.
#### Flexible billing and cost savings
Pay only for what you use with per-second billing and no minimum commitments. Spot instances offer the same GPU hardware at lower prices when you can tolerate occasional interruptions. Combined with 60-80% savings over traditional cloud providers, Spheron significantly reduces your total infrastructure spend.
#### Team coordination
Manage GPU access for your entire team from a shared account. Teams share credits, SSH keys, and API keys across members. Role-based access controls let you assign owner, admin, or member permissions so each person has the right level of access for their responsibilities.
### Cost savings
Spheron reduces GPU costs by 60-80% compared to traditional cloud providers:
* **RTX 4090:** \~$0.52/hr (check current prices in the dashboard)
* **Traditional clouds:** Typically charge 3-4x more for equivalent GPU resources
* **No hidden fees:** Zero ingress/egress charges, transparent billing
### Performance notes
* **Cluster (bare metal):** No hypervisor layer means direct NVLink access and no virtualization overhead for multi-GPU training
* **Dedicated/Spot (VM):** High-performance VMs with guaranteed GPU access; suitable for single-node training and inference
### Platform advantages
#### Reliability
Five providers across dozens of regions mean you can redeploy to a different provider if one has availability issues. No single datacenter dependency.
#### Scalability
Deploy a single GPU instance or a multi-node H100 cluster. Scale up or down between deployments; no reserved capacity required.
#### Security
Choose providers with specific compliance certifications for your workload: Verda (ISO 27001, GDPR), Sesterce (SOC 2 Type II, ISO 27001), and Massed Compute (HIPAA, SOC 2 Type II).
#### Stop instead of destroy
Park an instance you will come back to. Stopping releases the GPU and drops billing to the disk rate while the disk and everything on it stays in place; starting returns the same environment on the same public IP. Available on Spheron AI and Spheron ES. See [Instance lifecycle](/concepts/instance-lifecycle).
#### Deployment
* Dashboard and REST API for deployment
* Real-time metrics and monitoring
* Pay-per-second billing with no hidden fees
### How Spheron compares
| Feature | Spheron | Traditional Clouds | Other GPU Clouds |
| -------------- | --------------------------------------------- | ------------------ | ------------------------ |
| Root Access | ✅ Full by default | ⚠️ Limited | ⚠️ Container-only (some) |
| Architecture | ✅ Bare metal (Cluster) / VM (Dedicated, Spot) | ❌ Virtualized | ⚠️ Mixed |
| Provider Model | ✅ Aggregated | ❌ Single vendor | ❌ Single vendor |
| High-end GPUs | ✅ SXM + NVLink | ⚠️ Limited | ⚠️ Limited |
| Pricing | ✅ 60-80% cheaper | ❌ Premium | ⚠️ Moderate |
### Use cases
* **LLM training and fine-tuning:** Single-GPU to 8x H100 NVLink runs with PyTorch DDP or DeepSpeed
* **Production inference:** Dedicated instances that cannot be interrupted mid-request
* **Distributed training:** Multi-GPU bare-metal instances with NVLink or NVSwitch interconnects
* **Development and testing:** RTX 4090 Spot instances at \~$0.52/hr for prototyping and iteration
* **Research:** EU data-resident instances (Verda, Sesterce) for GDPR-compliant workloads
* **Support workloads:** CPU nodes from $0.09/hr for data prep, build steps, and schedulers that never touch a GPU
### Platform primitives
Understand how the platform works before deploying at larger scales:
* **[Instance Types](/concepts/instance-types)**: Spot, Dedicated, and Cluster trade-offs
* **[CPU Nodes](/concepts/cpu-nodes)**: CPU-only instances, sizes, regions, and pricing
* **[Instance Lifecycle](/concepts/instance-lifecycle)**: Stop, start, and restart a running instance
* **[Regions & Providers](/concepts/regions-providers)**: GPU availability by provider and region
* **[Networking](/concepts/networking)**: Port access, SSH tunneling, and public IPs
* **[Teams](/concepts/teams)**: Shared credits, SSH keys, and role-based access
### What's next
* **[Getting Started](/getting-started)**: Deploy your first instance in 5 minutes
* **[Quick Start](/quick-start)**: Launch pre-configured models
* **[Templates & Images](/templates)**: Copy-ready startup scripts for common stacks
* **[Cost Optimization](/cost-optimization)**: GPU tier selection and spend strategies
* **[Reserved GPUs](/reserved-gpus)**: Lock in long-term GPU access for better rates
* **[Billing](/billing)**: Understand pricing and payment options
## Provider integration guide
This guide describes the API contract a compute provider's orchestrator must expose for the Spheron AI Marketplace to list, provision, and manage GPU instances on the provider's infrastructure. It is written for the engineers who build and operate that orchestrator.
By the end of integration, the marketplace can pull your offer catalog, deploy an instance on your platform, give the end user working SSH access, and stop, start, or terminate that instance, all by calling your API.
The machine-readable companion is provider-orchestrator-openapi.yaml (OpenAPI 3.0.3). That file is the authoritative source for endpoint paths, payloads, and schemas. This page explains the intent and conventions behind it.
:::tip
Download the spec: provider-orchestrator-openapi.yaml (OpenAPI 3.0.3). Import it into Swagger UI, Postman, or your code generator to scaffold the server.
:::
### Integration model
The marketplace is the client. The provider's orchestrator is the server. The integration is entirely poll-based. No webhooks or callbacks are required.
After provisioning, the marketplace polls the instance-state endpoint every 10 to 30 seconds for each active instance and reacts to status transitions. Accurate, promptly updated status reporting is therefore the single most important property of the integration.
All requests and responses are JSON. The marketplace sends `Content-Type: application/json` on every request body and expects the same in responses.
### Capability tiers
Implement the Compute tier in full. Add the Storage tier only if your platform offers network volumes.
| Tier | Scope | Required? |
| ------- | ---------------------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------------------------------- |
| Compute | Offer catalog, real-time availability, instance create / get / list / start / stop / terminate | Required. A fully working compute tier is sufficient for a successful integration. |
| Storage | Volume locations, volume create / get / attach / detach / delete | Optional. Implement only if your platform supports network volumes. Its absence does not block integration. |
### Authentication
The preferred mechanism is a long-lived static API key sent on every request as `Authorization: Bearer `.
```bash
# Every request carries the static API key
curl -H "Authorization: Bearer " \
https://api.provider.example.com/v1/configurations
```
Keys must meet three requirements:
* Scoped to the marketplace account.
* Revocable.
* Concurrently valid in multiples, so keys rotate with zero downtime.
If your platform requires short-lived tokens instead, expose `POST /auth/token` and include `expires_in` in the response so the marketplace can refresh proactively.
### Offer catalog and availability
Two endpoints serve different purposes, and both are required.
#### Catalog: GET /configurations
This endpoint is the catalog. It must return every offer the provider knows about, both deployable and out-of-stock, with an `available` boolean set per offer.
Out-of-stock offers must be returned with `available: false`, never dropped from the array. The marketplace renders unavailable offers as out-of-stock cards with a notify-me flow. An offer that was never emitted simply vanishes from the marketplace UI.
The example below shows one deployable offer and one out-of-stock offer in the same response:
```json
{
"configurations": [
{
"id": "gpu-8x-h100-sxm",
"name": "8x H100 SXM",
"instance_type": "DEDICATED",
"vcpus": 192,
"memory_gb": 2048,
"storage_gb": 8000,
"gpu_count": 8,
"gpu_type": "H100-SXM5-80GB",
"gpu_memory_gb": 80,
"price_per_hour": 21.52,
"available": true,
"regions": ["EU-North 1", "US-Central 1"],
"os_options": ["ubuntu-22.04-cuda-12.4", "ubuntu-24.04"],
"supports_cloud_init": true
},
{
"id": "gpu-1x-rtx4090",
"name": "1x RTX 4090",
"instance_type": "SPOT",
"vcpus": 16,
"memory_gb": 64,
"storage_gb": 500,
"gpu_count": 1,
"gpu_type": "RTX-4090-24GB",
"gpu_memory_gb": 24,
"price_per_hour": 0.72,
"spot_price_per_hour": 0.36,
"available": false,
"regions": ["EU-North 1"],
"os_options": ["ubuntu-22.04-cuda-12.4"],
"supports_cloud_init": true
}
]
}
```
#### Deploy-time gate: GET /availability
This endpoint is the deploy-time gate. It returns only offers deployable right now (`available: true`), optionally filtered by region, and the marketplace calls it immediately before provisioning. It should reflect real-time inventory as closely as possible.
```bash
# Check live inventory in a single region before deploying
curl -H "Authorization: Bearer " \
"https://api.provider.example.com/v1/availability?region=EU-North%201"
```
#### Offer fields
Each offer (`Configuration`) carries:
* A stable `id` and `name`.
* `instance_type`: one of `SPOT` or `DEDICATED`.
* Hardware shape: `vcpus`, `memory_gb`, `storage_gb`, `gpu_count`, `gpu_type`, `gpu_memory_gb`.
* Pricing: `price_per_hour` and optional `spot_price_per_hour`, both USD per hour.
* `regions`, `os_options`, and `supports_cloud_init`.
#### Region tokens
Regions are identified by stable, human-readable tokens (for example `"EU-North 1"`), used consistently across every endpoint: offer `regions`, the availability filter, instance `region`, and volume locations.
Translate internal datacenter codes to canonical tokens at the API boundary. Raw codes must never leak into responses. If the storage tier is implemented, each volume-location `id` must equal the matching offer region token.
### Instance lifecycle
#### State machine
Instances report one of eight canonical statuses. Map your internal platform states onto these:
```text
┌────────────► ERROR (terminal)
│
PROVISIONING ────► ONLINE ◄──────────────┐
│ │ │
│ ▼ stop │ start
│ STOPPING ─► STOPPED ┘
│ │
│ ▼ (reaped by platform)
│ OFFLINE (terminal)
▼ terminate
DESTROYING ─► DESTROYED (terminal)
```
The distinction between `STOPPED` and `OFFLINE` matters:
* `STOPPED`: the resource still exists, is still owned by the deployment, and can be resumed via `/start`.
* `OFFLINE`: the instance can no longer be resumed in place (for example, the platform reaped a shut-off VM) and the deployment is effectively over.
`ERROR` is reserved for non-recoverable failures and should include a human-readable `error` field.
#### Provisioning flow
A single deployment follows this sequence. Steps 1 and 2 are marketplace calls; the rest is what your orchestrator does and reports:
1. The marketplace calls `GET /availability` to confirm live capacity.
2. The marketplace calls `POST /instances` with the offer, region, and SSH keys.
3. Your orchestrator returns a `PROVISIONING` instance record immediately, without waiting for boot.
4. The marketplace polls `GET /instances/{id}` every 10 to 30 seconds.
5. Your orchestrator transitions the instance to `ONLINE` once it has a reachable public IP (or port-forwarded SSH endpoint) and the injected SSH keys work.
A create request looks like this:
```json
{
"configuration_id": "gpu-8x-h100-sxm",
"region": "EU-North 1",
"name": "spheron-d3f9a1",
"ssh_keys": [
"ssh-ed25519 AAAAC3NzaC1lZDI1NTE5AAAA... user@host"
],
"operating_system_image": "ubuntu-22.04-cuda-12.4",
"cloud_init": {
"package_update": true,
"packages": ["tmux", "htop"],
"runcmd": ["nvidia-smi"]
}
}
```
Return `201` with a `PROVISIONING` record as soon as the instance exists:
```json
{
"id": "inst-7f3a91c2",
"configuration_id": "gpu-8x-h100-sxm",
"region": "EU-North 1",
"status": "PROVISIONING",
"created_at": "2026-06-10T12:00:00Z",
"updated_at": "2026-06-10T12:00:00Z"
}
```
A later poll returns the live, reachable instance:
```json
{
"id": "inst-7f3a91c2",
"configuration_id": "gpu-8x-h100-sxm",
"region": "EU-North 1",
"status": "ONLINE",
"public_ip": "203.0.113.10",
"ssh_port": 22,
"ssh_username": "ubuntu",
"gpu_count": 8,
"gpu_type": "H100-SXM5-80GB",
"image": "ubuntu-22.04-cuda-12.4",
"price_per_hour": 21.52,
"created_at": "2026-06-10T12:00:00Z",
"updated_at": "2026-06-10T12:03:40Z"
}
```
Expected provisioning times:
* Virtual machines: reach `ONLINE` within 10 minutes, with a typical target under 5 minutes.
* Bare metal: longer windows are acceptable. Agree on an SLA during onboarding, provided status is reported accurately throughout.
#### SSH keys, images, and cloud-init
The create request carries raw OpenSSH public key material in `ssh_keys`. The orchestrator injects these so the end user can connect. If your platform requires registered key objects, create temporary keys internally and clean them up at termination.
`operating_system_image` selects one of the offer's `os_options`. When an offer reports `supports_cloud_init: true`, honor the structured `cloud_init` block (run commands, packages, file writes) on first boot.
If instance names must be unique on your platform, de-duplicate (for example, by suffixing) rather than failing the request.
#### Stop and start
`POST /instances/{id}/stop` pauses a running instance while preserving its disk. Compute billing should pause while stopped. Document any storage charges during onboarding.
`POST /instances/{id}/start` resumes the instance in place. If your platform cannot resume stopped instances, return `409` with a descriptive error rather than silently destroying state.
#### Termination
`DELETE /instances/{id}` destroys the instance and releases all associated resources, including temporary SSH keys or scripts created during provisioning.
Once destroyed, `GET /instances/{id}` should return `404`. The marketplace interprets `404` on a previously known instance as `DESTROYED`. Deletion must be idempotent: deleting an already-destroyed instance is success, not an error.
### Volumes (optional tier)
Implement these endpoints only if your platform supports network volumes:
* `GET /volumes/locations`: lists regions where volumes can be created, with ids equal to region tokens.
* `POST /volumes`: creates a volume, optionally attaching to instances at create time.
* `POST /volumes/{id}/attach` and `/detach`: manage attachments.
* `DELETE /volumes/{id}`: removes the volume.
Several conventions make volume integrations robust:
* Attach is idempotent. Attaching to an already-attached instance is success.
* If attachment requires a stop, attach, then start cycle on your platform, handle it internally and report the intermediate instance states accurately.
* If detachment is asynchronous, do not report the volume as detached until the attachment record is actually gone.
* If attachment records can linger, force-detach internally before delete instead of failing.
The create-instance request may carry `volume_ids` for inline attachment. Honor it if you support it; ignore it otherwise, and the marketplace falls back to post-create attach.
### Errors and operational conventions
Errors use a consistent envelope with meaningful HTTP status codes:
```json
{
"error": {
"code": "capacity_unavailable",
"message": "No capacity for gpu-8x-h100-sxm in EU-North 1.",
"details": {}
}
}
```
Map status codes as follows:
| Status | Meaning |
| ------ | ---------------------------------------------- |
| `400` | Invalid request |
| `401` | Bad credentials |
| `404` | Not found (terminal for instances) |
| `409` | Invalid state, or capacity loss at create time |
Preserve real HTTP status codes. Do not return `200` with an embedded error.
Operational expectations:
* The state endpoint is polled continuously, so keep it fast and cheap.
* Status transitions should be observable within seconds of occurring.
* Rate limits, if any, should comfortably accommodate one poll per active instance per 10 seconds, plus catalog refreshes.
* All prices are USD per hour. Memory and storage are in GB.
* Timestamps are RFC 3339 UTC.
### Integration checklist
A provider is ready for marketplace onboarding when:
1. All compute-tier endpoints in the OpenAPI spec are implemented and reachable over HTTPS.
2. `GET /configurations` returns the full catalog, including out-of-stock offers with `available: false`.
3. Region tokens are stable and consistent across all endpoints.
4. A test instance can be provisioned, reached over SSH with an injected key, stopped, started, and terminated, with every status transition visible via polling.
5. `GET /instances/{id}` returns `404` after termination.
6. VM provisioning reaches `ONLINE` within the agreed SLA.
7. API keys are issued, scoped to the marketplace account, and rotatable.
8. If applicable, volume endpoints pass the same lifecycle test, including idempotent attach and reliable detach.
### What we need from you to start
To begin integration, share the following with the Spheron team:
* Your orchestrator base URL for staging and production.
* API credentials for a test account.
* Your offer catalog with pricing and regions.
* Expected provisioning times per instance type.
* Any platform-specific constraints: naming rules, stop/start support, NAT or port-forwarding, and volume semantics.
The Spheron team validates the contract with you against the checklist above. For questions, contact [info@spheron.ai](mailto\:info@spheron.ai).
### What's next
* [API reference](/api-reference): the REST API the marketplace exposes to end users.
* [Regions and providers](/concepts/regions-providers): how regions and providers map across the platform.
* [Instance types](/concepts/instance-types): the commercial classes behind `instance_type`.
* [Networking](/concepts/networking): public IPs, ports, and connectivity for deployed instances.
## Quick Start
Fast GPU deployment for users with an account already configured. Deploy in under 3 minutes.
:::info
**First-time user?** This guide assumes you already have:
* An active account with credits
* An SSH key uploaded
* Basic familiarity with the platform
**New to Spheron?** Start with [Getting Started](/getting-started) for complete setup.
:::
### Recommended configurations
Choose a configuration based on your use case:
#### Development and testing
**GPU:** RTX 4090 (24 GB VRAM)
**Cost:** \~$0.52/hour
**Best for:** Prototyping, small models, testing
#### Production training
**GPU:** H100 SXM5 (80 GB VRAM)
**Cost:** Variable (check dashboard)
**Best for:** Large language models, production training
#### Research and fine-tuning
**GPU:** A100 (40 GB/80 GB VRAM)
**Cost:** Variable (check dashboard)
**Best for:** Model fine-tuning, research workloads
#### No GPU needed
**Compute:** [CPU Node](/concepts/cpu-nodes) (from 4 vCPU)
**Cost:** From $0.09/hour
**Best for:** Data prep, build steps, schedulers, API workers
### Deploy in 3 steps
:::steps
#### 1. Select GPU
Go to [app.spheron.ai](https://app.spheron.ai) and click **Deploy GPUs** in the sidebar.
Choose from recommended configurations or browse the catalog:
* **RTX 4090** for development and testing
* **A100** for production training
* **H100** for large-scale LLM work
Filters persist in the URL, so a refresh keeps your view and the link opens the same catalog for a teammate.
For a workload that never touches CUDA, click **Deploy CPU** instead. That page skips the catalog entirely and goes straight to configuration.
#### 2. Configure
* **Region:** Closest to your location
* **OS:** Ubuntu 22.04 LTS
* **SSH Key:** Select from your uploaded keys
* Review pricing in the order summary
#### 3. Launch
Click **Deploy Instance** and wait about 30 seconds. Copy the SSH command from the instance details panel in the dashboard. The username and port vary by provider.
```bash
# Spheron AI provider - username is ubuntu
ssh ubuntu@
```
:::
### Verify and test
#### Check GPU
```bash
nvidia-smi # Shows GPU model, memory, driver
```
#### Quick tests
```bash
# Test CUDA
nvcc --version
# Test PyTorch (if installed)
python3 -c "import torch; print(torch.cuda.is_available())"
# Monitor GPU
nvidia-smi -l 1
```
#### Install ML stack
```bash
# Install common libraries
pip install torch torchvision transformers accelerate bitsandbytes
# Or use conda
conda install pytorch torchvision torchaudio pytorch-cuda=12.1 -c pytorch -c nvidia
```
### Advanced options
#### Startup scripts
Automate setup with cloud-init scripts. Add during deployment to:
* Install dependencies on first boot
* Configure environment variables
* Clone repositories
* Set up monitoring
See [Startup Script examples](/connecting) for templates.
#### Managing costs
Stop the instance when you will return to it:
* Go to the instance dashboard and click **Stop**
* The GPU stops billing; the disk and its contents are preserved
* Start it again on the same disk and the same public IP
* Available on Spheron AI and Spheron ES
Terminate the instance when you are done for good:
* Go to the instance dashboard and click **Terminate**
* Stops all charges immediately
* All data is permanently deleted
:::tip
Use [Reserved GPUs](/reserved-gpus) for long-term work to save 30-50% on costs.
:::
### Troubleshooting
**SSH connection issues:**
* Verify the correct SSH key is uploaded: check [User Settings](https://app.spheron.ai/settings)
* Try with an explicit key path: `ssh -i ~/.ssh/id_ed25519 @`
* See [SSH Guide](/connecting/ssh-connection) for detailed help
**GPU not showing:**
* Wait 30 seconds after deployment (drivers may still be loading)
* Run `nvidia-smi` to verify
* Reboot if needed: `sudo reboot`
**Deployment failed:**
* Check that account balance has sufficient credits
* Try a different region (some may be at capacity)
* Contact support via the chat widget on [app.spheron.ai](https://app.spheron.ai)
### What's next
#### Deploy AI models
* [Deploy LLMs](/quick-guides): Run Qwen, Chandra OCR, and more
* [AI Nodes](/quick-guides): Gonka AI, Pluralis
#### Advanced setup
* [Jupyter Notebook](/connecting/jupyter): Browser-based development
* [VS Code Remote](/connecting/vscode-remote): Remote development environment
* [Startup Scripts](/connecting): Automate configuration
* [Templates & Images](/templates): Copy-ready startup scripts for common stacks
#### Platform features
* [CPU Nodes](/concepts/cpu-nodes): CPU-only instances from $0.09/hr
* [Instance Lifecycle](/concepts/instance-lifecycle): Stop, start, and restart an instance
* [API Reference](/api-reference): Automate deployments with the API
* [Reserved GPUs](/reserved-gpus): Save 30-50% with reservations
* [Security guide](/security): Best practices
## Reserved GPUs
Request bulk GPU allocations, specific locations, or preferential pricing for long-term commitments.
### What are reserved GPUs
Reserved GPUs are for requests requiring:
* **Bulk quantities**: Multiple GPUs (8, 16, 32, 64+)
* **Specific locations**: Regional compliance or data proximity requirements
* **Long-term commitments**: Multi-month reservations with preferential pricing
* **Custom configurations**: Specialized hardware or network requirements
### How it works
1. **Submit request**: Fill out the reservation form with your requirements
2. **Team review**: Spheron team reviews your request within 24 hours
3. **Receive quotes**: Multiple providers compete to offer the best pricing
4. **Choose option**: Select the quote that fits your needs
5. **[Book meeting](https://meetings-eu1.hubspot.com/prashant-maurya)** (optional): Schedule a consultation for complex requirements
Competitive bidding across providers ensures optimal pricing.
### Benefits
**Cost savings:**
* 30-50% lower than on-demand hourly rates
* Bulk discounts for multiple GPUs
* Long-term commitment pricing advantages
**Guaranteed availability:**
* Reserved capacity ensures GPU access
* No competition with the spot market
* Predictable resource allocation
**Provider competition:**
* Multiple quotes from different providers
* Compare pricing and terms
* Choose the best value for your requirements
### Submitting a request
Visit [app.spheron.ai](https://app.spheron.ai/) > **Reserved GPU** to access the request form.
:::steps
#### Fill out request form
##### GPU model
Select GPU type: H100, H200, A100, B200, RTX 4090, RTX 5090, L40S, A40, L4, V100
* **H100/H200:** Highest performance, large-scale training
* **A100/B200:** Production-grade training and inference
* **RTX 4090/5090:** Development and medium workloads
* **L40S/A40:** Balanced price-performance
* **L4/V100:** Cost-effective for inference
Unsure? [Book a consultation](https://meetings-eu1.hubspot.com/prashant-maurya) with the team.
##### Quantity
Enter the number of GPUs needed. Reserved requests start at **32 GPUs (4 nodes of 8)**. Reservations are for bulk capacity; for anything smaller, deploy from the on-demand [GPU catalog](https://app.spheron.ai) instead.
##### Duration
Specify the reservation length:
* Enter a value (e.g., 6)
* Select a unit (Months or Years)
* Choose a start time (ASAP or Within 12 Months)
Longer commitments typically receive better pricing.
##### Location
Select a region: North America, Europe, Asia Pacific, South America, Middle East, Africa, or Any Location
* **Any Location:** Maximum provider competition, best pricing
* **Specific region:** Required for data compliance or proximity
##### Start date
Calendar selection for specific deployment timing (optional)
##### Additional requirements
Specify custom needs (optional):
* Network requirements (e.g., InfiniBand, NVLink)
* Compliance needs (e.g., GDPR, HIPAA)
* Storage requirements
* Special configurations
#### Contact information
Provide your contact details so the team can deliver quotes:
* **Name**: your full name
* **Email**: where quotes and follow-ups are sent
* **Phone** (required): include country code (e.g. `+1 555-123-4567`). Phone is validated and mandatory; the form will not advance to the review step without a valid number.
#### Review and submit
Review all details before submission. Edit any field if needed.
Click **Submit Request** to send to the team.
#### Receive quotes
Within 24 hours:
* Multiple provider quotes via email
* Pricing, hardware specs, and availability
* Terms and conditions
No obligation to accept. Compare and choose the best option.
:::
### Support and consultation
For complex requirements, [schedule a 30-minute consultation](https://meetings-eu1.hubspot.com/prashant-maurya) with the Spheron team to discuss GPU selection, quantity, and received quotes. For general questions, submit a request via the platform; responses are typically within 24 hours.
### Common use cases
**LLM training**: Large language models requiring days or weeks of GPU time
**Research projects**: Academic and lab projects needing predictable long-term costs
**Production inference**: AI services requiring guaranteed GPU availability
**Data processing**: Video processing, simulations, large-scale data analysis
**Multi-GPU workloads**: Distributed training requiring 8+ GPUs with high-speed interconnects
### Best practices
**Optimize costs:**
* Request the exact quantity needed, at or above the 32 GPU minimum (submit additional requests later if needed)
* Choose "Any Location" for competitive bidding unless a specific region is required
* Longer commitments (6-12+ months) typically offer better per-month pricing
* Select the appropriate GPU tier (L40S vs H100) based on actual workload needs
**Improve quote quality:**
* Provide detailed requirements in additional notes
* Specify network, storage, and compliance needs upfront
* Include realistic timelines
* Book a consultation for complex configurations
### Frequently asked questions
**Q:** Can I modify my request after submission?
**A:** Contact the team with your updated requirements. The team sends a revised quote.
**Q:** What if I need additional GPUs later?
**A:** Submit a new request. Multiple concurrent reservations are supported.
**Q:** Am I obligated to accept a quote?
**A:** No. Quotes are non-binding offers. Choose only if the terms meet your needs.
**Q:** What are the cancellation policies?
**A:** Policies vary by provider. Review the specific terms included with each quote.
**Q:** What if my preferred GPU is unavailable?
**A:** Providers suggest equivalent alternatives. The large provider network ensures options are available.
**Q:** How much cheaper are reserved vs on-demand?
**A:** Typically 30-50% savings depending on duration, quantity, and GPU type.
**Q:** Can I get a quote without committing?
**A:** Yes. Request quotes with no commitment. Consultation is also free.
### What's next
* [Getting Started](/getting-started): Deploy on-demand instances
* [Quick Start](/quick-start): Fast deployment guide
* [Cost Optimization](/cost-optimization): GPU tier selection and spend strategies
* [Billing](/billing): Credit management and pricing
* [General Info](/general-info): Support and official channels
## Security best practices
This page covers essential security guidelines for protecting your Spheron account, API credentials, and GPU instances. Apply these practices before deploying in any production environment.
:::warning
Never share credentials, API keys, or SSH private keys with anyone. Spheron will never ask for this information.
:::
### Account security
**Credentials protection:**
* Use strong, unique passwords
* Never share passwords, API keys, SSH keys, or payment info
* Verify URLs before entering credentials (official: spheron.network)
**Phishing protection:**
* Watch for fake support messages and impersonation attempts
* Use only official channels (see [General Info](/general-info))
* Verify domains before clicking links
### SSH keys
SSH keys are required for instance access. Only upload public keys to Spheron.
**Best practices:**
* Generate keys using ED25519 or RSA 4096-bit
* Use passphrases on private keys; never share them
* Store private keys in a secure location, not in repositories
* Rotate keys every 90 days
* Use different keys for different services
See [SSH Connection Guide](/connecting/ssh-connection) for setup.
### API keys
API keys provide programmatic access to your account. See [API Reference](/api-reference) for endpoint details.
**Best practices:**
* Store API keys in environment variables; never hardcode them
* Rotate every 90 days
* Revoke immediately if compromised
* Use separate keys per environment
* Never commit API keys to version control
```bash
export SPHERON_API_KEY="" # Store in environment, not in code
```
### Monitoring and alerts
Monitor regularly to detect unauthorized access:
* Active instances and deployments
* Billing and credit usage
* API activity logs
To set up alerts:
* Enable billing notifications in [User Settings](/user-settings)
* Set spending limits
* Track unusual activity patterns
See [Billing](/billing) for monitoring details.
### Instance security
**Network:**
* Close unnecessary ports
* Configure firewall rules
* Disable password authentication; use SSH keys only
* Use VPN or SSH tunneling for sensitive services
**System:**
* Keep software updated
* Apply security patches promptly
* Monitor system logs regularly
* Back up important data before terminating an instance
**Startup scripts:**
* Review scripts before deployment (they run with root privileges)
* Never hardcode credentials in scripts
* Use secrets management for sensitive data
* Test scripts in a development environment first
See [Connecting to instances](/connecting) for startup script examples.
### Official channels and support
For a complete list of official Spheron channels and contact information, see [General Information](/general-info).
Always verify you are on the correct official domain before:
* Entering login credentials
* Connecting your wallet to any website
* Sharing sensitive information
* Clicking links in messages or emails
Bookmark official URLs and double-check domains to avoid phishing attempts.
### Reporting security issues
If you suspect unauthorized access or find a vulnerability, take these steps immediately:
1. Change your account password
2. Revoke compromised API keys and SSH keys
3. Terminate any suspicious instances
4. Review billing for unauthorized usage
Then report the issue:
* Contact through official channels (see [General Info](/general-info))
* Provide timestamps, affected resources, and observed behavior
* Report phishing attempts to help the community
### Security checklist
**Account:**
* [ ] Strong unique password set
* [ ] Regular activity reviews scheduled
**Keys:**
* [ ] Only SSH public keys uploaded
* [ ] Passphrases set on private keys
* [ ] 90-day key rotation scheduled
* [ ] API keys stored in environment variables
**Instances:**
* [ ] Firewall configured
* [ ] Software kept up to date
* [ ] Unnecessary ports closed
* [ ] Instances terminated when not in use
### What's next
* [Getting Started](/getting-started): Account setup
* [SSH Connection Guide](/connecting/ssh-connection): SSH configuration
* [API Reference](/api-reference): API key management
* [User Settings](/user-settings): Account settings
* [General Info](/general-info): Official channels
## Templates and images
Copy-ready cloud-init startup scripts organized by use case. Paste the script into the **Startup Script** field when deploying an instance.
For a full introduction to startup scripts, see the [Startup Script guide](/connecting).
### Available templates
| Template | Minimum GPU | Stack |
| -------------------------------------------------- | ----------- | -------------------------------- |
| [PyTorch + CUDA 12.1](#pytorch--cuda-121) | RTX 4090 | Python 3.11, PyTorch 2.x |
| [TensorFlow 2.x](#tensorflow-2x) | RTX 4090 | Python 3.11, TF 2.x, CUDA |
| [JupyterLab ML Stack](#jupyterlab-ml-stack) | RTX 4090 | PyTorch + TF + JupyterLab |
| [Docker + NVIDIA Runtime](#docker--nvidia-runtime) | Any | Docker, NVIDIA Container Toolkit |
| [Prometheus + Grafana](#prometheus--grafana) | Any | Docker Compose monitoring |
| [vLLM Inference Server](#vllm-inference-server) | H100 / A100 | vLLM, OpenAI-compatible API |
| [Ollama + Open WebUI](#ollama--open-webui) | RTX 4090 | Docker, Ollama, Open WebUI |
***
### PyTorch + CUDA 12.1
Installs Python 3.11, PyTorch 2.x with CUDA 12.1, and common ML libraries.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3.11 python3.11-venv
- python3.11 -m ensurepip --upgrade
- python3.11 -m pip install --upgrade pip
- python3.11 -m pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121
- python3.11 -m pip install transformers accelerate bitsandbytes datasets
```
**Verify after boot:**
```bash
python3.11 -c "import torch; print(torch.cuda.is_available(), torch.version.cuda)"
```
***
### TensorFlow 2.x
Installs Python 3.11, TensorFlow 2.x with CUDA support, and common data science libraries.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3.11
- python3.11 -m ensurepip --upgrade
- python3.11 -m pip install --upgrade pip
- python3.11 -m pip install tensorflow[and-cuda]
- python3.11 -m pip install numpy pandas scikit-learn matplotlib
```
**Verify after boot:**
```bash
python3.11 -c "import tensorflow as tf; print(tf.config.list_physical_devices('GPU'))"
```
***
### JupyterLab ML Stack
Full ML environment with PyTorch, TensorFlow, and JupyterLab. JupyterLab starts on port 8888.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3.11
- python3.11 -m ensurepip --upgrade
- python3.11 -m pip install --upgrade pip
- python3.11 -m pip install torch torchvision --index-url https://download.pytorch.org/whl/cu121
- python3.11 -m pip install tensorflow[and-cuda]
- python3.11 -m pip install jupyterlab transformers accelerate datasets matplotlib scikit-learn
- |
cat > /etc/systemd/system/jupyterlab.service << 'EOF'
[Unit]
Description=JupyterLab
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3.11 -m jupyterlab --ip=0.0.0.0 --port=8888 --no-browser --allow-root
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable jupyterlab
- systemctl start jupyterlab
```
:::warning
JupyterLab generates a random token on startup. Retrieve it from the service logs after boot:
```bash
journalctl -u jupyterlab --no-pager | grep "token="
```
Use SSH tunneling to access it securely: `ssh -L 8888:localhost:8888 @`, then open the URL with the token printed in the logs (e.g. `http://localhost:8888/lab?token=`). Do not open port 8888 publicly without token-based authentication.
Replace `` and `` with the values from the SSH command in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances).
:::
***
### Docker + NVIDIA Runtime
Installs Docker CE and the NVIDIA Container Toolkit so you can run GPU-accelerated containers.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y ca-certificates curl gnupg
- install -m 0755 -d /etc/apt/keyrings
- curl -fsSL https://download.docker.com/linux/ubuntu/gpg | gpg --dearmor -o /etc/apt/keyrings/docker.gpg
- chmod a+r /etc/apt/keyrings/docker.gpg
- echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://download.docker.com/linux/ubuntu $(. /etc/os-release && echo $VERSION_CODENAME) stable" > /etc/apt/sources.list.d/docker.list
- apt-get update -y
- apt-get install -y docker-ce docker-ce-cli containerd.io docker-compose-plugin
- curl -fsSL https://nvidia.github.io/libnvidia-container/gpgkey | gpg --dearmor -o /usr/share/keyrings/nvidia-container-toolkit-keyring.gpg
- curl -s -L https://nvidia.github.io/libnvidia-container/stable/deb/nvidia-container-toolkit.list | sed 's#deb https://#deb [signed-by=/usr/share/keyrings/nvidia-container-toolkit-keyring.gpg] https://#g' > /etc/apt/sources.list.d/nvidia-container-toolkit.list
- apt-get update -y
- apt-get install -y nvidia-container-toolkit
- nvidia-ctk runtime configure --runtime=docker
- systemctl restart docker
```
**Verify:**
```bash
docker run --rm --gpus all nvidia/cuda:12.1.0-base-ubuntu22.04 nvidia-smi
```
***
### Prometheus + Grafana
Sets up a Docker Compose monitoring stack with Prometheus and Grafana on port 3000.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y ca-certificates curl gnupg
- install -m 0755 -d /etc/apt/keyrings
- curl -fsSL https://download.docker.com/linux/ubuntu/gpg | gpg --dearmor -o /etc/apt/keyrings/docker.gpg
- chmod a+r /etc/apt/keyrings/docker.gpg
- echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://download.docker.com/linux/ubuntu $(. /etc/os-release && echo $VERSION_CODENAME) stable" > /etc/apt/sources.list.d/docker.list
- apt-get update -y
- apt-get install -y docker-ce docker-ce-cli containerd.io docker-compose-plugin
- |
ADMIN_PASS=$(openssl rand -hex 16)
mkdir -p /opt/monitoring
echo "Grafana admin password: $ADMIN_PASS" > /root/grafana-credentials.txt
chmod 600 /root/grafana-credentials.txt
echo "GF_SECURITY_ADMIN_PASSWORD=$ADMIN_PASS" > /opt/monitoring/grafana.env
chmod 600 /opt/monitoring/grafana.env
cat > /opt/monitoring/docker-compose.yml << 'EOF'
services:
prometheus:
image: prom/prometheus:latest
container_name: prometheus
volumes:
- ./prometheus.yml:/etc/prometheus/prometheus.yml
restart: unless-stopped
grafana:
image: grafana/grafana:latest
container_name: grafana
ports:
- "3000:3000"
env_file:
- ./grafana.env
restart: unless-stopped
node-exporter:
image: prom/node-exporter:latest
container_name: node-exporter
volumes:
- /proc:/host/proc:ro
- /sys:/host/sys:ro
- /:/rootfs:ro
command:
- '--path.procfs=/host/proc'
- '--path.rootfs=/rootfs'
- '--path.sysfs=/host/sys'
restart: unless-stopped
EOF
chmod 644 /opt/monitoring/docker-compose.yml
- |
cat > /opt/monitoring/prometheus.yml << 'EOF'
global:
scrape_interval: 15s
scrape_configs:
- job_name: 'node'
static_configs:
- targets: ['node-exporter:9100']
EOF
- docker compose -f /opt/monitoring/docker-compose.yml up -d
```
Access Grafana at `http://localhost:3000` via SSH tunnel. Log in as `admin` with the generated password stored in `/root/grafana-credentials.txt` on your instance:
```bash
cat /root/grafana-credentials.txt
```
***
### vLLM Inference Server
Installs vLLM and starts an OpenAI-compatible inference server on port 8000. See the [full vLLM guide](/quick-guides/llms/frameworks/vllm-server) for configuration details.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm.service << 'EOF'
[Unit]
Description=vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Llama-3-8B-Instruct \
--tensor-parallel-size 1 \
--port 8000 \
--gpu-memory-utilization 0.9
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm
- systemctl start vllm
```
***
### Ollama + Open WebUI
Installs Docker and starts Ollama with the Open WebUI browser interface on port 3000. See the [full Ollama guide](/quick-guides/llms/frameworks/ollama) for model usage.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y ca-certificates curl gnupg
- install -m 0755 -d /etc/apt/keyrings
- curl -fsSL https://download.docker.com/linux/ubuntu/gpg | gpg --dearmor -o /etc/apt/keyrings/docker.gpg
- chmod a+r /etc/apt/keyrings/docker.gpg
- echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://download.docker.com/linux/ubuntu $(. /etc/os-release && echo $VERSION_CODENAME) stable" > /etc/apt/sources.list.d/docker.list
- apt-get update -y
- apt-get install -y docker-ce docker-ce-cli containerd.io docker-compose-plugin
- curl -fsSL https://nvidia.github.io/libnvidia-container/gpgkey | gpg --dearmor -o /usr/share/keyrings/nvidia-container-toolkit-keyring.gpg
- curl -s -L https://nvidia.github.io/libnvidia-container/stable/deb/nvidia-container-toolkit.list | sed 's#deb https://#deb [signed-by=/usr/share/keyrings/nvidia-container-toolkit-keyring.gpg] https://#g' > /etc/apt/sources.list.d/nvidia-container-toolkit.list
- apt-get update -y
- apt-get install -y nvidia-container-toolkit
- nvidia-ctk runtime configure --runtime=docker
- systemctl restart docker
- mkdir -p /opt/ollama
- |
cat > /opt/ollama/docker-compose.yml << 'EOF'
services:
ollama:
image: ollama/ollama:latest
container_name: ollama
runtime: nvidia
environment:
- NVIDIA_VISIBLE_DEVICES=all
volumes:
- ollama_data:/root/.ollama
ports:
- "11434:11434"
restart: unless-stopped
open-webui:
image: ghcr.io/open-webui/open-webui:main
container_name: open-webui
ports:
- "3000:8080"
environment:
- OLLAMA_BASE_URL=http://ollama:11434
volumes:
- webui_data:/app/backend/data
depends_on:
- ollama
restart: unless-stopped
volumes:
ollama_data:
webui_data:
EOF
- docker compose -f /opt/ollama/docker-compose.yml up -d
```
### What's next
* [Startup Script guide](/connecting): Cloud-init syntax and best practices
* [vLLM guide](/quick-guides/llms/frameworks/vllm-server): Full vLLM configuration
* [Ollama guide](/quick-guides/llms/frameworks/ollama): Model management and memory guidelines
* [Networking](/concepts/networking): SSH tunneling and port exposure
## User settings
Manage your account profile, SSH keys, API access credentials, GPU availability alerts, and email preferences.
Access settings at [app.spheron.ai](https://app.spheron.ai/) > **Settings**. The page has five tabs: **Profile**, **SSH Keys**, **API Keys**, **Alerts**, and **Notifications**.
### Profile
Update account information and preferences.
**Available fields:**
* **Full Name**: Editable
* **Email Address**: Must be changed through your OAuth provider (GitHub/Google)
* **Company**: Optional organization name
Click **Save Changes** to apply updates.
### SSH keys
Manage SSH keys used to authenticate sessions on your GPU instances. Keys are scoped to the current team; switching teams shows a different key set. The header chip displays the total key count for the active team.
**Each key entry shows:**
* Key name
* Public key (with copy button)
* Date added
* Delete action
#### Adding SSH keys
1. Click **+ Add SSH Key**
2. Enter a key name
3. Paste public key content (from `~/.ssh/id_*.pub`)
4. Click **Save**
**Generate SSH keys:**
```bash
# Linux/Mac
ssh-keygen -t ed25519 -C "your_email@example.com"
cat ~/.ssh/id_ed25519.pub
# Windows PowerShell
ssh-keygen -t ed25519 -C "your_email@example.com"
type $env:USERPROFILE\.ssh\id_ed25519.pub
```
See [SSH Connection Guide](/connecting/ssh-connection) for detailed setup.
**Security:** Only upload public keys (`.pub` files). Never share private keys.
### API keys
Generate and manage API keys for programmatic access.
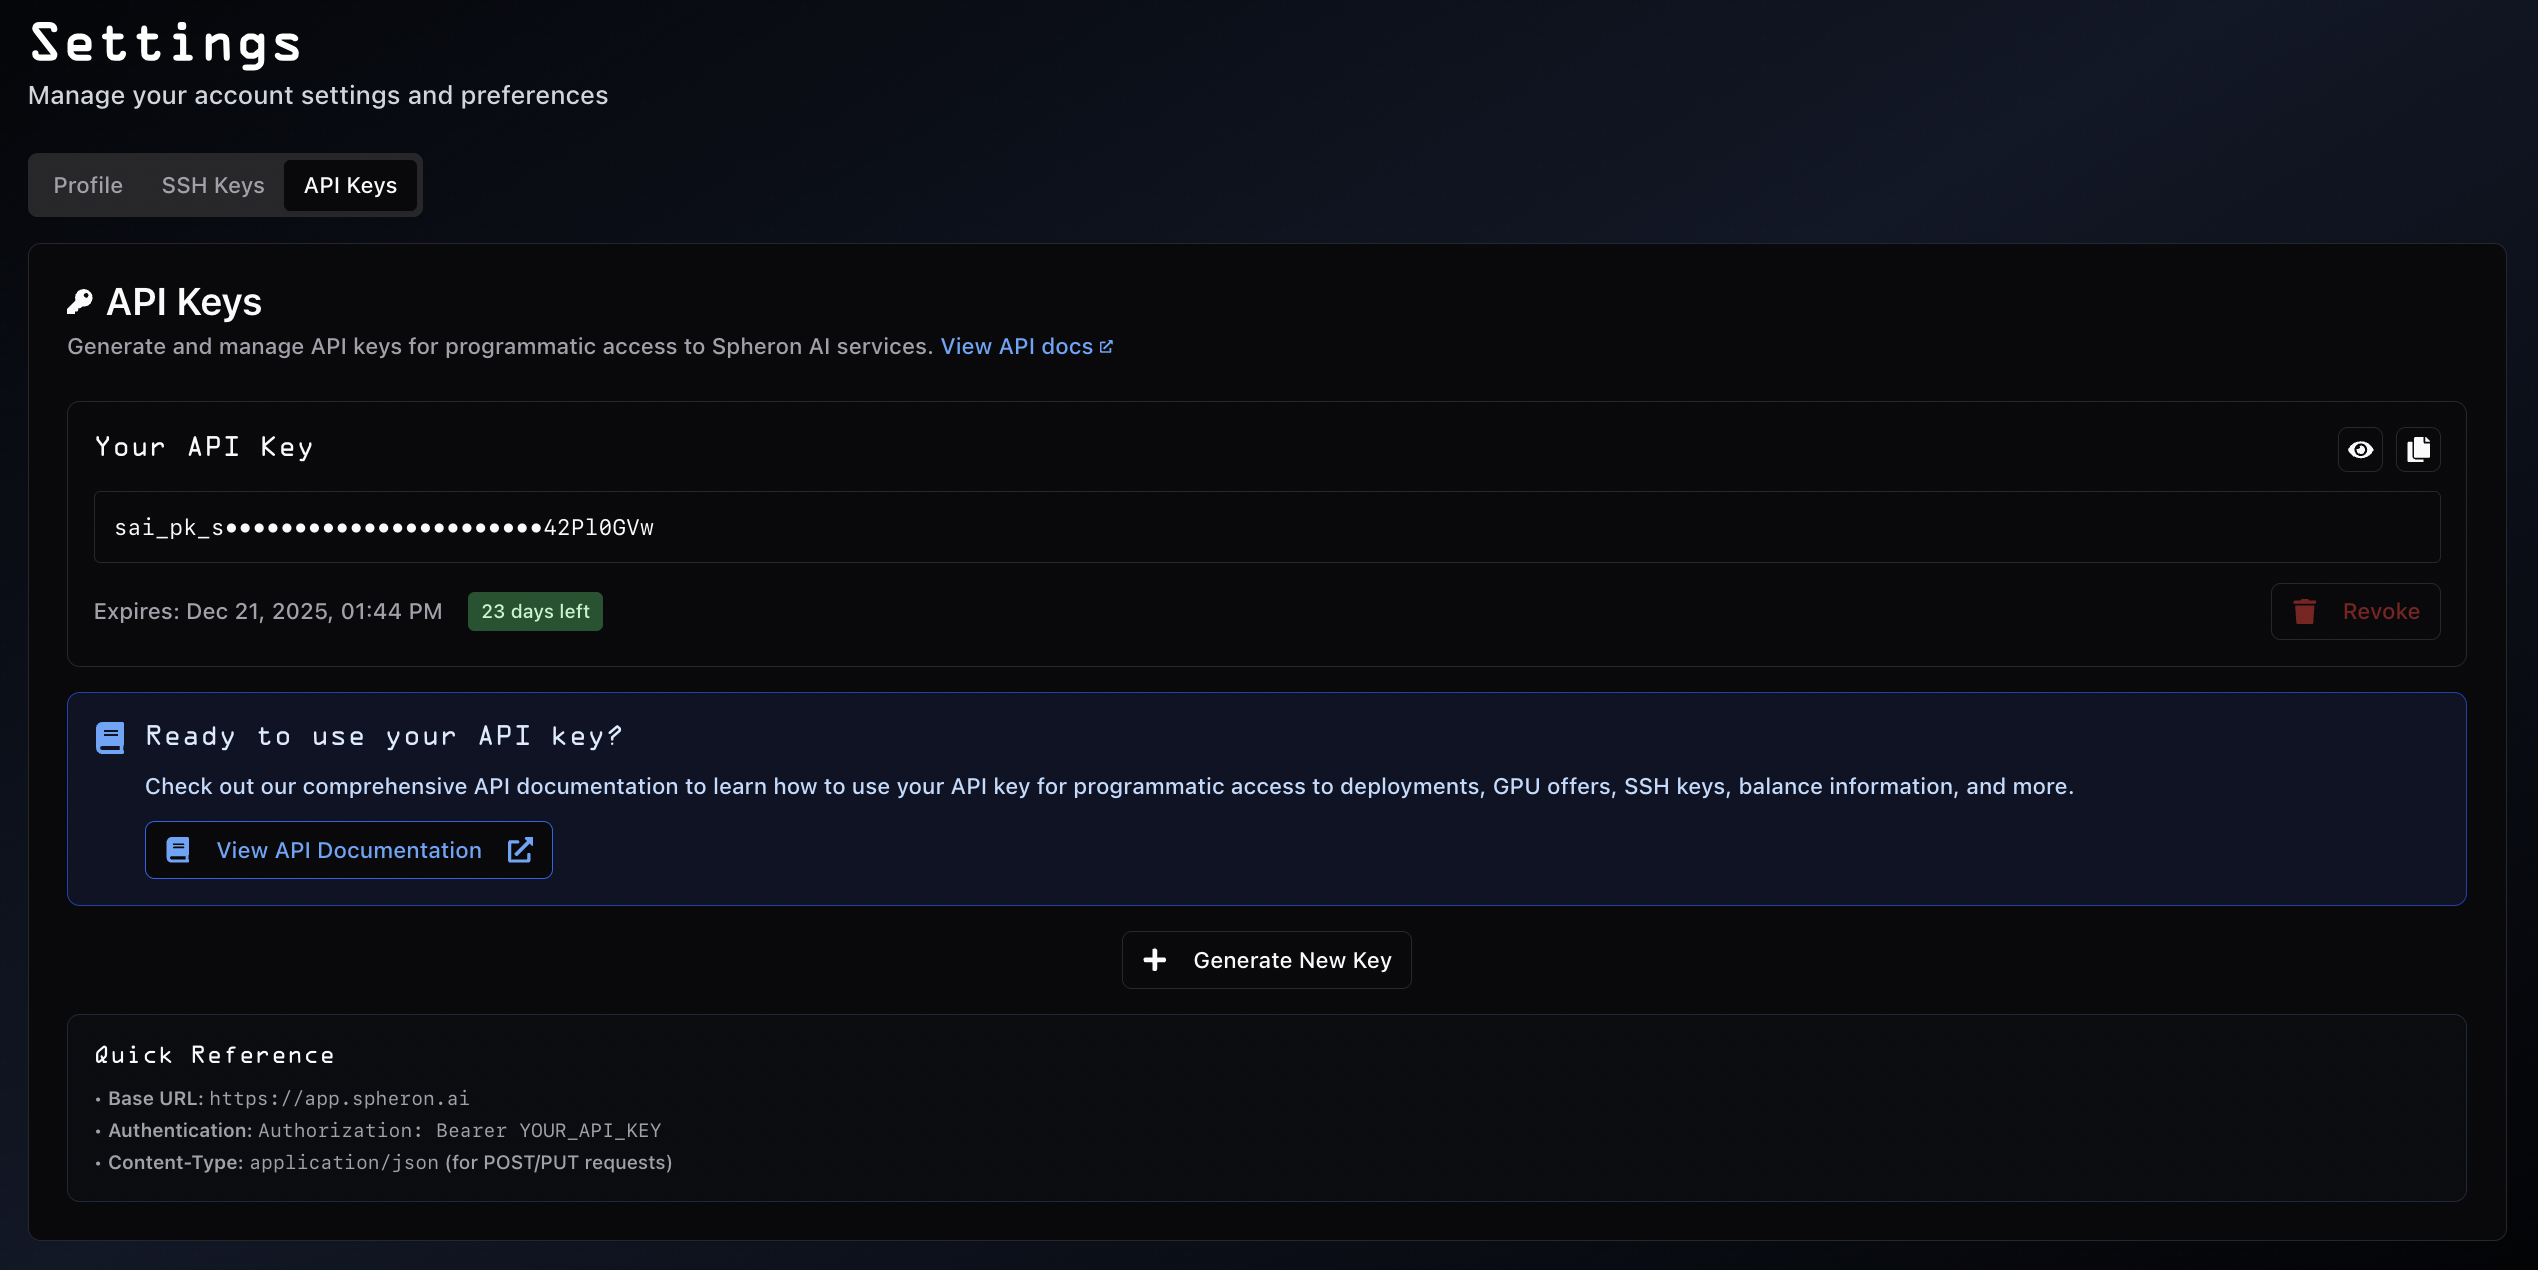
:::warning[Whitelist required before generating a key]
API key generation is gated by the Spheron team. New accounts see an **API Key Generation Locked** state until your account is approved.
To request access, email [info@spheron.ai](mailto\:info@spheron.ai) with the following details:
* Whether you are an individual or a company
* Your current location (country)
* Your estimated monthly compute budget in USD
* Your use case for the API key (training, inference, agents, automation, etc.)
The team reviews requests to ensure secure and appropriate platform usage. Once approved, the **Generate New Key** button unlocks on this page.
:::
#### Managing keys
Once whitelisted and a key is issued, the **Active Key** card shows:
* Masked key starting with `sai_` (with reveal-and-copy buttons)
* **Expires** date plus a days-left indicator (for example, `320 DAYS LEFT`)
* **Revoke** button to invalidate the key immediately
To rotate a key, revoke the existing one and then click **+ Generate New Key** to issue a replacement. Only one API key can be active at a time.
#### Quick reference
The API keys page also displays the values needed to authenticate API requests:
| Field | Value |
| ------------ | ------------------------------------ |
| Base URL | `https://app.spheron.ai` |
| Auth header | `Authorization: Bearer YOUR_API_KEY` |
| Content-Type | `application/json` |
#### API capabilities
With an API key, you can:
* Deploy and manage GPU instances
* Check GPU availability and pricing
* Manage SSH keys programmatically
* View account balance
* Monitor usage and billing
See the [API Reference](/api-reference) for complete endpoint documentation and usage examples.
### Alerts
The **Alerts** tab lists your GPU availability alerts. Subscribe to one when the hardware you want is out of stock, and Spheron emails you as soon as it returns.
#### Create an alert
1. Go to **Deploy GPUs** and find an offer card marked unavailable.
2. Click **Notify me** on that card.
3. Confirm the configuration: GPU type, GPU count, instance type (Spot, Dedicated, or any), and provider.
CPU Node offers support alerts the same way. An out-of-stock CPU size shows the same **Notify me** action in place of the configure flow.
#### Alert statuses
| Status | Meaning |
| --------- | --------------------------------------------------------- |
| Pending | Waiting for the configuration to come back in stock |
| Notified | The configuration became available and the email was sent |
| Cancelled | You unsubscribed from the alert |
Cancelled and notified alerts can be resubscribed from the same tab. Alerts are a dashboard feature and are not exposed on the API-key surface.
### Notifications
The **Notifications** tab controls which marketing emails you receive. You are subscribed by default.
Turn the toggle off and product and offer emails stop. Account and billing emails always reach you and are unaffected by this setting:
* Deployment succeeded and deployment failed notices
* Low-balance warnings and balance-exhaustion notices
* Payment receipts and auto top-up failures
Every marketing email carries a one-click unsubscribe link that opens this tab directly.
### Security best practices
**API keys:**
* Store in environment variables; never hardcode them
* Revoke immediately if compromised
* Rotate every 90 days
* Generate separate keys per environment
* Never commit to version control
**SSH keys:**
* Add keys only from controlled devices
* Remove keys from lost or compromised devices
* Use passphrases on private keys
* Delete unused keys regularly
**Monitoring:**
* Review active keys periodically
* Remove unrecognized keys immediately
* Check key expiration dates
See [Security best practices](/security) for comprehensive guidelines.
### Frequently asked questions
**Q:** Why can't I change my email?
**A:** Email is managed through your OAuth provider (GitHub/Google). Update it there first.
**Q:** How many SSH keys can I add?
**A:** There is no limit. Add keys for different devices or team members as needed.
**Q:** What happens when my API key expires?
**A:** Applications using that key fail. Generate a new key before expiration.
**Q:** Can I have multiple active API keys?
**A:** One active API key at a time. Generate a new key to replace the existing one.
**Q:** Where do I find my SSH public key?
**A:**
* Linux/Mac: `cat ~/.ssh/id_ed25519.pub`
* Windows: `type $env:USERPROFILE\.ssh\id_ed25519.pub`
**Q:** Can I turn off deployment and billing emails?
**A:** No. The Notifications toggle covers marketing email only. Deployment status, low-balance warnings, and payment receipts are always sent, because they affect running instances and your balance.
**Q:** How do I rotate API keys safely?
**A:** Generate a new key, update your applications, test them, then revoke the old key.
### What's next
* [SSH Connection Guide](/connecting/ssh-connection): Detailed SSH setup
* [API Reference](/api-reference): Complete API documentation
* [Billing](/billing): Credits, auto top-up, and low-balance warnings
* [Security best practices](/security): Comprehensive security guide
* [Getting Started](/getting-started): Account setup and first deployment
* [General Info](/general-info): Support and official channels
## Quick Guides
### Where to start
* **Training a model?** → Start with [Distributed Training](/quick-guides/training/distributed-training) for multi-GPU, or pick any RTX 4090 Spot instance for single-GPU fine-tuning
* **Running inference?** → [vLLM Server](/quick-guides/llms/frameworks/vllm-server) for an OpenAI-compatible API; [Ollama](/quick-guides/llms/frameworks/ollama) for interactive local usage
* **Generating images?** → [FLUX.1](/quick-guides/image-generation/flux-1) for state-of-the-art text-to-image; [ComfyUI](/quick-guides/image-generation/comfyui) for visual workflows
* **Running an AI node?** → See the [AI Nodes](#ai-nodes) section below
### Training
Model training guides, from single-GPU fine-tuning to large-scale distributed runs.
#### [Distributed Training (PyTorch DDP)](/quick-guides/training/distributed-training)
Multi-GPU PyTorch DDP and DeepSpeed ZeRO-3 on a bare-metal SXM instance (up to 8 GPUs with NVLink). Covers `torchrun`, gradient checkpointing, BF16 precision, checkpoint persistence, and GPU monitoring.
**Hardware:** Dedicated Bare Metal, SXM form factor (H100, H200, or B200; up to 8 GPUs)
### LLM inference
Deploy and serve large language models on Spheron GPU instances.
#### [Inference Frameworks](/quick-guides/llms/frameworks)
Choose the right serving stack for your use case.
#### [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server)
OpenAI-compatible inference server using vLLM on H100 or A100. Includes a systemd service for persistence, SSH tunnel access, and performance tuning flags.
**Hardware:** H100 80GB (7B–13B models) · 2× A100 80GB (30B+)
#### [Ollama + Open WebUI](/quick-guides/llms/frameworks/ollama)
Browser-based chat interface backed by Ollama on an RTX 4090. Docker Compose setup with GPU passthrough; pull any model with one command.
**Hardware:** RTX 4090 (24GB VRAM)
#### [DeepSeek R1 & V3](/quick-guides/llms/deepseek-r1)
DeepSeek reasoning models from 7B distillations to the full 671B FP8 multi-GPU deployment.
#### [Llama 4 Scout & Maverick](/quick-guides/llms/llama-4-scout)
Meta's latest multimodal MoE models with long-context and image understanding.
#### [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3)
Meta Llama 3 family guides covering 8B through 405B with tensor parallelism.
#### [Qwen3 Dense & MoE](/quick-guides/llms/qwen3)
Qwen3 text models with thinking mode, 8B through 235B MoE variants.
#### [Mistral & Mixtral](/quick-guides/llms/mistral-mixtral)
Mistral 7B, Mixtral 8x7B MoE, and Mistral Small 3.1 with function calling.
#### [Gemma 3](/quick-guides/llms/gemma-3)
Google DeepMind Gemma 3, 4B through 27B, available under the Gemma Terms of Use (commercial use permitted).
#### [Phi-4 & Phi-4 Multimodal](/quick-guides/llms/phi-4)
Microsoft Phi-4 SLMs including the multimodal variant with image input.
#### [Multimodal Models](/quick-guides/llms/multimodal)
Vision-language models including Qwen3-Omni, InternVL3, LLaVA-Next, Pixtral, and Baidu ERNIE.
#### [Chandra OCR](/quick-guides/llms/chandra-ocr)
Specialized OCR model for document processing and text extraction.
#### [Soulx Podcast-1.7B](/quick-guides/llms/soulx-podcast-1-7b)
Compact 1.7B parameter model optimized for podcast and audio content generation.
#### [Janus CoderV-8B](/quick-guides/llms/janus-coderv-8b)
Code generation and understanding model with 8B parameters.
### Image generation
Deploy GPU-accelerated image generation models on Spheron instances.
#### [FLUX.1 & FLUX.2](/quick-guides/image-generation/flux-1)
Black Forest Labs text-to-image models. FLUX.1-dev on RTX 4090 (24GB), FLUX.2 on H100 (80GB).
**Hardware:** RTX 4090 24GB (FLUX.1-dev) · H100 80GB (FLUX.2)
#### [Stable Diffusion 3.5 & SDXL](/quick-guides/image-generation/stable-diffusion-35)
Stability AI diffusion models. SD 1.5 on 8GB, SDXL on 16GB, SD 3.5 on 24–40GB VRAM.
**Hardware:** 8–40GB VRAM depending on model variant
#### [ComfyUI](/quick-guides/image-generation/comfyui)
Node-based visual workflow server for image generation. Docker-based, port 8188, SSH tunnel setup.
**Hardware:** RTX 4090 24GB (recommended)
### AI nodes
Deploy and run specialized AI network nodes.
#### [Gonka AI Node](/quick-guides/nodes/gonka-ai)
Deploy Gonka AI node infrastructure for AI compute network participation.
#### [Pluralis Node 0](/quick-guides/nodes/pluralis-node-0)
Set up and run Pluralis Node 0 for distributed AI network participation.
### What's next
* [Instance Types](/concepts/instance-types): Choose the right GPU for your workload
* [Cost Optimization](/cost-optimization): Reduce training and inference costs
* [Templates & Images](/templates): Copy-ready startup scripts
* [API Reference](/api-reference): Automate deployments programmatically
## Distributed Training (PyTorch DDP)
Run large-scale distributed training with PyTorch DDP or DeepSpeed on a multi-GPU bare-metal instance.
### Recommended hardware
#### Instance type overview
Spheron GPU offerings are classified by two criteria: **interruptibility** and **hardware isolation**.
All Spot instances are VM-based and can be reclaimed by the provider at any time. Use Spot only for fault-tolerant jobs with checkpointing. Dedicated instances carry a 99.95% SLA and are not reclaimed after deployment.
Within Dedicated, two hardware isolation options are available:
* **VM**: Runs in an isolated virtual machine on shared physical hardware. The default across most providers and GPU offers.
* **Bare Metal**: Full physical server with no hypervisor, no shared tenants. GPU count varies by offer and provider, from single-GPU up to multi-GPU servers. On the dashboard, identified by the `BAREMETAL` suffix in the GPU type name.
For multi-GPU distributed training, use a **Dedicated Bare Metal** offer with multiple GPUs on a single host. Bare metal removes the hypervisor layer and gives training processes direct access to every GPU and to the interconnect between them, which is what makes gradient synchronization efficient.
**Offer:** Look for the `BAREMETAL` suffix in the GPU type name and a GPU count of 4 or 8
#### GPU form factor and interconnect
Gradient synchronization speed depends on how the GPUs on the host talk to each other, which is determined by the GPU form factor in the offer you select:
| Form factor | Intra-node interconnect | Notes |
| ------------------------------------- | ----------------------- | ------------------------------------------------------------------------------ |
| SXM (B200 SXM6, H200 SXM5, H100 SXM5) | NVLink / NVSwitch | Highest GPU-to-GPU bandwidth; optimal for all-reduce-heavy DDP and ZeRO-3 runs |
| PCIe (H100 PCIE, A100 PCIE) | PCIe lanes | Lower cost; sufficient when gradient synchronization is not the bottleneck |
Choose an SXM offer for large model training where gradient synchronization dominates step time. PCIe offers are adequate for smaller models or when cost is the priority.
SXM multi-GPU offers are available on Spheron ES (B200 SXM6, H200 SXM5, H100 SXM5), Spheron AI (H200 SXM, H100 SXM5), and Verda (H100). See [Regions and Providers](/concepts/regions-providers) for current inventory per provider.
:::warning[Do not use Spot for training runs]
Spot instances are VM-based and can be reclaimed by the provider at any time. Do not use Spot for multi-day training runs or any job requiring uninterrupted access.
Dedicated instances carry a 99.95% SLA and are not subject to provider interruption. However, **persistent volumes for checkpoints are still strongly recommended** to protect work against hardware failure or accidental termination.
:::
### Deploy the instance
Deploy a multi-GPU bare-metal instance from the dashboard. On the **Deploy GPUs** page, select a Dedicated offer with the `BAREMETAL` suffix and the GPU count your run needs. Choose Ubuntu 22.04 as the operating system and attach your SSH key.
### Running distributed training with `torchrun`
Once SSH'd into the instance, launch your training script with `torchrun`:
```bash
torchrun \
--nproc_per_node=8 \
--nnodes=1 \
train.py \
--batch_size 32 \
--gradient_checkpointing
```
`--nproc_per_node=8` uses all 8 H100 GPUs. For a 4-GPU offer, use `--nproc_per_node=4`.
### PyTorch DDP training script
Minimal example of a DDP-compatible training loop:
```python
import argparse
import os
import torch
import torch.distributed as dist
from torch.nn.parallel import DistributedDataParallel as DDP
from torch.utils.data import DataLoader
from torch.utils.data.distributed import DistributedSampler
def setup():
dist.init_process_group(backend="nccl")
torch.cuda.set_device(int(os.environ["LOCAL_RANK"]))
def cleanup():
dist.destroy_process_group()
def train():
parser = argparse.ArgumentParser()
parser.add_argument("--batch_size", type=int, default=8)
parser.add_argument("--gradient_checkpointing", action="store_true")
args = parser.parse_args()
setup()
rank = dist.get_rank()
local_rank = int(os.environ["LOCAL_RANK"])
model = YourModel().to(local_rank)
model = DDP(model, device_ids=[local_rank])
# Enable gradient checkpointing to reduce VRAM usage
if args.gradient_checkpointing:
model.module.gradient_checkpointing_enable()
optimizer = torch.optim.AdamW(model.parameters(), lr=1e-4)
# DistributedSampler ensures each worker sees a disjoint shard of the data
dataset = YourDataset() # replace with your dataset
sampler = DistributedSampler(dataset)
dataloader = DataLoader(dataset, batch_size=args.batch_size, sampler=sampler)
num_epochs = 3
for epoch in range(num_epochs):
# Reshuffle the dataset differently for each epoch across all workers
sampler.set_epoch(epoch)
for step, batch in enumerate(dataloader):
with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
loss = model(**batch).loss
loss.backward()
optimizer.step()
optimizer.zero_grad()
# Save checkpoint every 100 steps
if step % 100 == 0 and rank == 0:
torch.save({
'step': step,
'epoch': epoch,
'model_state_dict': model.module.state_dict(),
'optimizer_state_dict': optimizer.state_dict(),
}, f'/checkpoints/checkpoint_epoch{epoch}_step{step}.pt')
cleanup()
if __name__ == '__main__':
train()
```
### DeepSpeed ZeRO-3 for models >30B
For models too large to fit in a single GPU's memory, use DeepSpeed ZeRO-3 to shard parameters, gradients, and optimizer states across all GPUs.
`ds_config.json`:
```json
{
"zero_optimization": {
"stage": 3,
"offload_optimizer": { "device": "cpu", "pin_memory": true },
"offload_param": { "device": "cpu", "pin_memory": true },
"overlap_comm": true,
"contiguous_gradients": true,
"reduce_bucket_size": 5e8,
"stage3_prefetch_bucket_size": 5e7,
"stage3_param_persistence_threshold": 1e6
},
"bf16": { "enabled": true },
"activation_checkpointing": {
"partition_activations": true,
"cpu_checkpointing": true
},
"train_micro_batch_size_per_gpu": 1,
"gradient_accumulation_steps": 8
}
```
Launch with DeepSpeed:
```bash
deepspeed --num_gpus=8 train.py \
--deepspeed ds_config.json \
--model_name_or_path meta-llama/Meta-Llama-3.1-70B
```
### Mixed precision (BF16)
H100, H200, and B200 GPUs have native BF16 support. Always use BF16 for training on these GPUs; it is faster and more numerically stable than FP16:
```python
with torch.autocast(device_type="cuda", dtype=torch.bfloat16):
outputs = model(**batch)
```
### Checkpoint persistence
Mount a persistent volume at `/checkpoints` before your training run to protect checkpoints across deployments:
1. Create a volume: see [Volume Mounting](/connecting/volume-mounting)
2. Mount it at `/checkpoints` in your cloud-init script
3. Save checkpoints to `/checkpoints/` in your training loop (example above)
### Dataset storage
For large datasets, stage the data on the instance's local NVMe disk rather than reading it from a network volume during training. Local disks deliver much higher I/O bandwidth than NFS or virtiofs volumes. Keep the authoritative copy on a persistent volume and copy the working set to local disk at the start of the run.
### GPU monitoring
Watch per-GPU utilization during training:
```bash
nvidia-smi dmon -s u
```
Check NVLink health and bandwidth (SXM offers only):
```bash
nvidia-smi nvlink --status
nvidia-smi nvlink --capabilities
```
Monitor GPU memory:
```bash
nvidia-smi --query-gpu=memory.used,memory.free --format=csv -l 1
```
### What's next
* [Volume Mounting](/connecting/volume-mounting): Persistent checkpoint storage
* [Instance Types](/concepts/instance-types): Spot vs Dedicated, and hardware isolation categories (VM, Bare Metal)
* [Regions and Providers](/concepts/regions-providers): Multi-GPU inventory by provider
* [Cost Optimization](/cost-optimization): Reserved GPU pricing for long-term training
## Training Guides
Guides for running model training workloads on Spheron GPU instances, from single-GPU fine-tuning to large-scale distributed training on bare-metal H100 clusters.
### Choosing the right instance for training
| Workload | Recommended Type | Why |
| ------------------------------- | ------------------------------------ | ------------------------------------------------- |
| Experiments, prototyping | Spot | 30–60% cheaper; interrupt-safe with checkpointing |
| Single-GPU fine-tuning | Dedicated (RTX 4090 / A100) | No interruption risk for multi-hour runs |
| Multi-GPU distributed training | Dedicated Bare Metal (multi-GPU SXM) | NVLink interconnect, full physical server access |
| Production training runs (days) | Dedicated | Guaranteed availability |
Use [Spot instances](/concepts/instance-types#spot) for experiments; they save significant cost. Enable checkpoint saving to a [persistent volume](/connecting/volume-mounting) so work survives if the instance is reclaimed.
### Available guides
#### [Distributed Training (PyTorch DDP)](/quick-guides/training/distributed-training)
Multi-GPU PyTorch DDP and DeepSpeed ZeRO-3 training on a bare-metal SXM instance (up to 8 GPUs with NVLink). Covers `torchrun` invocation, gradient checkpointing, BF16 mixed precision, checkpoint persistence, and GPU monitoring.
**Best for:** Large language model pre-training and fine-tuning; multi-day training runs on multi-GPU NVLink hosts.
### What's next
* [Instance Types](/concepts/instance-types): Spot vs Dedicated, and hardware isolation categories
* [Volume Mounting](/connecting/volume-mounting): Persistent checkpoint storage
* [Cost Optimization](/cost-optimization): Reducing training costs with Spot and Reserved GPUs
import { YouTube } from '../../../components/YouTube'
## Gonka AI Node
Deploy a Gonka AI node on a Spheron GPU instance. Gonka is a decentralized AI compute network that uses Proof of Work 2.0, directing GPU compute toward real AI training and inference workloads. Operators earn rewards for providing verifiable compute.
### Overview
Gonka transforms GPU compute into useful AI work through Proof of Work 2.0, where computational power advances real AI models instead of solving arbitrary puzzles. Operators earn rewards for delivering verifiable compute.
**Key features:**
* Real AI workloads (not wasteful mining)
* Honest-majority validation
* Reputation-based trust system
* Open, censorship-free LLM inference and training
### Hardware requirements
**Minimum per MLNode:**
* VRAM: 40GB+ usable
* GPUs: 2-5 Network Nodes recommended
**Large models** (DeepSeek R1, Qwen3-235B):
* 2+ MLNodes, each with 8x H200 GPUs
* 640GB+ VRAM per MLNode
**Medium models** (Qwen3-32B, Gemma-3-27B):
* 2+ MLNodes, each with 4x A100 or 2x H100
* 80GB+ VRAM per MLNode
**Network Node server:**
* CPU: 16-core
* RAM: 64GB+
* Storage: 1TB NVMe SSD
* Network: Stable high-speed connection
**MLNode server:**
* RAM: 1.5x GPU VRAM
* CPU: 16-core
* NVIDIA Container Toolkit with CUDA 12.6-12.9
### Key management overview
Gonka uses a three-key system:
* **Account Key (Cold):** Created locally, high-privilege, store offline
* **Consensus Key (TMKMS):** Managed by secure service for block validation
* **ML Operational Key (Warm):** Created on server for automated transactions
Read the [Gonka Key Management Guide](https://github.com/gonka-ai/gonka) before production deployment.
### Prerequisites
* Spheron AI account ([sign up](https://app.spheron.ai))
* Payment method configured
* SSH key (see [SSH connection guide](/connecting/ssh-connection))
* Local secure machine for Account Key generation
* HuggingFace account and token
### Part A: Local machine setup
#### Step 1: Install CLI tool
Download the `inferenced` binary from [Gonka releases](https://github.com/gonka-ai/gonka/releases):
```bash
chmod +x inferenced
./inferenced --help
```
On macOS, allow execution in System Settings → Privacy & Security if prompted.
#### Step 2: Create Account Key
:::warning[Run on local machine only]
Run this step on your secure local machine, not on the server.
:::
```bash
./inferenced keys add gonka-account-key --keyring-backend file
```
Save the mnemonic phrase securely offline. This is your only recovery method.
### Part B: Deploy GPU on Spheron
#### Step 3: Sign up and add credits
1. Go to [app.spheron.ai](https://app.spheron.ai) and sign up.
2. Click **Credits** → Add funds (card or stables).
#### Step 4: Deploy instance
1. Click **Deploy** in the sidebar.
2. Select GPU: **A100 (80GB) or H100** (40GB+ VRAM required).
3. Region: Closest to you.
4. OS: **Ubuntu 22.04 LTS + CUDA 12.8**.
5. Select your SSH key.
6. Click **Deploy Instance**.
### Part C: Server setup
#### Step 5: Connect to instance
```bash
ssh root@
```
#### Step 6: Install dependencies
```bash
sudo apt update && apt upgrade -y
sudo apt install git docker.io docker-compose -y
```
#### Step 7: Install NVIDIA container toolkit
```bash
sudo apt install nvidia-container-toolkit -y
sudo nvidia-ctk runtime configure --runtime=docker
systemctl restart docker
```
Verify GPU access:
```bash
docker run --rm --gpus all nvidia/cuda:12.2.0-base-ubuntu22.04 nvidia-smi
```
#### Step 8: Clone Gonka repository
```bash
git clone https://github.com/gonka-ai/gonka.git -b main
cp /root/gonka/deploy/join/config.env.template /root/gonka/deploy/join/config.env
cd /root/gonka/deploy/join
```
#### Step 9: Configure environment
```bash
# Create HuggingFace cache directory
mkdir -p /mnt/shared
```
Edit `config.env`:
```bash
nano config.env
```
Required fields:
* Key name
* Public URL of your node
* Account public key
* SSH ports
Load the configuration:
```bash
source config.env
```
Configure `node-config.json`:
* Define MLNodes and inference ports
* Specify models to load
* Set concurrent request limits
#### Step 10: Download model weights
```bash
# Setup HuggingFace cache
mkdir -p $HF_HOME
sudo apt update && apt install -y python3-pip pipx
pipx install huggingface_hub[cli]
pipx ensurepath
export PATH="$HOME/.local/bin:$PATH"
# Download model
hf download Qwen/Qwen2.5-7B-Instruct
```
#### Step 11: Pull containers
```bash
# Pull all images
docker compose -f docker-compose.yml -f docker-compose.mlnode.yml pull
# Start chain components
source config.env && docker compose up tmkms node -d --no-deps
# Check logs
docker compose logs tmkms node -f
```
#### Step 12: Create ML operational key
Enter the API container:
```bash
docker compose run --rm --no-deps -it api /bin/sh
```
Create the warm key:
```bash
printf '%s\n%s\n' "$KEYRING_PASSWORD" "$KEYRING_PASSWORD" | inferenced keys add "$KEY_NAME" --keyring-backend file
```
Save the mnemonic, then exit the container:
```bash
exit
```
#### Step 13: Register host
Re-enter the API container:
```bash
docker compose run --rm --no-deps -it api /bin/sh
```
Register the participant:
```bash
inferenced register-new-participant \
$DAPI_API__PUBLIC_URL \
$ACCOUNT_PUBKEY \
--node-address $DAPI_CHAIN_NODE__SEED_API_URL
```
Exit:
```bash
exit
```
#### Step 14: Grant permissions (switch to local machine)
:::warning[Run on local machine only]
Run this step on your local machine where you created the Account Key.
:::
```bash
./inferenced tx inference grant-ml-ops-permissions \
gonka-account-key \
\
--from gonka-account-key \
--keyring-backend file \
--gas 2000000 \
--node /chain-rpc/
```
This grants the ML Operational Key permission to submit inference proofs.
#### Step 15: Launch node (switch back to server)
```bash
source config.env && \
docker compose -f docker-compose.yml -f docker-compose.mlnode.yml up -d
```
All services start: chain node, API node, MLNodes.
### Verification
#### Check participant registration
```
http://node2.gonka.ai:8000/v1/participants/
```
The response displays your public key in JSON.
#### Check current epoch
After Proof of Compute completes (every 24 hours):
```
http://node2.gonka.ai:8000/v1/epochs/current/participants
```
#### Monitor dashboard
```
http://node2.gonka.ai:8000/dashboard/gonka/validator
```
Track the next Proof of Compute session timing.
#### Check node status
Using public IP:
```bash
curl http://:/status
```
Using private (on server):
```bash
curl http://0.0.0.0:26657/status
```
Using genesis node:
```bash
curl http://node2.gonka.ai:26657/status
```
### Proof of Compute
**Simulation:** Test PoC on MLNode before the actual PoC phase begins.
**Timing:**
* Runs every 24 hours
* Check the dashboard for the next session
* Stop the server between sessions and restart before PoC
### Troubleshooting
#### Issue: Container won't start
**Symptoms:** Container exits immediately or fails to start.
**Diagnosis:**
```bash
docker ps -a
docker compose logs
```
**Resolution:** Verify configuration and reload:
```bash
source config.env
env | grep DAPI
```
#### Issue: GPU not accessible
**Symptoms:** NVIDIA toolkit not found or GPU not visible in container.
**Resolution:**
```bash
nvidia-ctk --version
sudo nvidia-ctk runtime configure --runtime=docker
systemctl restart docker
```
#### Issue: Permission grant failed
**Symptoms:** Transaction rejected or timeout.
**Resolution:**
* Verify the Account Key is correct.
* Check network connectivity to the seed node.
* Ensure sufficient gas.
* Verify the ML Operational Key address.
#### Issue: PoC failures
**Symptoms:** Proof of Compute does not complete.
**Resolution:**
* Verify all MLNodes have sufficient VRAM.
* Confirm model weights downloaded correctly.
* Review MLNode logs: `docker compose logs mlnode`
### Managing your node
**Update profile:** Update host name, website, and avatar on the dashboard to help the network identify your node.
**Monitor performance:**
* Check PoC completion status.
* View earned rewards.
* Monitor GPU usage: `nvidia-smi -l 1`
**Stop node:**
```bash
docker compose down
```
**Restart node:**
```bash
source config.env && \
docker compose -f docker-compose.yml -f docker-compose.mlnode.yml up -d
```
### What's next
* [Gonka GitHub](https://github.com/gonka-ai/gonka)
* [Gonka Dashboard](http://node2.gonka.ai:8000/dashboard)
* [Getting Started](/getting-started): Spheron deployment basics
* [SSH Connection](/connecting/ssh-connection): SSH setup guide
## AI Node Guides
Guides for deploying and running AI network nodes on Spheron GPU instances. Participate in decentralized AI compute networks and distributed model training protocols.
### Choosing the right instance for AI nodes
| Node Type | Recommended Type | Why |
| -------------- | --------------------------- | ---------------------------------------------- |
| Gonka AI Node | Dedicated (A100 / H100) | Sustained uptime for Proof of Work 2.0 tasks |
| Pluralis Node0 | Dedicated (RTX 4090 / A100) | 16GB+ VRAM required for collaborative training |
Use Dedicated instances for node operations to ensure consistent availability. Spot instances may be interrupted, which can affect node participation and rewards.
### Available guides
#### [Gonka AI Node](/quick-guides/nodes/gonka-ai)
Decentralized AI network using Proof of Work 2.0 for meaningful compute contribution to AI training and inference. Docker-based deployment on A100 or H100 instances.
**Best for:** Contributing GPU compute to the Gonka decentralized AI network.
#### [Pluralis Node 0](/quick-guides/nodes/pluralis-node-0)
Collaborative multi-participant model training via Protocol Learning. Node0-7.5B enables permissionless participation in distributed AI model pretraining with 16GB+ VRAM.
**Best for:** Participating in collaborative distributed AI model training.
### What's next
* [Instance Types](/concepts/instance-types): Spot vs Dedicated vs Cluster
* [Networking](/concepts/networking): SSH tunneling and port access
* [Getting Started](/getting-started): Deploy your first Spheron instance
import { YouTube } from '../../../components/YouTube'
## Pluralis Node0-7.5B
Deploy a Pluralis Node0-7.5B on a Spheron GPU instance. Pluralis Protocol Learning allows multiple participants to collaboratively train large-scale foundation models without central ownership. Node0-7.5B enables permissionless participation in distributed AI model pretraining with 16GB+ VRAM.
### Overview
Models remain unextractable and become collectively owned protocol assets under the Pluralis Protocol Learning framework.
**Node0-7.5B:** Permissionless, model-parallel pretraining framework for GPUs with 16GB+ VRAM.
### Requirements
**Hardware:**
* GPU: 16GB+ VRAM
* RAM: 16GB+ recommended
* Storage: 50GB free
* Network: Stable connection
**Recommended GPUs:**
* RTX 4090, A100, H100
**Software:**
* Ubuntu 22.04 or 24.04
* Python 3.11
* Miniconda
* Git
### Prerequisites
* Spheron account ([sign up](https://app.spheron.ai))
* Payment method configured
* SSH key (see [SSH connection guide](/connecting/ssh-connection))
* HuggingFace account and token ([get token](https://huggingface.co/settings/tokens))
### Step 1: Deploy GPU on Spheron
1. **Sign up** at [app.spheron.ai](https://app.spheron.ai).
2. **Add credits:** Click Credits → Add funds (card/stables).
3. **Deploy:**
* Click **Deploy** in the sidebar.
* Select GPU: **RTX 4090, A100, or H100** (16GB+ VRAM).
* Region: Closest to you.
* OS: **Ubuntu 22.04 or 24.04 LTS**.
* Select your SSH key.
* Click **Deploy Instance**.
### Step 2: Connect to instance
```bash
ssh root@
```
### Step 3: Install dependencies
```bash
# Install PyTorch (CPU version for setup)
pip3 install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cpu
# Install Git
sudo apt install -y git
```
### Step 4: Clone repository
```bash
git clone https://github.com/PluralisResearch/node0
cd node0
```
### Step 5: Install Miniconda
```bash
# Download installer
wget https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh -O ~/miniconda.sh
# Install
bash ~/miniconda.sh -b -p ~/miniconda3
# Initialize
~/miniconda3/bin/conda init bash
# Clean up
rm ~/miniconda.sh
# Verify
source ~/miniconda3/etc/profile.d/conda.sh && conda --version
```
### Step 6: Create Conda environment
```bash
# Create environment
conda create -n node0 python=3.11 -y
# Activate
conda activate node0
# Install Node0
pip install .
```
### Step 7: Configure Node0
```bash
# Generate configuration
python3 generate_script.py --host_port 49200 --announce_port 22
```
When prompted, enter your HuggingFace token:
1. Visit [huggingface.co/settings/tokens](https://huggingface.co/settings/tokens).
2. Create a new token with "Read" permissions.
3. Copy and paste when prompted.
### Step 8: Start Node0 server
```bash
./start_server.sh
```
The server starts and begins listening on the configured ports.
### Verification
Check server status:
```bash
# Monitor logs
tail -f logs/node0.log
# Verify process running
ps aux | grep node0
```
Confirm participation:
* Check the Pluralis dashboard for your node.
* Verify network connectivity.
* Monitor contribution metrics.
### Troubleshooting
#### Issue: Installation fails
**Symptoms:** pip or conda errors during setup.
**Resolution:**
```bash
# Verify Python version
python --version
# Check conda environment
conda env list
```
#### Issue: HuggingFace token error
**Symptoms:** Authentication failure when generating configuration.
**Resolution:**
* Verify the token has "Read" permissions.
* Regenerate the token if expired.
* Check that the token was copied without extra spaces.
#### Issue: Server won't start
**Symptoms:** `start_server.sh` exits with an error.
**Resolution:**
```bash
# Check ports available
lsof -i :49200
lsof -i :22
# View error logs
cat logs/node0.log
```
#### Issue: Connection issues
**Symptoms:** Node cannot reach the Pluralis network.
**Resolution:**
* Verify the firewall allows ports 49200 and 22.
* Check GPU is accessible: `nvidia-smi`
* Ensure sufficient VRAM is available.
### What's next
* [Pluralis Research GitHub](https://github.com/PluralisResearch/node0)
* [Getting Started](/getting-started): Spheron deployment basics
* [SSH Connection](/connecting/ssh-connection): SSH setup guide
* [General Info](/general-info): Support channels
import { YouTube } from '../../../components/YouTube'
## Chandra OCR
Deploy [Chandra OCR](https://huggingface.co/datalab-to/chandra) on a Spheron GPU instance. Chandra OCR converts images and PDFs into structured Markdown, HTML, or JSON while preserving document layout, hierarchy, and visual elements. It achieves 83.1% accuracy on the olmOCR benchmark, outperforming GPT-4o, Mistral OCR, and DeepSeek OCR.
### Key capabilities
* Multi-format output (Markdown, HTML, JSON)
* Handwriting recognition
* Form reconstruction (including checkboxes)
* Complex layouts (tables, math equations)
* Visual element extraction (images, diagrams, captions)
* 40+ languages
Chandra OCR supports two inference modes:
* **Local:** HuggingFace transformers for privacy-sensitive and edge deployments
* **Remote:** vLLM server for scalable production and high-throughput pipelines
Benchmark accuracy on olmOCR (83.1% overall):
| Category | Accuracy |
| --------------- | -------- |
| Headers/Footers | 90.8% |
| Long Tiny Text | 92.3% |
| Tables | 88.0% |
| ArXiv | 82.2% |
Accuracy vs. competitors: +13.2 pp vs. GPT-4o, +19.3 pp vs. Gemini Flash 2, +4 pp vs. dots.ocr
### Deployment tiers
| Tier | GPU | Performance | Use Case |
| -------------------- | ------------------------------- | ------------- | -------------------------- |
| **Dev/Test** | CPU | 0.1-0.3 img/s | PoC, batch processing |
| **Cost-Optimized** | RTX 3060/4060 Ti (4-bit) | 0.4-0.8 img/s | Moderate volumes |
| **High-Performance** | RTX 3090/4090, L40S (BF16/FP16) | 1.5-3.0 img/s | High daily volumes |
| **Enterprise** | A100/H100 (FlashAttention2) | 3.0-5.0 img/s | Mission-critical pipelines |
| **Distributed** | 2x A100/H100 (tensor-parallel) | 5.0-8.0 img/s | Real-time OCR services |
The model weights are available on [HuggingFace](https://huggingface.co/datalab-to/chandra).
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Provision a Spheron instance
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. Click **Deploy** → Select GPU (see Deployment Tiers above) → Region → **Ubuntu 22.04** → add your SSH key → **Deploy**
See [Getting Started](/getting-started) or [SSH Connection](/connecting/ssh-connection) for details.
#### Step 2: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `root` or `ubuntu`) and `` with your instance's public IP.
#### Step 3: Update system packages
```bash
sudo apt update && sudo apt install -y software-properties-common curl ca-certificates
```
#### Step 4: Add Python PPA repository
```bash
sudo add-apt-repository -y ppa:deadsnakes/ppa
sudo apt update
```
#### Step 5: Install Python 3.11
```bash
sudo apt-get -o Acquire::Retries=3 install -y python3.11 python3.11-venv python3.11-dev
```
#### Step 6: Set up pip
```bash
python3.11 -m ensurepip --upgrade
python3.11 -m pip install --upgrade pip setuptools wheel
```
#### Step 7: Create virtual environment
```bash
python3.11 -m venv ~/.venvs/py311
source ~/.venvs/py311/bin/activate
```
#### Step 8: Install PyTorch (CUDA 12.1)
```bash
pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
```
#### Step 9: Install Chandra OCR dependencies
```bash
pip install chandra-ocr vllm transformers accelerate pillow bitsandbytes
```
### Usage
#### Launch web interface
```bash
chandra_app
```
Access at: **[http://localhost:8501](http://localhost:8501)**
**Features:**
* Upload PDFs or images
* Visualize OCR results
* Export as Markdown, HTML, or JSON
### Programmatic usage
```python
from chandra_ocr import ChandraOCR
# Initialize the model
ocr = ChandraOCR()
# Process a document
result = ocr.process("path/to/document.pdf", output_format="markdown")
# Print the result
print(result)
```
#### Batch processing
```python
import os
from chandra_ocr import ChandraOCR
ocr = ChandraOCR()
input_dir = "path/to/documents"
output_dir = "path/to/output"
for filename in os.listdir(input_dir):
if filename.endswith((".pdf", ".png", ".jpg")):
input_path = os.path.join(input_dir, filename)
result = ocr.process(input_path, output_format="markdown")
output_path = os.path.join(output_dir, f"{filename}.md")
with open(output_path, "w") as f:
f.write(result)
```
### Advanced configuration
#### vLLM server (high throughput)
```bash
# Install vLLM if not already installed
pip install vllm
# Start the vLLM server
python -m vllm.entrypoints.openai.api_server \
--model datalab-to/chandra \
--dtype bfloat16 \
--max-model-len 4096
```
#### Custom parameters
```python
from chandra_ocr import ChandraOCR
ocr = ChandraOCR(
max_tokens=2048,
temperature=0.7,
batch_size=4,
use_flash_attention=True
)
```
### Performance optimization
#### Memory
* Use 4-bit or 8-bit quantization to reduce VRAM requirements.
* Reduce batch size when you encounter out-of-memory errors.
* Enable gradient checkpointing for large documents.
#### Speed
* Enable FlashAttention2 on A100 and H100 GPUs.
* Use vLLM for concurrent multi-request processing.
* Use distributed inference for high-volume workloads.
#### Accuracy
* Use BF16 or FP16 precision for full-precision output.
* Process images at 2560 px or higher resolution.
* Apply multi-pass processing for critical documents.
### Troubleshooting
#### OOM errors
```bash
# Solution 1: Reduce batch size
ocr = ChandraOCR(batch_size=1)
# Solution 2: Use quantization
pip install bitsandbytes
ocr = ChandraOCR(quantization="4bit")
# Solution 3: Lower resolution
ocr.process("document.pdf", max_resolution=1920)
```
#### Slow processing
```bash
# Ensure CUDA is properly configured
python -c "import torch; print(torch.cuda.is_available())"
# Check GPU utilization
nvidia-smi
# Enable vLLM for better throughput
# See Advanced Configuration section above
```
#### Installation issues
```bash
# If pip install fails, try:
pip install --no-cache-dir chandra-ocr
# Or install dependencies separately:
pip install torch torchvision --index-url https://download.pytorch.org/whl/cu121
pip install transformers accelerate
pip install chandra-ocr
```
### Supported formats
**Input formats:** PNG, JPEG, JPG, TIFF, BMP, WebP, PDF, scanned documents, screenshots
**Specialized document types:** Academic papers, forms, tables, equations, diagrams, handwritten notes
**Output formats:**
* **Markdown:** Preserves structure, hierarchy, and formatting
* **HTML:** Browser-ready output with semantic markup
* **JSON:** Includes text, layout, bounding boxes, confidence scores, and metadata
### Best practices
#### Document quality
* Use good lighting and scan at 300 DPI or higher.
* Avoid skewed or rotated pages and remove background noise before processing.
#### Deployment
* Start with the Balanced tier and scale up as volume increases.
* Monitor GPU usage and adjust batch sizes to stay within VRAM limits.
* Add error handling and retry logic to your pipeline.
#### Production
* Use async processing for web applications.
* Use a queue system for high-volume workloads.
* Cache results for frequently processed documents.
* Add logging and monitoring to track throughput and errors.
### Use cases
* **Enterprise:** Legacy archives, invoice automation, contract analysis, compliance reporting
* **Academic:** Research papers, databases, publications, historical documents
* **Legal and financial:** Contracts, statements, filings, due diligence review
* **Healthcare:** Medical records, prescriptions, forms, clinical trial documents
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the environment setup. After the instance is ready, SSH in and run `. /opt/chandra-ocr/bin/activate && chandra_app` to launch the web interface.
```yaml
#cloud-config
runcmd:
- apt update && apt install -y software-properties-common curl ca-certificates
- add-apt-repository -y ppa:deadsnakes/ppa
- apt update
- apt-get -o Acquire::Retries=3 install -y python3.11 python3.11-venv python3.11-dev
- python3.11 -m ensurepip --upgrade
- python3.11 -m pip install --upgrade pip setuptools wheel
- python3.11 -m venv /opt/chandra-ocr
- /opt/chandra-ocr/bin/pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
- /opt/chandra-ocr/bin/pip install chandra-ocr vllm transformers accelerate pillow bitsandbytes
```
After cloud-init completes, activate the environment and start the web interface:
```bash
. /opt/chandra-ocr/bin/activate
chandra_app
```
### What's next
* [Specialized Models](/quick-guides/llms/specialized-models): Compare Chandra OCR with SoulX Podcast and Janus CoderV
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Configure vLLM for high-throughput OCR pipelines
* [Instance Types](/concepts/instance-types): Select the right GPU tier for your document volume
* [Getting Started](/getting-started): Create a Spheron account and deploy your first instance
## DeepSeek R1 & V3
Deploy [DeepSeek R1](https://huggingface.co/deepseek-ai/DeepSeek-R1) and [DeepSeek V3](https://huggingface.co/deepseek-ai/DeepSeek-V3) reasoning models on Spheron GPU instances using vLLM. DeepSeek R1 features chain-of-thought reasoning exposed via `` blocks; distilled variants (7B–32B) run on single GPUs.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| ---------------- | ------------------ | ----------------- | -------------------------- |
| R1-Distill-7B | RTX 4090 (24GB) | Dedicated or Spot | Single-GPU, fast iteration |
| R1-Distill-14B | A100 40GB | Dedicated | Full precision |
| R1-Distill-32B | A100 80GB (INT4) | Dedicated | AWQ quantization |
| DeepSeek-V3 671B | 8× H100 80GB (FP8) | Cluster | `--tensor-parallel-size 8` |
| DeepSeek-R1 671B | 8× H100 80GB (FP8) | Cluster | `--tensor-parallel-size 8` |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model deepseek-ai/DeepSeek-R1-Distill-Qwen-7B \
--port 8000 \
--dtype bfloat16
```
Press `Ctrl+C` to stop.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-deepseek.service > /dev/null << 'EOF'
[Unit]
Description=DeepSeek R1 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model deepseek-ai/DeepSeek-R1-Distill-Qwen-7B \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-deepseek
sudo systemctl start vllm-deepseek
```
For the full DeepSeek-R1 671B model on 8× H100, replace the `ExecStart` command with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model deepseek-ai/DeepSeek-R1 \
--port 8000 \
--dtype fp8 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: reasoning block parsing
DeepSeek R1 outputs reasoning inside `...` tags before the final answer.
```python
from openai import OpenAI
import re
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
response = client.chat.completions.create(
model="deepseek-ai/DeepSeek-R1-Distill-Qwen-7B",
messages=[{"role": "user", "content": "What is 17 × 23? Show your reasoning."}],
)
content = response.choices[0].message.content
# Extract reasoning and final answer
think_match = re.search(r"(.*?)", content, re.DOTALL)
if think_match:
reasoning = think_match.group(1).strip()
answer = content[think_match.end():].strip()
print("Reasoning:", reasoning)
print("Answer:", answer)
else:
print(content)
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### R1-Distill-7B (RTX 4090)
```yaml
#cloud-config
write_files:
- path: /etc/systemd/system/vllm-deepseek.service
content: |
[Unit]
Description=DeepSeek R1 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model deepseek-ai/DeepSeek-R1-Distill-Qwen-7B \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- systemctl daemon-reload
- systemctl enable vllm-deepseek
- systemctl start vllm-deepseek
```
#### DeepSeek-R1 671B (8× H100, FP8)
Replace the ExecStart line with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model deepseek-ai/DeepSeek-R1 \
--port 8000 \
--dtype fp8 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3): Meta Llama model guides
* [Instance Types](/concepts/instance-types): H100 NVLink cluster for full 671B
* [Cost Optimization](/cost-optimization): GPU tier selection for inference workloads
## Gemma 3
Deploy [Gemma 3](https://huggingface.co/google/gemma-3-27b-it) from Google DeepMind on Spheron GPU instances using vLLM. Gemma 3 is released under the [Gemma Terms of Use](https://ai.google.dev/gemma/terms), which permits commercial use and modification after accepting Google's license agreement.
:::warning[HuggingFace Token Required]
Gemma 3 models require accepting Google's terms on HuggingFace. Visit [google/gemma-3-27b-it](https://huggingface.co/google/gemma-3-27b-it) to request access, then set `HF_TOKEN` in your environment before running the server.
:::
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| --------------------- | --------------- | ----------------- | -------------- |
| Gemma-3-4B-IT | Any 8GB GPU | Spot | Lightweight |
| Gemma-3-12B-IT | RTX 4090 (24GB) | Dedicated or Spot | Full precision |
| Gemma-3-27B-IT | A100 80GB | Dedicated | Full precision |
| Gemma-3-27B-IT (INT4) | RTX 4090 (24GB) | Dedicated or Spot | AWQ 4-bit |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
HF_TOKEN= python3 -m vllm.entrypoints.openai.api_server \
--model google/gemma-3-12b-it \
--port 8000 \
--dtype bfloat16
```
Press `Ctrl+C` to stop. Replace `` with your HuggingFace token. For Gemma-3-27B on A100 80GB, replace the model with `google/gemma-3-27b-it`.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a restricted token file and a systemd service:
```bash
# Store the token in a file readable only by root
sudo mkdir -p /etc/vllm
sudo install -m 600 /dev/null /etc/vllm/hf-token
echo "HF_TOKEN=" | sudo tee -a /etc/vllm/hf-token > /dev/null
sudo tee /etc/systemd/system/vllm-gemma3.service > /dev/null << 'EOF'
[Unit]
Description=Gemma 3 vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model google/gemma-3-12b-it \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-gemma3
sudo systemctl start vllm-gemma3
```
Replace `` with your HuggingFace token. Using `EnvironmentFile=` with `chmod 600` prevents other local users from reading the token via `systemctl show`.
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example
```python
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
response = client.chat.completions.create(
model="google/gemma-3-12b-it",
messages=[{"role": "user", "content": "Explain the Apache 2.0 license in one paragraph."}],
)
print(response.choices[0].message.content)
```
:::info[Gemma Terms of Use]
Gemma 3 is released under the [Gemma Terms of Use](https://ai.google.dev/gemma/terms). You must accept Google's license agreement on HuggingFace before downloading the model weights. Commercial use and modification are permitted under these terms.
:::
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Gemma-3-12B (RTX 4090)
```yaml
#cloud-config
write_files:
- path: /etc/systemd/system/vllm-gemma3.service
content: |
[Unit]
Description=Gemma 3 vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model google/gemma-3-12b-it \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- mkdir -p /etc/vllm
- install -m 600 /dev/null /etc/vllm/hf-token
- echo "HF_TOKEN=" >> /etc/vllm/hf-token
- systemctl daemon-reload
- systemctl enable vllm-gemma3
- systemctl start vllm-gemma3
```
Replace `` with your HuggingFace token.
#### Gemma-3-27B (A100 80GB)
Replace the model in ExecStart with `google/gemma-3-27b-it`.
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Phi-4 & Phi-4 Multimodal](/quick-guides/llms/phi-4): Another efficient small model option
* [Instance Types](/concepts/instance-types): GPU selection for small models
* [Cost Optimization](/cost-optimization): Spot instances for Gemma 3
## LLM & AI Guides
Guides for running language model and AI inference workloads on Spheron GPU instances, from interactive chat interfaces to high-throughput OpenAI-compatible API servers.
### Choosing the right instance for inference
| Workload | Recommended Type | Why |
| ------------------------- | ------------------------ | ----------------------------------------- |
| Interactive chat, testing | Spot (RTX 4090) | Cost-effective for low-traffic usage |
| Production API (7B–13B) | Dedicated (H100 80GB) | Consistent latency, single-GPU throughput |
| Large models (30B+) | Dedicated (2× A100 80GB) | Multi-GPU tensor parallelism |
| 70B+ models | Cluster (H100 NVLink) | NVLink bandwidth for maximum throughput |
Use [Spot instances](/concepts/instance-types#spot) for experiments and development; switch to Dedicated for production traffic.
### Inference frameworks
Choose the right serving stack for your use case. See the [Inference Frameworks](/quick-guides/llms/frameworks) index for a comparison.
#### [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server)
OpenAI-compatible inference server using vLLM on H100 or A100. Includes a systemd service for persistence across reboots, SSH tunnel access, and performance tuning flags (`--tensor-parallel-size`, `--dtype`, `--max-model-len`).
**Best for:** Production API workloads; drop-in replacement for the OpenAI API.
#### [Ollama + Open WebUI](/quick-guides/llms/frameworks/ollama)
Browser-based chat interface backed by Ollama on an RTX 4090. Docker Compose setup with NVIDIA GPU passthrough; pull any model with a single command.
**Best for:** Interactive local model usage; exploring models without writing code.
#### [SGLang](/quick-guides/llms/frameworks/sglang)
Agentic LLM serving with RadixAttention for KV cache reuse, constrained decoding, and OpenAI-compatible API.
**Best for:** Agentic pipelines, multi-turn workloads, and structured output generation.
#### [TensorRT-LLM + Triton](/quick-guides/llms/frameworks/tensorrt-llm)
NVIDIA-optimized engine compilation via TensorRT-LLM with Triton Inference Server for production-grade serving.
**Best for:** Maximum throughput on NVIDIA GPUs; production deployments requiring low latency.
#### [llama.cpp Server](/quick-guides/llms/frameworks/llama-cpp)
GGUF model serving with CPU+GPU offload, lightweight and portable.
**Best for:** Running quantized models on consumer GPUs; mixed CPU/GPU inference.
#### [LMDeploy](/quick-guides/llms/frameworks/lmdeploy)
LMDeploy TurboMind inference toolkit with AWQ quantization support.
**Best for:** Memory-efficient deployment with AWQ-quantized models on A100/H100.
#### [LocalAI](/quick-guides/llms/frameworks/localai)
OpenAI-compatible drop-in replacement via Docker with support for LLMs, Whisper, and Stable Diffusion.
**Best for:** Multi-modal local inference with a single OpenAI-compatible endpoint.
### Text models
#### [DeepSeek R1 & V3](/quick-guides/llms/deepseek-r1)
DeepSeek reasoning models, from 7B distillations to the full 671B FP8 multi-GPU deployment. Includes `` reasoning block parsing.
**Best for:** Complex reasoning tasks, math, and code generation.
#### [Llama 4 Scout & Maverick](/quick-guides/llms/llama-4-scout)
Meta's latest multimodal MoE models (Scout 109B and Maverick 400B) with long-context and image understanding.
**Best for:** State-of-the-art multimodal reasoning with large context windows.
#### [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3)
Meta Llama 3 family: 8B on RTX 4090, 70B on 2× A100, 405B on 8× H100 with tensor parallelism and function calling.
**Best for:** General-purpose chat, instruction following, and function calling.
#### [Qwen3 Dense & MoE](/quick-guides/llms/qwen3)
Qwen3 text models with thinking mode toggle, 7B dense through 235B-A22B MoE on multi-GPU.
**Best for:** Reasoning tasks with controllable chain-of-thought via `/think` and `/no_think` tokens.
#### [Mistral & Mixtral](/quick-guides/llms/mistral-mixtral)
Mistral 7B, Mixtral 8x7B MoE, and Mistral Small 3.1 24B with function calling support.
**Best for:** Efficient inference with strong instruction following and function calling.
#### [Gemma 3](/quick-guides/llms/gemma-3)
Google DeepMind Gemma 3 in 4B, 12B, and 27B (INT4). Available under the Gemma Terms of Use; commercial use is permitted after accepting Google's license agreement on HuggingFace.
**Best for:** Low-latency inference on smaller GPUs; research and commercial projects.
#### [Phi-4 & Phi-4 Multimodal](/quick-guides/llms/phi-4)
Microsoft Phi-4 14B SLM and Phi-4-multimodal with image input support. MIT license.
**Best for:** Efficient SLM inference; multimodal tasks on a single RTX 4090.
### Multimodal models
#### [Qwen3-Omni-30B-A3B](/quick-guides/llms/multimodal/qwen3-omni-30b-a3b)
Multimodal language model with 30B parameters supporting text, audio, images, and video inputs. 32K context window (single GPU) on A100/H100.
**Best for:** Multimodal tasks requiring audio, vision, and text processing in a single model.
#### [Qwen3-VL 4B & 8B](/quick-guides/llms/multimodal/qwen3-vl-4b-8b)
Vision-language models available in 4B and 8B parameter variants. 256K context, multimodal reasoning, and GUI automation capabilities on RTX 4090 or A100.
**Best for:** Image understanding, visual reasoning, and GUI automation tasks.
#### [InternVL3](/quick-guides/llms/multimodal/internvl3)
InternVL3 vision-language model series, 8B through 78B, deployed via vLLM.
**Best for:** High-accuracy visual question answering and multimodal reasoning.
#### [LLaVA-Next](/quick-guides/llms/multimodal/llava-next)
LLaVA-NeXT vision-language model (7B/13B) with improved visual reasoning, deployed via vLLM.
**Best for:** Image-to-text tasks; accessible VLM on RTX 4090 or A100.
#### [Pixtral-12B](/quick-guides/llms/multimodal/pixtral-12b)
Mistral's Pixtral-12B multimodal model, deployed via vLLM on RTX 4090 (24GB).
**Best for:** Compact multimodal inference with Mistral-quality text generation.
#### [Baidu ERNIE-4.5-VL-28B-A3B](/quick-guides/llms/multimodal/baidu-ernie-4-5-vl-28b-a3b)
Advanced vision-language model from Baidu with 28B active parameters (MoE architecture). Strong visual reasoning and STEM task performance on RTX 4090 or A6000.
**Best for:** Visual reasoning, multimodal understanding, and STEM-domain tasks.
### Specialized models
#### [Chandra OCR](/quick-guides/llms/chandra-ocr)
Specialized OCR model for document processing with 83.1% accuracy, outperforming GPT-4o on document tasks. Supports vLLM deployment for high-throughput document pipelines.
**Best for:** Document digitization, text extraction, and OCR pipelines.
#### [Soulx Podcast-1.7B](/quick-guides/llms/soulx-podcast-1-7b)
Multi-speaker podcast generation model (1.7B parameters). Generates 60+ minute dialogues with speaker switching, zero-shot voice cloning, and paralinguistics.
**Best for:** Audio content generation, podcast production, and voice synthesis.
#### [Janus CoderV-8B](/quick-guides/llms/janus-coderv-8b)
8B multimodal code intelligence model. Generates HTML/CSS/React from screenshots, charts, and mockups. Trained on JANUSCODE-800K, the largest multimodal code dataset.
**Best for:** Visual-to-code translation, layout bug fixing, and UI mockup generation.
### What's next
* [Instance Types](/concepts/instance-types): Spot vs Dedicated vs Cluster
* [Networking](/concepts/networking): SSH tunneling and port access
* [Cost Optimization](/cost-optimization): Reducing inference costs with Spot instances
* [Templates & Images](/templates): Copy-ready startup scripts
import { YouTube } from '../../../components/YouTube'
## Janus CoderV-8B
Deploy [JanusCoderV-8B](https://huggingface.co/internlm/JanusCoderV-8B) on a Spheron GPU instance. JanusCoderV-8B is an 8B multimodal model that generates code from visual inputs including charts, screenshots, and UI mockups. It converts images into HTML, CSS, React components, and data visualization code.
### Key capabilities
* Visual-to-code translation: converts charts and screenshots to HTML and code
* Layout bug fixing from screenshot inputs
* Animation reconstruction using Manim
* 32K token context support
* Multimodal understanding across text, images, and code
**Benchmarks:**
* ChartMimic: 74.20 (beats Qwen2.5VL-7B, InternVL3.5-8B)
* WebCode2,M: 18.28 (best open-weight structural correctness)
* InteractScience: 33.32 (visual metrics leader)
### Requirements
**Hardware:**
* GPU: RTX 4090, A100, or H100 (16 GB VRAM minimum, 24 GB recommended)
* RAM: 16 GB (32 GB for large context workloads)
* Storage: 20 GB (SSD recommended)
**Software:**
* Ubuntu 22.04 LTS
* CUDA 12.1 or later
* Python 3.11
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Provision a Spheron instance
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. Click **Deploy** → **RTX 4090** → Region → **Ubuntu 22.04** → add your SSH key → **Deploy**
See [Getting Started](/getting-started) or [SSH Connection](/connecting/ssh-connection) for details.
#### Step 2: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `root` or `ubuntu`) and `` with your instance's public IP.
#### Step 3: Set up the environment
```bash
sudo apt update && apt install -y software-properties-common curl ca-certificates
sudo add-apt-repository -y ppa:deadsnakes/ppa
sudo apt update
```
#### Step 4: Install Python 3.11
```bash
sudo apt install -y python3.11 python3.11-venv python3.11-dev
python3.11 -m ensurepip --upgrade
python3.11 -m pip install --upgrade pip setuptools wheel
```
#### Step 5: Create virtual environment
```bash
python3.11 -m venv ~/.venvs/py311
source ~/.venvs/py311/bin/activate
```
#### Step 6: Install PyTorch (CUDA)
```bash
pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
```
#### Step 7: Install dependencies
```bash
pip install -U "transformers>=4.57.0" accelerate huggingface-hub safetensors pillow requests
pip install -U bitsandbytes
```
### Create the runner script
Create `run_januscoder.py` using nano, vim, or an SSH-capable editor:
```python
#!/usr/bin/env python3
# JanusCoderV-8B runner (InternVL head)
# Uses AutoModelForImageTextToText + AutoProcessor and supports URL/local images.
import argparse
import io
import sys
import requests
import torch
from PIL import Image
from transformers import AutoProcessor, AutoModelForImageTextToText # <-- key class
MODEL_NAME = "internlm/JanusCoderV-8B"
def load_image_from_url(url: str) -> Image.Image:
response = requests.get(url, timeout=30)
response.raise_for_status()
return Image.open(io.BytesIO(response.content)).convert("RGB")
def load_image_local(path: str) -> Image.Image:
return Image.open(path).convert("RGB")
def main():
parser = argparse.ArgumentParser()
source_group = parser.add_mutually_exclusive_group(required=True)
source_group.add_argument("--image-url", type=str, help="URL of the image to process")
source_group.add_argument("--image-path", type=str, help="Local path to the image file")
parser.add_argument("--task", type=str, default="Please describe the image explicitly.", help="Task description for the model")
parser.add_argument("--max-new-tokens", type=int, default=1024, help="Maximum number of new tokens to generate")
parser.add_argument("--bits8", action="store_true", help="Load model in 8-bit mode (requires bitsandbytes)")
parser.add_argument("--no-bf16", action="store_true", help="Force FP16 inputs instead of BF16")
args = parser.parse_args()
use_bf16 = (not args.no_bf16) and torch.cuda.is_available() and torch.cuda.is_bf16_supported()
input_dtype = torch.bfloat16 if use_bf16 else torch.float16
print(f"torch={torch.__version__} | cuda={torch.cuda.is_available()} | bf16_ok={use_bf16} | dtype={input_dtype}")
print("Loading processor …")
processor = AutoProcessor.from_pretrained(MODEL_NAME, trust_remote_code=True)
print("Loading model …")
load_kwargs = dict(device_map="auto", trust_remote_code=True)
if args.bits8:
load_kwargs["load_in_8bit"] = True
else:
load_kwargs["torch_dtype"] = input_dtype # Use torch_dtype for consistency
model = AutoModelForImageTextToText.from_pretrained(MODEL_NAME, **load_kwargs).eval()
# Build messages with either URL or PIL image
content = []
if args.image_url:
content.append({"type": "image", "url": args.image_url})
else:
pil_image = load_image_local(args.image_path)
content.append({"type": "image", "image": pil_image})
content.append({"type": "text", "text": args.task})
messages = [{"role": "user", "content": content}]
print("Tokenizing …")
inputs = processor.apply_chat_template(
messages,
add_generation_prompt=True,
tokenize=True,
return_dict=True,
return_tensors="pt",
)
# Move input tensors to model device/dtype
device = next(iter(model.parameters())).device
for key, value in list(inputs.items()):
if torch.is_floating_point(value):
inputs[key] = value.to(device, dtype=input_dtype)
else:
inputs[key] = value.to(device)
print("Generating …")
with torch.inference_mode():
output_ids = model.generate(**inputs, max_new_tokens=args.max_new_tokens, do_sample=False, use_cache=True)
prompt_length = inputs["input_ids"].shape[1]
generated_text = processor.decode(output_ids[0, prompt_length:], skip_special_tokens=True)
print("\n" + "=" * 80 + "\nOUTPUT:\n" + "=" * 80)
print(generated_text)
if __name__ == "__main__":
main()
```
### Usage examples
#### Basic image description
```bash
python run_januscoder.py \
--image-url https://c7.alamy.com/comp/BHKEPY/woman-running-with-two-rottweilers-canis-lupus-familiaris-in-garden-BHKEPY.jpg
```
#### Generate HTML/CSS from a mockup
```bash
python run_januscoder.py \
--image-url https://example.com/mockup.jpg \
--task "Generate responsive HTML+CSS from this mockup."
```
#### Process a local image
```bash
python run_januscoder.py \
--image-path /path/to/image.jpg \
--task "Convert this UI mockup into React components."
```
#### Convert a chart to code
```bash
python run_januscoder.py \
--image-url https://example.com/chart.png \
--task "Generate matplotlib code to recreate this chart."
```
#### Fix layout bugs
```bash
python run_januscoder.py \
--image-path screenshot.png \
--task "Identify layout issues and provide corrected CSS."
```
### Configuration
**Arguments:**
* `--image-url` or `--image-path`: Input source (URL or local file path)
* `--task`: Task description (default: "describe image")
* `--max-new-tokens`: Maximum output length (default: 1024)
* `--bits8`: Enable 8-bit quantization to reduce VRAM usage
* `--no-bf16`: Force FP16 for GPU compatibility
8-bit quantization for low VRAM:
```bash
python run_januscoder.py --image-url --bits8
```
Long output for complex tasks:
```bash
python run_januscoder.py --image-url --max-new-tokens 4096
```
FP16 mode for GPU compatibility:
```bash
python run_januscoder.py --image-url --no-bf16
```
### Performance optimization
* **Memory:** Use `--bits8`, lower `--max-new-tokens`, and batch smaller workloads.
* **Speed:** Use BF16 on A100 and H100 GPUs; ensure CUDA is properly configured and caching is enabled.
* **Quality:** Use high-resolution images, write detailed task prompts, and increase `--max-new-tokens` for complex outputs.
### Use cases
* **Web development:** Convert mockups to HTML/CSS, generate responsive layouts, fix layout bugs, create React and Vue components.
* **Data visualization:** Convert charts to matplotlib or plotly code and generate interactive dashboards.
* **Animation:** Rebuild animations using Manim, generate SVG, or create CSS animations.
* **Documentation:** Generate code explanations, visual docs, and GUI documentation from screenshots.
### Troubleshooting
#### Issue: Out-of-memory (OOM) error
Use 8-bit quantization, reduce output length, or switch to FP16:
```bash
# Use 8-bit quantization
python run_januscoder.py --image-url --bits8
# Reduce output length
python run_januscoder.py --image-url --max-new-tokens 512
# Use FP16
python run_januscoder.py --image-url --no-bf16
```
#### Issue: Model download failures
Set a custom cache directory with sufficient storage:
```bash
export HF_HOME=/path/to/large/storage
export TRANSFORMERS_CACHE=/path/to/large/storage
python run_januscoder.py --image-url
```
#### Issue: CUDA errors
Verify CUDA availability and reinstall PyTorch if needed:
```bash
python -c "import torch; print(torch.cuda.is_available())"
nvidia-smi
pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
```
#### Issue: Image loading errors
Download the image locally or fix file permissions:
```bash
wget https://example.com/image.jpg
python run_januscoder.py --image-path image.jpg --task "Your task"
chmod 644 /path/to/image.jpg
```
### Best practices
* **Prompts:** Be specific. Include the target format (HTML/CSS, Python) and framework (React, Vue).
* **Images:** Use high-resolution, well-lit, and cropped images in standard formats (JPEG or PNG).
* **Output:** Save generated code to files, review before use, iterate on prompts, and track what works.
* **Resources:** Monitor GPU usage with `nvidia-smi`, close unused processes, use quantization, and batch tasks where possible.
### Integration example
Python subprocess wrapper:
```python
import subprocess
def generate_code_from_image(image_path, task):
cmd = ["python", "run_januscoder.py", "--image-path", image_path, "--task", task, "--max-new-tokens", "2048"]
result = subprocess.run(cmd, capture_output=True, text=True)
return result.stdout
code = generate_code_from_image("mockup.png", "Generate React components")
```
Flask API wrapper:
```python
from flask import Flask, request, jsonify
import subprocess
app = Flask(__name__)
@app.route('/generate', methods=['POST'])
def generate():
data = request.json
cmd = ["python", "run_januscoder.py", "--image-url", data['image_url'], "--task", data.get('task', 'Describe')]
result = subprocess.run(cmd, capture_output=True, text=True)
return jsonify({"code": result.stdout})
app.run(port=5000)
```
### Performance on Spheron
| Task | RTX 4090 time | A100 time | VRAM usage |
| -------------------------- | ------------- | --------- | ---------- |
| Simple description | 5 s | 3 s | 12 GB |
| HTML generation | 10 s | 6 s | 14 GB |
| Complex output (2K tokens) | 20 s | 12 s | 16 GB |
| Full output (4K tokens) | 40 s | 24 s | 18 GB |
### Supported output formats
* **Web:** HTML/CSS, JavaScript, React, Vue, Tailwind, Bootstrap
* **Data visualization:** Python (matplotlib, plotly), JavaScript (D3, Chart.js), R (ggplot2)
* **Animation:** Manim, CSS, JavaScript, SVG
* **Other:** SVG, LaTeX, Processing, Three.js
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the environment setup. After the instance is ready, SSH in, activate the virtual environment, and create the `run_januscoder.py` script following the [Create Runner Script](#create-runner-script) section above.
```yaml
#cloud-config
runcmd:
- apt update && apt install -y software-properties-common curl ca-certificates
- add-apt-repository -y ppa:deadsnakes/ppa
- apt update
- apt install -y python3.11 python3.11-venv python3.11-dev
- python3.11 -m ensurepip --upgrade
- python3.11 -m pip install --upgrade pip setuptools wheel
- python3.11 -m venv /opt/januscoder
- /opt/januscoder/bin/pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
- /opt/januscoder/bin/pip install -U "transformers>=4.57.0" accelerate huggingface-hub safetensors pillow requests bitsandbytes
```
After cloud-init completes, SSH in, activate the environment, and create the runner script:
```bash
source /opt/januscoder/bin/activate
# Create run_januscoder.py as shown in the "Create the runner script" section above
python run_januscoder.py --image-url https://example.com/image.jpg
```
### What's next
* [Specialized Models](/quick-guides/llms/specialized-models): Compare Janus CoderV with Chandra OCR and SoulX Podcast
* [Instance Types](/concepts/instance-types): Select the right GPU for multimodal code generation
* [Getting Started](/getting-started): Create a Spheron account and deploy your first instance
* [SSH Connection](/connecting/ssh-connection): Connect to your instance after deployment
## Llama 3.1 / 3.2 / 3.3
Deploy Meta's Llama 3 family on Spheron GPU instances using vLLM. The Llama 3 series covers 8B through 405B parameters with strong instruction following and function calling capabilities.
:::warning[HuggingFace Token Required]
Llama 3 models are gated on HuggingFace. Request access at [meta-llama/Meta-Llama-3.1-8B-Instruct](https://huggingface.co/meta-llama/Meta-Llama-3.1-8B-Instruct), then set `HF_TOKEN` in your environment before running the server.
:::
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| -------------------- | --------------- | ----------------- | -------------------------------------- |
| Llama 3.1/3.2/3.3 8B | RTX 4090 (24GB) | Dedicated or Spot | Single-GPU |
| Llama 3.1 70B | 2× A100 80GB | Dedicated | `--tensor-parallel-size 2` |
| Llama 3.1 405B | 8× H100 80GB | Cluster | `--tensor-parallel-size 8 --dtype fp8` |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
HF_TOKEN= python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-8B-Instruct \
--port 8000 \
--dtype bfloat16
```
Press `Ctrl+C` to stop. Replace `` with your HuggingFace token.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a restricted token file and a systemd service:
```bash
# Store the token in a file readable only by root
sudo mkdir -p /etc/vllm
sudo install -m 600 /dev/null /etc/vllm/hf-token
echo "HF_TOKEN=" | sudo tee -a /etc/vllm/hf-token > /dev/null
sudo tee /etc/systemd/system/vllm-llama3.service > /dev/null << 'EOF'
[Unit]
Description=Llama 3 vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-8B-Instruct \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-llama3
sudo systemctl start vllm-llama3
```
Replace `` with your HuggingFace token. Using `EnvironmentFile=` with `chmod 600` prevents other local users from reading the token via `systemctl show`.
#### Llama 3.1 70B (2× A100 80GB)
For the 70B model, replace the `ExecStart` command with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-70B-Instruct \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 2
```
#### Llama 3.1 405B (8× H100)
The 405B model in BF16 requires more than 640 GB VRAM and cannot run on a single 8× H100 node. Use the official FP8 quantized variant, which fits within the 640 GB total VRAM available across 8× H100 80GB.
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-405B-Instruct-FP8 \
--port 8000 \
--dtype fp8 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: function calling (Llama 3.1/3.3)
```python
from openai import OpenAI
import json
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
tools = [
{
"type": "function",
"function": {
"name": "get_weather",
"description": "Get current weather for a city",
"parameters": {
"type": "object",
"properties": {"city": {"type": "string"}},
"required": ["city"],
},
},
}
]
response = client.chat.completions.create(
model="meta-llama/Meta-Llama-3.1-8B-Instruct",
messages=[{"role": "user", "content": "What is the weather in Paris?"}],
tools=tools,
tool_choice="auto",
)
if response.choices[0].message.tool_calls:
tool_call = response.choices[0].message.tool_calls[0]
print(f"Function: {tool_call.function.name}")
print(f"Arguments: {tool_call.function.arguments}")
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Llama 3.1 8B (RTX 4090)
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- mkdir -p /etc/vllm
- install -m 600 /dev/null /etc/vllm/hf-token
- echo "HF_TOKEN=" >> /etc/vllm/hf-token
- |
cat > /etc/systemd/system/vllm-llama3.service << 'EOF'
[Unit]
Description=Llama 3 vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-8B-Instruct \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-llama3
- systemctl start vllm-llama3
```
#### Llama 3.1 70B (2× A100 80GB)
Replace the ExecStart line with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-70B-Instruct \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 2
```
#### Llama 3.1 405B (8× H100)
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-405B-Instruct-FP8 \
--port 8000 \
--dtype fp8 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### What's next
* [Llama 4 Scout & Maverick](/quick-guides/llms/llama-4-scout): Latest Llama generation
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Instance Types](/concepts/instance-types): Multi-GPU setup for 70B+ models
* [Cost Optimization](/cost-optimization): Spot vs Dedicated for inference workloads
## Llama 4 Scout & Maverick
Deploy [Meta Llama 4](https://huggingface.co/meta-llama) Scout and Maverick on Spheron GPU instances using vLLM. Llama 4 introduces a Mixture-of-Experts (MoE) architecture with native multimodal support for text and images.
:::warning[HuggingFace Token Required]
Llama 4 models are gated on HuggingFace. Request access at [meta-llama/Llama-4-Scout-17B-16E-Instruct](https://huggingface.co/meta-llama/Llama-4-Scout-17B-16E-Instruct), then set `HF_TOKEN` in your environment before running the server.
:::
### Recommended hardware
| Model | Parameters | Recommended GPU | Instance Type | Notes |
| ---------------- | ----------------- | --------------- | ------------- | ------------------ |
| Llama 4 Scout | 109B (17B active) | H100 80GB (FP8) | Dedicated | MoE, 16 experts |
| Llama 4 Maverick | 400B (17B active) | 8× H200 141 GB | Cluster | Requires multi-GPU |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
HF_TOKEN= python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Llama-4-Scout-17B-16E-Instruct \
--port 8000 \
--dtype fp8 \
--gpu-memory-utilization 0.95
```
Press `Ctrl+C` to stop. Replace `` with your HuggingFace token.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a restricted token file and a systemd service:
```bash
# Store the token in a file readable only by root
sudo mkdir -p /etc/vllm
sudo install -m 600 /dev/null /etc/vllm/hf-token
echo "HF_TOKEN=" | sudo tee -a /etc/vllm/hf-token > /dev/null
sudo tee /etc/systemd/system/vllm-llama4.service > /dev/null << 'EOF'
[Unit]
Description=Llama 4 Scout vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Llama-4-Scout-17B-16E-Instruct \
--port 8000 \
--dtype fp8 \
--gpu-memory-utilization 0.95
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-llama4
sudo systemctl start vllm-llama4
```
Replace `` with your HuggingFace token. Using `EnvironmentFile=` with `chmod 600` prevents other local users from reading the token via `systemctl show`.
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: multimodal image input
```python
import base64
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
with open("image.jpg", "rb") as f:
image_b64 = base64.b64encode(f.read()).decode()
response = client.chat.completions.create(
model="meta-llama/Llama-4-Scout-17B-16E-Instruct",
messages=[
{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_b64}"}},
{"type": "text", "text": "What is in this image?"},
],
}
],
)
print(response.choices[0].message.content)
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Llama 4 Scout (H100, FP8)
```yaml
#cloud-config
write_files:
- path: /etc/systemd/system/vllm-llama4.service
content: |
[Unit]
Description=Llama 4 Scout vLLM Inference Server
After=network.target
[Service]
Type=simple
EnvironmentFile=/etc/vllm/hf-token
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Llama-4-Scout-17B-16E-Instruct \
--port 8000 \
--dtype fp8 \
--gpu-memory-utilization 0.95
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- mkdir -p /etc/vllm
- install -m 600 /dev/null /etc/vllm/hf-token
- echo "HF_TOKEN=" >> /etc/vllm/hf-token
- systemctl daemon-reload
- systemctl enable vllm-llama4
- systemctl start vllm-llama4
```
Replace `` with your HuggingFace token.
### What's next
* [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3): Previous Llama generation guides
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Instance Types](/concepts/instance-types): H100/H200 cluster requirements
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
## Mistral & Mixtral
Deploy [Mistral AI](https://huggingface.co/mistralai) models on Spheron GPU instances using vLLM. Includes Mistral 7B for single-GPU deployment, Mixtral 8x7B MoE (requires \~90 GB VRAM in bfloat16, needs 2× A100 80GB), and Mistral Small 3.1 24B.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| -------------------------- | --------------- | ----------------- | ----------------------------- |
| Mistral-7B-Instruct-v0.3 | RTX 4090 (24GB) | Dedicated or Spot | Fits in 16GB VRAM |
| Mixtral-8x7B-Instruct-v0.1 | 2× A100 80GB | Dedicated | MoE, \~90 GB VRAM in bfloat16 |
| Mistral-Small-3.1-24B | A100 80GB | Dedicated | Full precision (\~55GB VRAM) |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Mistral-7B-Instruct-v0.3 \
--port 8000 \
--dtype bfloat16
```
Press `Ctrl+C` to stop.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-mistral.service > /dev/null << 'EOF'
[Unit]
Description=Mistral vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Mistral-7B-Instruct-v0.3 \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-mistral
sudo systemctl start vllm-mistral
```
#### Mixtral 8x7B (2× A100 80GB)
For the Mixtral MoE model, replace the `ExecStart` command with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Mixtral-8x7B-Instruct-v0.1 \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 2
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: function calling
```python
from openai import OpenAI
import json
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
tools = [
{
"type": "function",
"function": {
"name": "search_web",
"description": "Search the web for information",
"parameters": {
"type": "object",
"properties": {"query": {"type": "string"}},
"required": ["query"],
},
},
}
]
response = client.chat.completions.create(
model="mistralai/Mistral-7B-Instruct-v0.3",
messages=[{"role": "user", "content": "Search for the latest GPU benchmarks."}],
tools=tools,
tool_choice="auto",
)
if response.choices[0].message.tool_calls:
tool_call = response.choices[0].message.tool_calls[0]
print(f"Function: {tool_call.function.name}")
print(f"Arguments: {tool_call.function.arguments}")
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Mistral 7B (RTX 4090)
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-mistral.service << 'EOF'
[Unit]
Description=Mistral vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Mistral-7B-Instruct-v0.3 \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-mistral
- systemctl start vllm-mistral
```
#### Mixtral 8x7B (2× A100 80GB)
Replace the ExecStart line with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Mixtral-8x7B-Instruct-v0.1 \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 2
```
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3): Meta Llama model guides
* [Instance Types](/concepts/instance-types): GPU selection for MoE models
* [Cost Optimization](/cost-optimization): Spot instances for Mistral 7B
## Phi-4 & Phi-4 Multimodal
Deploy [Microsoft Phi-4](https://huggingface.co/microsoft/phi-4) and [Phi-4-multimodal](https://huggingface.co/microsoft/Phi-4-multimodal-instruct) on Spheron GPU instances using vLLM. Phi-4 is a 14B parameter small language model (SLM) with strong reasoning capabilities released under the MIT license.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| ---------------- | ----------------------- | ------------- | ------------------ |
| Phi-4 (14B) | A100 40GB | Dedicated | Full precision |
| Phi-4-multimodal | RTX 4090 (24GB) or A100 | Dedicated | Image + text input |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model microsoft/phi-4 \
--port 8000 \
--dtype bfloat16 \
--trust-remote-code
```
Press `Ctrl+C` to stop. For Phi-4-multimodal, replace `microsoft/phi-4` with `microsoft/Phi-4-multimodal-instruct`.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-phi4.service > /dev/null << 'EOF'
[Unit]
Description=Phi-4 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model microsoft/phi-4 \
--port 8000 \
--dtype bfloat16 \
--trust-remote-code
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-phi4
sudo systemctl start vllm-phi4
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: text
```python
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
response = client.chat.completions.create(
model="microsoft/phi-4",
messages=[{"role": "user", "content": "Write a Python function that checks if a number is prime."}],
)
print(response.choices[0].message.content)
```
### Usage example: image input (Phi-4-multimodal)
```python
import base64
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
with open("image.jpg", "rb") as f:
image_b64 = base64.b64encode(f.read()).decode()
response = client.chat.completions.create(
model="microsoft/Phi-4-multimodal-instruct",
messages=[
{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_b64}"}},
{"type": "text", "text": "What is shown in this image?"},
],
}
],
)
print(response.choices[0].message.content)
```
:::info[MIT License]
Phi-4 is released under the [MIT license](https://opensource.org/licenses/MIT), allowing commercial use and modification without restrictions.
:::
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Phi-4 (A100 40GB)
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-phi4.service << 'EOF'
[Unit]
Description=Phi-4 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model microsoft/phi-4 \
--port 8000 \
--dtype bfloat16 \
--trust-remote-code
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-phi4
- systemctl start vllm-phi4
```
#### Phi-4-multimodal
Replace the model in ExecStart with `microsoft/Phi-4-multimodal-instruct`.
### What's next
* [Gemma 3](/quick-guides/llms/gemma-3): Another efficient small model option (Gemma Terms of Use)
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Instance Types](/concepts/instance-types): GPU selection for SLMs
## Qwen3 Dense & MoE
Deploy [Qwen3](https://huggingface.co/Qwen) dense and Mixture-of-Experts (MoE) models on Spheron GPU instances using vLLM. Qwen3 introduces a thinking mode that can be toggled at inference time using system prompt tokens.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| --------------- | --------------- | ----------------- | ------------------------------- |
| Qwen3-8B | RTX 4090 (24GB) | Dedicated or Spot | Dense, single-GPU |
| Qwen3-14B | A100 40GB | Dedicated | Dense |
| Qwen3-32B | A100 80GB | Dedicated | Dense |
| Qwen3-30B-A3B | A100 80GB | Dedicated | MoE, 3B active params |
| Qwen3-235B-A22B | 8× H100 80GB | Cluster | MoE, `--tensor-parallel-size 8` |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model Qwen/Qwen3-32B \
--port 8000 \
--dtype bfloat16
```
Press `Ctrl+C` to stop.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-qwen3.service > /dev/null << 'EOF'
[Unit]
Description=Qwen3 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model Qwen/Qwen3-32B \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-qwen3
sudo systemctl start vllm-qwen3
```
#### Qwen3-235B-A22B MoE (8× H100)
For the large MoE model, replace the `ExecStart` command with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model Qwen/Qwen3-235B-A22B \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: thinking mode
Qwen3 supports toggleable chain-of-thought reasoning via system prompt tokens.
```python
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
# Enable thinking mode (default for instruction models)
response_think = client.chat.completions.create(
model="Qwen/Qwen3-32B",
messages=[
{"role": "system", "content": "/think"},
{"role": "user", "content": "Solve: if x² + 3x - 10 = 0, what is x?"},
],
)
# Disable thinking mode for faster responses
response_no_think = client.chat.completions.create(
model="Qwen/Qwen3-32B",
messages=[
{"role": "system", "content": "/no_think"},
{"role": "user", "content": "What is the capital of France?"},
],
)
print("With thinking:", response_think.choices[0].message.content[:200])
print("Without thinking:", response_no_think.choices[0].message.content)
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
#### Qwen3-32B (A100 80GB)
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-qwen3.service << 'EOF'
[Unit]
Description=Qwen3 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model Qwen/Qwen3-32B \
--port 8000 \
--dtype bfloat16
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-qwen3
- systemctl start vllm-qwen3
```
#### Qwen3-235B-A22B MoE (8× H100)
Replace the ExecStart line with:
```bash
/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model Qwen/Qwen3-235B-A22B \
--port 8000 \
--dtype bfloat16 \
--tensor-parallel-size 8 \
--gpu-memory-utilization 0.95
```
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [DeepSeek R1 & V3](/quick-guides/llms/deepseek-r1): Another reasoning model option
* [Instance Types](/concepts/instance-types): Multi-GPU setup for MoE models
* [Cost Optimization](/cost-optimization): Spot instances for development
import { YouTube } from '../../../components/YouTube'
## SoulX Podcast-1.7B
Deploy [SoulX Podcast-1.7B](https://huggingface.co/Soul-AILab/SoulX-Podcast-1.7B) on a Spheron GPU instance. SoulX Podcast-1.7B is a 1.7B parameter speech generation model that produces multi-speaker podcast dialogues with speaker switching, zero-shot voice cloning, and paralinguistic elements such as laughter and sighs. It supports English, Mandarin, and several Chinese dialects.
### Key capabilities
* **Multi-speaker dialogue:** Maintains consistency across turns and handles interruptions
* **Zero-shot voice cloning:** Replicates voices from 10 to 30 second reference samples
* **Paralinguistics:** Generates laughter, sighs, throat clearing, and intonation shifts
* **Multi-language:** Supports English, Mandarin, Sichuanese, Henanese, and Cantonese
* **Efficient deployment:** Runs on GPUs ranging from RTX 4060 to H100
**Resources:**
* [HuggingFace Model](https://huggingface.co/Soul-AILab/SoulX-Podcast-1.7B)
* [GitHub Repository](https://github.com/Soul-AILab/SoulX-Podcast)
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Provision a Spheron instance
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. Click **Deploy** → **RTX 4090** (or RTX 4060+ for testing) → Region → **Ubuntu 22.04** → add your SSH key → **Deploy**
See [Getting Started](/getting-started) or [SSH Connection](/connecting/ssh-connection) for details.
#### Step 2: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `root` or `ubuntu`) and `` with your instance's public IP.
#### Step 3: Set up the environment
```bash
sudo apt update && apt install -y software-properties-common curl ca-certificates
sudo add-apt-repository -y ppa:deadsnakes/ppa
sudo apt update
```
#### Step 4: Install Python 3.11
```bash
sudo apt install -y python3.11 python3.11-venv python3.11-dev
python3.11 -m ensurepip --upgrade
python3.11 -m pip install --upgrade pip setuptools wheel
```
#### Step 5: Install Miniconda
```bash
curl -O https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh -b -p $HOME/miniconda3
$HOME/miniconda3/bin/conda init bash
source ~/.bashrc
```
#### Step 6: Create conda environment
```bash
conda create -n soulxpodcast -y python=3.11
```
Accept ToS if prompted:
```bash
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/main
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/r
```
#### Step 7: Activate environment
```bash
conda activate soulxpodcast
```
#### Step 8: Clone the repository
```bash
git clone https://github.com/Soul-AILab/SoulX-Podcast.git
cd SoulX-Podcast
```
#### Step 9: Install dependencies
```bash
pip install -r requirements.txt
pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
pip install "transformers==4.57.1" "huggingface_hub<1.0,>=0.34.0"
```
### Download models
#### Base model (English/Mandarin)
```bash
huggingface-cli download --resume-download Soul-AILab/SoulX-Podcast-1.7B \
--local-dir pretrained_models/SoulX-Podcast-1.7B
```
#### Dialect model (Sichuanese/Henanese/Cantonese)
```bash
huggingface-cli download --resume-download Soul-AILab/SoulX-Podcast-1.7B-dialect \
--local-dir pretrained_models/SoulX-Podcast-1.7B-dialect
```
### Test the model
```bash
bash example/infer_dialogue.sh
```
Check `outputs/` directory for generated `.wav` files.
### Launch the WebUI
#### Modify webui.py
Change `share=False` to `share=True`:
```python
# In webui.py:
share=True
```
#### Start the WebUI
Base model:
```bash
python3 webui.py --model_path pretrained_models/SoulX-Podcast-1.7B
```
Dialect model:
```bash
python3 webui.py --model_path pretrained_models/SoulX-Podcast-1.7B-dialect
```
Open the Gradio link printed in the terminal (e.g., `https://baccd06ba693323c35.gradio.live`) to access the interface.
### Troubleshooting
#### Issue: Low audio quality
Set a higher sample rate:
```bash
python3 webui.py --model_path pretrained_models/SoulX-Podcast-1.7B --sample_rate 48000
```
#### Issue: Out-of-memory (OOM) error
Increase the CUDA memory split size:
```bash
export PYTORCH_CUDA_ALLOC_CONF=max_split_size_mb:512
```
#### Issue: Model download failures
Set a custom cache directory and retry the download:
```bash
export HF_HOME=/path/to/cache
huggingface-cli download --resume-download Soul-AILab/SoulX-Podcast-1.7B
```
#### Issue: CUDA errors
Verify CUDA availability, check GPU status, and reinstall PyTorch if needed:
```bash
python -c "import torch; print(torch.cuda.is_available())"
nvidia-smi
pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
```
#### Issue: Gradio interface not accessible
Ensure `share=True` is set in `webui.py`, then allow the port through the firewall or specify an alternate port:
```bash
sudo ufw allow 7860/tcp
python3 webui.py --model_path pretrained_models/SoulX-Podcast-1.7B --server_port 8080
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the environment setup. After the instance is ready, SSH in, activate the conda environment, and follow the [Download Models](#download-models) and [Launch WebUI](#launch-webui) steps.
```yaml
#cloud-config
runcmd:
- apt update && apt install -y software-properties-common curl ca-certificates git
- add-apt-repository -y ppa:deadsnakes/ppa
- apt update
- apt install -y python3.11 python3.11-venv python3.11-dev
- curl -fsSL -o /tmp/miniconda.sh https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
- bash /tmp/miniconda.sh -b -p /opt/miniconda3
- /opt/miniconda3/bin/conda create -n soulxpodcast -y python=3.11
- /opt/miniconda3/bin/conda run -n soulxpodcast pip install --index-url https://download.pytorch.org/whl/cu121 torch torchvision torchaudio
- git clone https://github.com/Soul-AILab/SoulX-Podcast.git /opt/SoulX-Podcast
- /opt/miniconda3/bin/conda run -n soulxpodcast pip install -r /opt/SoulX-Podcast/requirements.txt
- /opt/miniconda3/bin/conda run -n soulxpodcast pip install "transformers==4.57.1" "huggingface_hub<1.0,>=0.34.0"
```
After cloud-init completes, SSH in and download the model:
```bash
source /opt/miniconda3/bin/activate soulxpodcast
cd /opt/SoulX-Podcast
huggingface-cli download --resume-download Soul-AILab/SoulX-Podcast-1.7B \
--local-dir pretrained_models/SoulX-Podcast-1.7B
python3 webui.py --model_path pretrained_models/SoulX-Podcast-1.7B
```
### What's next
* [Specialized Models](/quick-guides/llms/specialized-models): Compare SoulX Podcast with Chandra OCR and Janus CoderV
* [Instance Types](/concepts/instance-types): Select the right GPU tier for audio generation workloads
* [Getting Started](/getting-started): Create a Spheron account and deploy your first instance
* [SSH Connection](/connecting/ssh-connection): Connect to your instance after deployment
## Specialized Models
Guides for deploying task-specific AI models on Spheron GPU instances. These models are purpose-built for document processing, audio generation, and visual code intelligence rather than general-purpose chat.
### Available guides
#### [Chandra OCR](/quick-guides/llms/chandra-ocr)
State-of-the-art document processing model with 83.1% accuracy on the olmOCR benchmark, outperforming GPT-4o, Gemini Flash 2, and Mistral OCR. Converts images and PDFs to structured Markdown, HTML, or JSON while preserving layout, tables, and formulas.
**Best for:** Document digitization, text extraction from PDFs and scanned documents, OCR pipelines with 40+ language support.
**Deployment:** CPU (dev/test) through distributed H100 (enterprise). Supports local inference via HuggingFace transformers and high-throughput via vLLM server.
#### [SoulX Podcast-1.7B](/quick-guides/llms/soulx-podcast-1-7b)
Multi-speaker podcast generation model (1.7B parameters). Generates 60+ minute dialogues with natural speaker switching, zero-shot voice cloning from 10–30 second samples, and paralinguistic expressions (laughter, sighs, intonation).
**Best for:** Audio content generation, podcast production, multi-speaker voice synthesis, and zero-shot voice cloning.
**Deployment:** RTX 4060 (testing) to H100 (production). Runs via a Gradio web interface.
#### [Janus CoderV-8B](/quick-guides/llms/janus-coderv-8b)
8B multimodal code intelligence model trained on JANUSCODE-800K, the largest multimodal code dataset. Generates HTML, CSS, and React components from screenshots, mockups, charts, and animations. Supports 32K token context.
**Best for:** Visual-to-code translation, UI mockup generation, layout bug fixing from screenshots, and chart-to-code conversion.
**Deployment:** RTX 4090 (standard) through H100 (high throughput). Supports 8-bit quantization for reduced VRAM.
### Hardware overview
| Model | Min VRAM | Recommended GPU | Notes |
| ------------------- | -------- | ---------------- | -------------------- |
| Chandra OCR (4-bit) | 6GB | RTX 3060/4060 Ti | Quantized |
| Chandra OCR (BF16) | 16GB | RTX 4090 / L40S | Full precision |
| SoulX Podcast-1.7B | 4GB | RTX 4060+ | RTX 4090 recommended |
| Janus CoderV-8B | 16GB | RTX 4090 (24GB) | 8-bit: \~12GB |
### What's next
* [Text Models](/quick-guides/llms/text-models): General-purpose LLM guides
* [Multimodal Models](/quick-guides/llms/multimodal): Vision-language model guides
* [Instance Types](/concepts/instance-types): GPU selection
* [Getting Started](/getting-started): Spheron account and instance setup
## Text Models
Guides for deploying large language models (LLMs) on Spheron GPU instances. All models are served via vLLM's OpenAI-compatible API unless otherwise noted.
### VRAM requirements
| Model | Parameters | Min VRAM | Recommended GPU |
| ------------------------------ | ---------- | -------- | --------------- |
| DeepSeek-R1-Distill-7B | 7B | 16GB | RTX 4090 (24GB) |
| Llama 3.1/3.2/3.3 8B | 8B | 16GB | RTX 4090 (24GB) |
| Mistral 7B | 7B | 14GB | RTX 4090 (24GB) |
| Gemma 3 12B | 12B | 24GB | RTX 4090 (24GB) |
| Phi-4 14B | 14B | 24GB | RTX 4090 (24GB) |
| Qwen3-32B | 32B | 64GB | A100 80GB |
| DeepSeek-R1-Distill-32B (INT4) | 32B | 20GB | A100 40GB |
| Llama 3.1 70B | 70B | 140GB | 2× A100 80GB |
| Mixtral 8x7B | \~47B | 90GB | 2× A100 80GB |
| Llama 4 Scout 109B (INT4) | 17B active | 40GB | H100 80GB |
| DeepSeek-R1 671B (FP8) | 671B | 8× H100 | 8× H100 80GB |
### Available guides
#### [DeepSeek R1 & V3](/quick-guides/llms/deepseek-r1)
DeepSeek's reasoning models, from 7B distillations on RTX 4090 to the full 671B FP8 deployment on 8× H100. Features chain-of-thought reasoning exposed via `` blocks.
**Best for:** Complex reasoning, math, and code generation tasks.
#### [Llama 4 Scout & Maverick](/quick-guides/llms/llama-4-scout)
Meta's latest multimodal MoE models (Scout at 109B total/17B active, Maverick at 400B total/17B active) with long-context and native image understanding.
**Best for:** State-of-the-art multimodal reasoning and large context windows.
#### [Llama 3.1 / 3.2 / 3.3](/quick-guides/llms/llama-3)
Meta Llama 3 family: 8B on a single RTX 4090, 70B on 2× A100, 405B on 8× H100. Strong instruction following and function calling.
**Best for:** General-purpose chat, instruction following, and function calling.
#### [Qwen3 Dense & MoE](/quick-guides/llms/qwen3)
Alibaba Qwen3 text models with toggleable chain-of-thought reasoning. Dense models from 7B to 32B; MoE models up to 235B-A22B.
**Best for:** Reasoning tasks with controllable chain-of-thought via `/think` and `/no_think` tokens.
#### [Mistral & Mixtral](/quick-guides/llms/mistral-mixtral)
Mistral 7B, Mixtral 8x7B MoE, and Mistral Small 3.1 24B with efficient inference and function calling support.
**Best for:** Efficient inference with strong instruction following and function calling.
#### [Gemma 3](/quick-guides/llms/gemma-3)
Google DeepMind Gemma 3 in 4B, 12B, and 27B (INT4 option). Available under the Gemma Terms of Use; commercial use is permitted after accepting Google's license agreement.
**Best for:** Low-latency inference on smaller GPUs; research and commercial projects.
#### [Phi-4 & Phi-4 Multimodal](/quick-guides/llms/phi-4)
Microsoft Phi-4 14B small language model and Phi-4-multimodal with image input support. MIT license.
**Best for:** Efficient SLM inference; multimodal tasks on a single RTX 4090.
### What's next
* [Inference Frameworks](/quick-guides/llms/frameworks): Choose the right serving stack (vLLM, SGLang, llama.cpp, etc.)
* [Multimodal Models](/quick-guides/llms/multimodal): Vision-language model guides
* [Specialized Models](/quick-guides/llms/specialized-models): OCR, audio generation, and code intelligence
* [Instance Types](/concepts/instance-types): GPU selection for text models
* [Cost Optimization](/cost-optimization): Reducing inference costs with Spot instances
import { YouTube } from '../../../../components/YouTube'
## Baidu ERNIE-4.5-VL-28B-A3B-Thinking
Deploy [Baidu ERNIE-4.5-VL-28B-A3B-Thinking](https://huggingface.co/baidu/ERNIE-4.5-VL-28B-A3B-Thinking) on a Spheron GPU instance. This multimodal reasoning model uses a Mixture-of-Experts architecture with 28B total parameters and 3B active per token. It supports visual reasoning, STEM problem solving, chart analysis, and video understanding under the Apache 2.0 license.
### Overview
ERNIE-4.5-VL-28B-A3B-Thinking includes a "Thinking" mode for multi-step chain-of-thought reasoning over visual inputs. 28B parameters with MoE design (3B active per token). Performance is competitive with GPT-4o and Gemini 2.5 Pro on visual reasoning, STEM, charts, and video understanding tasks.
**Released:** November 11, 2025 by Baidu
**Architecture:** ERNIE-4.5-VL-28B-A3B + reasoning fine-tuning (GSPO, IcePop)
**Training:** Visual-language reasoning datasets with multimodal RL
### Key capabilities
* **Visual reasoning:** Multi-step reasoning, chart analysis, causal relationships
* **STEM reasoning:** Math, science, engineering from images
* **Visual grounding:** Object localization, industrial QC/automation
* **Dynamic detail focus:** Zooms into regions, chain-of-thought over visuals
* **Tool calling:** Image search, cropping, web lookup integration
* **Video understanding:** Temporal awareness, event localization, frame tracking
**Use cases:** Multimodal agents, document automation, visual search, education, video analysis
### Requirements
**Hardware:**
* GPU: A100 80GB (recommended), RTX A6000 48GB (minimum for single-card), or 2× RTX 4090 for tensor parallelism
* RAM: 32GB+
* Storage: 60GB free
* VRAM: 48GB+ per card for bfloat16 (80GB recommended); 20GB+ with 4-bit quantization
**Software:**
* Ubuntu 22.04 LTS
* CUDA 12.1+
* Python 3.11
* Conda/Miniconda
### Deploy on Spheron
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. **Deploy** → Select **A100 80GB** (or 2× RTX 4090 for multi-GPU) → Region → **Ubuntu 22.04** → SSH key → Deploy
**Connect:**
```bash
ssh -i root@
```
New to Spheron? See [Getting Started](/getting-started) and [SSH Setup](/connecting/ssh-connection).
### Installation
#### Install Miniconda
```bash
curl -O https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh -b -p $HOME/miniconda3
$HOME/miniconda3/bin/conda init bash
source ~/.bashrc
```
#### Create Python environment
```bash
conda create -n ernie python=3.11 -y && conda activate ernie
```
#### Install dependencies
```bash
pip install torch torchvision torchaudio einops timm pillow
pip install git+https://github.com/huggingface/transformers
pip install git+https://github.com/huggingface/accelerate
pip install git+https://github.com/huggingface/diffusers
pip install huggingface_hub
pip install sentencepiece bitsandbytes protobuf decord numpy
```
#### Install Jupyter
```bash
conda install -c conda-forge --override-channels notebook -y
conda install -c conda-forge --override-channels ipywidgets -y
jupyter notebook --allow-root
```
#### Access Jupyter from your local machine
SSH port forwarding from your local machine:
```bash
ssh -L 8888:localhost:8888 -p -i root@
```
Copy the Jupyter URL from the server terminal to your browser.
### Run model
#### Load model
Open a notebook and run:
```python
import torch
from transformers import AutoProcessor, AutoTokenizer, AutoModelForCausalLM
model_path = 'baidu/ERNIE-4.5-VL-28B-A3B-Thinking'
model = AutoModelForCausalLM.from_pretrained(
model_path,
device_map="auto",
dtype=torch.bfloat16,
trust_remote_code=True
)
processor = AutoProcessor.from_pretrained(model_path, trust_remote_code=True)
model.add_image_preprocess(processor)
```
#### Run inference
```python
messages = [
{
"role": "user",
"content": [
{
"type": "text",
"text": "What is in the image and what is the color of the dog"
},
{
"type": "image_url",
"image_url": {
"url": "https://images.pexels.com/photos/58997/pexels-photo-58997.jpeg"
}
},
]
},
]
text = processor.tokenizer.apply_chat_template(
messages,
tokenize=False,
add_generation_prompt=True,
)
image_inputs, video_inputs = processor.process_vision_info(messages)
inputs = processor(
text=[text],
images=image_inputs,
videos=video_inputs,
padding=True,
return_tensors="pt",
)
device = next(model.parameters()).device
inputs = inputs.to(device)
generated_ids = model.generate(
inputs=inputs['input_ids'].to(device),
**inputs,
max_new_tokens=1024,
use_cache=False
)
output_text = processor.decode(generated_ids[0][len(inputs['input_ids'][0]):])
print(output_text)
```
### What's next
* [Model on HuggingFace](https://huggingface.co/baidu/ERNIE-4.5-VL-28B-A3B-Thinking)
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [Getting Started](/getting-started): Spheron deployment basics
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Serve multimodal models via an OpenAI-compatible API
## Multimodal Models
Guides for deploying vision-language models (VLMs) on Spheron GPU instances. All models accept both text and image inputs and are served via vLLM's OpenAI-compatible multimodal API.
### VRAM requirements
| Model | Parameters | Min VRAM | Recommended GPU |
| -------------------------- | ---------- | -------- | --------------- |
| Qwen3-VL 4B | 4B | 10GB | RTX 4090 (24GB) |
| Qwen3-VL 8B | 8B | 18GB | RTX 4090 (24GB) |
| LLaVA-NeXT 7B | 7B | 14GB | RTX 4090 (24GB) |
| InternVL3-8B | 8B | 18GB | RTX 4090 (24GB) |
| Pixtral-12B | 12B | 24GB | RTX 4090 (24GB) |
| LLaVA-NeXT 13B | 13B | 28GB | A100 40GB |
| Baidu ERNIE-4.5-VL-28B-A3B | 28B active | 48GB | A100 80GB |
| Qwen3-Omni-30B-A3B | 30B active | 40GB | A100 80GB |
| InternVL3-78B | 78B | 80GB × 2 | 2× A100 80GB |
### Available guides
#### [Qwen3-Omni-30B-A3B](/quick-guides/llms/multimodal/qwen3-omni-30b-a3b)
Multimodal language model with 30B parameters supporting text, audio, images, and video inputs. 32K context window (single GPU).
**Best for:** Multimodal tasks requiring audio, vision, and text processing in a single model.
#### [Qwen3-VL 4B & 8B](/quick-guides/llms/multimodal/qwen3-vl-4b-8b)
Vision-language models in 4B and 8B variants. 256K context, multimodal reasoning, and GUI automation.
**Best for:** Image understanding, visual reasoning, and GUI automation tasks.
#### [InternVL3](/quick-guides/llms/multimodal/internvl3)
InternVL3 series (1B–78B) deployed via vLLM. Strong visual question answering and multimodal reasoning.
**Best for:** High-accuracy visual QA and multimodal reasoning across model scales.
#### [LLaVA-Next](/quick-guides/llms/multimodal/llava-next)
LLaVA-NeXT 7B and 13B with improved visual reasoning, served via vLLM.
**Best for:** Accessible image-to-text inference on RTX 4090 or A100.
#### [Pixtral-12B](/quick-guides/llms/multimodal/pixtral-12b)
Mistral's Pixtral-12B multimodal model on RTX 4090 (24GB) via vLLM.
**Best for:** Compact multimodal inference with Mistral-quality text generation.
#### [Baidu ERNIE-4.5-VL-28B-A3B](/quick-guides/llms/multimodal/baidu-ernie-4-5-vl-28b-a3b)
28B active parameter MoE vision-language model from Baidu. Strong STEM and visual reasoning performance.
**Best for:** Visual reasoning, multimodal understanding, and STEM-domain tasks.
### What's next
* [LLM Inference Overview](/quick-guides/llms): Text model and framework guides
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Serving stack used by most guides here
* [Instance Types](/concepts/instance-types): GPU selection for VLMs
* [Cost Optimization](/cost-optimization): Reducing inference costs with Spot instances
## InternVL3
Deploy [InternVL3](https://huggingface.co/OpenGVLab/InternVL3-8B) on Spheron GPU instances using vLLM. InternVL3 is a vision-language model series from 1B to 78B parameters with strong performance on visual question answering and multimodal reasoning benchmarks.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| ------------- | --------------- | ------------------- | -------------------------- |
| InternVL3-8B | RTX 4090 (24GB) | Dedicated or Spot | Single-GPU |
| InternVL3-14B | A100 40GB | Dedicated | Full precision |
| InternVL3-38B | A100 80GB | Dedicated | Single-GPU |
| InternVL3-78B | 2× A100 80GB | Dedicated / Cluster | `--tensor-parallel-size 2` |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model OpenGVLab/InternVL3-8B \
--port 8000 \
--dtype auto \
--trust-remote-code
```
Press `Ctrl+C` to stop. For InternVL3-78B on 2× A100, add `--tensor-parallel-size 2`.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-internvl.service > /dev/null << 'EOF'
[Unit]
Description=InternVL3 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model OpenGVLab/InternVL3-8B \
--port 8000 \
--dtype auto \
--trust-remote-code
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-internvl
sudo systemctl start vllm-internvl
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: image input
```python
import base64
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
with open("image.jpg", "rb") as f:
image_b64 = base64.b64encode(f.read()).decode()
response = client.chat.completions.create(
model="OpenGVLab/InternVL3-8B",
messages=[
{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_b64}"}},
{"type": "text", "text": "Describe what you see in this image."},
],
}
],
)
print(response.choices[0].message.content)
```
### Check server logs
```bash
journalctl -u vllm-internvl -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-internvl.service << 'EOF'
[Unit]
Description=InternVL3 vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model OpenGVLab/InternVL3-8B \
--port 8000 \
--dtype auto \
--trust-remote-code
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-internvl
- systemctl start vllm-internvl
```
For InternVL3-78B on 2× A100, add `--tensor-parallel-size 2` to the ExecStart command.
### What's next
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Networking](/concepts/networking): SSH tunneling and port access
* [Instance Types](/concepts/instance-types): Multi-GPU setup for large VLMs
## LLaVA-Next
Deploy [LLaVA-NeXT](https://huggingface.co/llava-hf/llava-v1.6-mistral-7b-hf) on Spheron GPU instances using vLLM. LLaVA-NeXT (Large Language and Vision Assistant Next) improves on LLaVA with better visual reasoning, higher image resolution support, and improved OCR capabilities.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| -------------- | --------------- | ----------------- | -------------------------- |
| LLaVA-NeXT 7B | RTX 4090 (24GB) | Dedicated or Spot | `llava-v1.6-mistral-7b-hf` |
| LLaVA-NeXT 13B | A100 40GB | Dedicated | `llava-v1.6-vicuna-13b-hf` |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model llava-hf/llava-v1.6-mistral-7b-hf \
--port 8000 \
--dtype auto
```
Press `Ctrl+C` to stop.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-llava.service > /dev/null << 'EOF'
[Unit]
Description=LLaVA-Next vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model llava-hf/llava-v1.6-mistral-7b-hf \
--port 8000 \
--dtype auto
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-llava
sudo systemctl start vllm-llava
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: image input
```python
import base64
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
with open("image.jpg", "rb") as f:
image_b64 = base64.b64encode(f.read()).decode()
response = client.chat.completions.create(
model="llava-hf/llava-v1.6-mistral-7b-hf",
messages=[
{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_b64}"}},
{"type": "text", "text": "What is shown in this image?"},
],
}
],
)
print(response.choices[0].message.content)
```
### Check server logs
```bash
journalctl -u vllm-llava -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-llava.service << 'EOF'
[Unit]
Description=LLaVA-Next vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model llava-hf/llava-v1.6-mistral-7b-hf \
--port 8000 \
--dtype auto
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-llava
- systemctl start vllm-llava
```
### What's next
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [InternVL3](/quick-guides/llms/multimodal/internvl3): Higher-accuracy VLM alternative
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Networking](/concepts/networking): SSH tunneling and port access
## Pixtral-12B
Deploy [Pixtral-12B](https://huggingface.co/mistralai/Pixtral-12B-2409) on a Spheron RTX 4090 (24GB) instance using vLLM. Pixtral-12B is Mistral AI's multimodal model built on Mistral-NeMo 12B, with a dedicated 400M visual encoder supporting variable-resolution image inputs.
### Recommended hardware
| Model | Recommended GPU | Instance Type | Notes |
| ----------- | --------------- | ----------------- | ----------------- |
| Pixtral-12B | RTX 4090 (24GB) | Dedicated or Spot | Fits in 24GB VRAM |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Pixtral-12B-2409 \
--port 8000 \
--dtype bfloat16 \
--tokenizer-mode mistral \
--config-format mistral \
--load-format mistral
```
Press `Ctrl+C` to stop.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm-pixtral.service > /dev/null << 'EOF'
[Unit]
Description=Pixtral-12B vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Pixtral-12B-2409 \
--port 8000 \
--dtype bfloat16 \
--tokenizer-mode mistral \
--config-format mistral \
--load-format mistral
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm-pixtral
sudo systemctl start vllm-pixtral
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add `--api-key ` to the vLLM startup command.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
### Usage example: image input
```python
import base64
from openai import OpenAI
client = OpenAI(base_url="http://localhost:8000/v1", api_key="not-needed")
with open("image.jpg", "rb") as f:
image_b64 = base64.b64encode(f.read()).decode()
response = client.chat.completions.create(
model="mistralai/Pixtral-12B-2409",
messages=[
{
"role": "user",
"content": [
{"type": "image_url", "image_url": {"url": f"data:image/jpeg;base64,{image_b64}"}},
{"type": "text", "text": "Describe the image in detail."},
],
}
],
)
print(response.choices[0].message.content)
```
### Check server logs
```bash
journalctl -u vllm-pixtral -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install vllm
- |
cat > /etc/systemd/system/vllm-pixtral.service << 'EOF'
[Unit]
Description=Pixtral-12B vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model mistralai/Pixtral-12B-2409 \
--port 8000 \
--dtype bfloat16 \
--tokenizer-mode mistral \
--config-format mistral \
--load-format mistral
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable vllm-pixtral
- systemctl start vllm-pixtral
```
### What's next
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [Mistral & Mixtral](/quick-guides/llms/mistral-mixtral): Mistral text-only model guides
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): vLLM configuration details
* [Networking](/concepts/networking): SSH tunneling and port access
import { YouTube } from '../../../../components/YouTube'
## Qwen3-Omni-30B-A3B
Deploy [Qwen3-Omni-30B-A3B](https://huggingface.co/Qwen/Qwen3-Omni-30B-A3B-Instruct) on a Spheron A100 or H100 instance. This multimodal language model processes text, audio, images, and video with a 32K context window (single GPU). It differs from Qwen3-VL, which handles vision and language only.
### Key capabilities
* **Multimodal inputs:** Text, audio, images, video
* **Audio understanding:** Speech recognition, audio analysis
* **Vision-language:** Image understanding and generation
* **Context window:** 32K tokens (single GPU), up to 65K (multi-GPU)
* **Multilingual:** 119+ languages and dialects
**Use cases:** Audio transcription, multimodal chat, content analysis, accessibility tools
### Requirements
**Hardware:**
* GPU: A100 or H100 (30B model needs significant VRAM)
* VRAM: 24GB+ minimum, 40GB+ recommended
* RAM: 32GB+
* Storage: 60GB (SSD recommended)
**Software:**
* Ubuntu 22.04 LTS
* CUDA 12.1+
* Python 3.11
* Conda/Miniconda
### Deploy on Spheron
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. **Deploy** → **A100** or **H100** → Region → **Ubuntu 22.04** → SSH key → Deploy
**Connect:**
```bash
ssh -i root@
```
New to Spheron? See [Getting Started](/getting-started) and [SSH Setup](/connecting/ssh-connection).
### Installation
#### Install Miniconda
```bash
curl -O https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh -b -p $HOME/miniconda3
$HOME/miniconda3/bin/conda init bash
source ~/.bashrc
```
#### Create environment
```bash
conda create -n qwen python=3.11 -y && conda activate qwen
```
Accept ToS if prompted:
```bash
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/main
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/r
```
#### Install PyTorch (CUDA 12.1)
```bash
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121
```
#### Install dependencies
```bash
pip install git+https://github.com/huggingface/transformers
pip install git+https://github.com/huggingface/accelerate
pip install huggingface_hub
pip install einops timm pillow sentencepiece protobuf decord numpy requests
pip install bitsandbytes
pip install qwen-omni-utils -U
```
### Create test.py
Create the inference script:
```python
from transformers import Qwen3OmniMoeForConditionalGeneration, Qwen3OmniMoeProcessor
# Load the model on available devices
model = Qwen3OmniMoeForConditionalGeneration.from_pretrained(
"Qwen/Qwen3-Omni-30B-A3B-Instruct",
dtype="auto",
device_map="auto"
)
# Optional: Enable flash_attention_2 for better performance and memory efficiency,
# especially in multi-image, video, or audio tasks.
# model = Qwen3OmniMoeForConditionalGeneration.from_pretrained(
# "Qwen/Qwen3-Omni-30B-A3B-Instruct",
# dtype=torch.bfloat16,
# attn_implementation="flash_attention_2",
# device_map="auto",
# )
# Load the processor
processor = Qwen3OmniMoeProcessor.from_pretrained("Qwen/Qwen3-Omni-30B-A3B-Instruct")
# Define input messages (image + text prompt)
messages = [
{
"role": "user",
"content": [
{
"type": "image",
"image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
},
{"type": "text", "text": "Describe this image."},
],
}
]
# Prepare inputs for inference
inputs = processor.apply_chat_template(
messages,
tokenize=True,
add_generation_prompt=True,
return_dict=True,
return_tensors="pt"
).to(model.device)
# Generate model output
generated_ids = model.generate(**inputs, max_new_tokens=128)
# Extract generated tokens (excluding prompt tokens)
generated_ids_trimmed = [
output[len(input_ids):] for input_ids, output in zip(inputs.input_ids, generated_ids)
]
# Decode output text
output_text = processor.batch_decode(
generated_ids_trimmed,
skip_special_tokens=True,
clean_up_tokenization_spaces=False
)
print(output_text)
```
### Run script
```bash
conda activate qwen
python3 test.py
```
### Configuration
**Model variants:**
* For a smaller omni model from the previous generation, use `Qwen/Qwen2.5-Omni-7B`.
**Precision:**
* `dtype=torch.float16` or `torch.bfloat16` (A100/H100)
**Flash Attention:**
* Add `attn_implementation="flash_attention_2"` if supported.
**Device:**
* `device_map="auto"` (default, recommended)
* `device_map={"":0}` (single GPU)
**Local images:**
* Use `load_image_from_path()` instead of a URL.
### Troubleshooting
#### Issue: Out of memory (OOM)
**Symptoms:** CUDA OOM error during model load or inference.
**Resolution:** Reduce `max_new_tokens`, switch to `dtype=torch.float16`, or enable bitsandbytes quantization.
#### Issue: Slow model loading
**Symptoms:** Model takes several minutes to load.
**Resolution:** Cache models locally, use NVMe storage, and enable `use_safetensors=True`.
#### Issue: CUDA errors
**Symptoms:** CUDA version mismatch errors.
**Resolution:** Verify that your PyTorch and CUDA versions match. Run `nvidia-smi` to check the installed CUDA version.
### What's next
* [Qwen3 Models on HuggingFace](https://huggingface.co/Qwen)
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [Getting Started](/getting-started): Spheron deployment basics
* [Instance Types](/concepts/instance-types): GPU selection for large multimodal models
import { YouTube } from '../../../../components/YouTube'
## Qwen3-VL 4B & 8B
Deploy [Qwen3-VL](https://huggingface.co/Qwen/Qwen3-VL-4B-Thinking) on a Spheron GPU instance. These vision-language models process text, images, and video with a 256K native context window (scalable to 1M tokens). Two size variants are available: 4B and 8B, plus an 8B-Thinking variant with enhanced reasoning.
**Training:** 36 trillion tokens, 119 languages/dialects
### Key features
**Architecture:**
* Interleaved-MRoPE: Multi-resolution position embeddings for long video reasoning
* DeepStack: Multi-level ViT feature fusion for fine-grained detail
* Text-Timestamp Alignment: Precise event localization in videos
**Capabilities:**
* Visual agents (GUI automation, OS World, Android Control)
* Visual coding (mockups to HTML/CSS/JS, Draw\.io diagrams)
* Spatial understanding (2D/3D grounding, position/viewpoint)
* OCR (32 languages, robust to low-light/blur/tilt)
**Benchmarks:**
* 8B-Thinking: MathVision 36.8, MMMU 61.7, MathVista 71.3
* 235B: Top scores on agent, document, and spatial reasoning benchmarks
### Requirements
**Hardware:**
* GPU: RTX 4090, A6000, A100, H100
* VRAM: 8GB minimum, 16GB+ recommended
* RAM: 16GB+
* Storage: 10GB+ (SSD recommended)
**Software:**
* Ubuntu 22.04 LTS
* CUDA 12.1+
* Python 3.11
* Conda/Miniconda
FP8-quantized versions reduce VRAM requirements (block size 128).
### Deploy on Spheron
1. Sign up at [app.spheron.ai](https://app.spheron.ai)
2. Add credits (card/stables)
3. **Deploy** → **RTX 4090/A100** → Region → **Ubuntu 22.04** → SSH key → Deploy
**Connect:**
```bash
ssh -i root@
```
New to Spheron? See [Getting Started](/getting-started) and [SSH Setup](/connecting/ssh-connection).
### Installation
#### Install Miniconda
```bash
curl -O https://repo.anaconda.com/miniconda/Miniconda3-latest-Linux-x86_64.sh
bash Miniconda3-latest-Linux-x86_64.sh -b -p $HOME/miniconda3
$HOME/miniconda3/bin/conda init bash
source ~/.bashrc
```
#### Create environment
```bash
conda create -n qwen python=3.11 -y && conda activate qwen
```
Accept ToS if prompted:
```bash
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/main
conda tos accept --override-channels --channel https://repo.anaconda.com/pkgs/r
```
#### Install PyTorch (CUDA 12.1)
```bash
pip install torch torchvision torchaudio --index-url https://download.pytorch.org/whl/cu121
```
#### Install dependencies
```bash
pip install git+https://github.com/huggingface/transformers
pip install git+https://github.com/huggingface/accelerate
pip install huggingface_hub
pip install einops timm pillow sentencepiece protobuf decord numpy requests
pip install bitsandbytes
```
### Create test.py
Create the inference script:
```python
from transformers import Qwen3VLForConditionalGeneration, AutoProcessor
# Load the model on available devices
model = Qwen3VLForConditionalGeneration.from_pretrained(
"Qwen/Qwen3-VL-4B-Thinking",
dtype="auto",
device_map="auto"
)
# Optional: Enable flash_attention_2 for better performance and memory efficiency,
# especially in multi-image or video tasks.
# model = Qwen3VLForConditionalGeneration.from_pretrained(
# "Qwen/Qwen3-VL-4B-Thinking",
# dtype=torch.bfloat16,
# attn_implementation="flash_attention_2",
# device_map="auto",
# )
# Load the processor
processor = AutoProcessor.from_pretrained("Qwen/Qwen3-VL-4B-Thinking")
# Define input messages (image + text prompt)
messages = [
{
"role": "user",
"content": [
{
"type": "image",
"image": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg",
},
{"type": "text", "text": "Describe this image."},
],
}
]
# Prepare inputs for inference
inputs = processor.apply_chat_template(
messages,
tokenize=True,
add_generation_prompt=True,
return_dict=True,
return_tensors="pt"
).to(model.device)
# Generate model output
generated_ids = model.generate(**inputs, max_new_tokens=128)
# Extract generated tokens (excluding prompt tokens)
generated_ids_trimmed = [
output[len(input_ids):] for input_ids, output in zip(inputs.input_ids, generated_ids)
]
# Decode output text
output_text = processor.batch_decode(
generated_ids_trimmed,
skip_special_tokens=True,
clean_up_tokenization_spaces=False
)
print(output_text)
```
### Run script
```bash
conda activate qwen
python3 test.py
```
### Configuration
**Model variants:**
* 4B: `Qwen/Qwen3-VL-4B-Thinking`
* 8B: `Qwen/Qwen3-VL-8B-Thinking` (requires more VRAM)
**Precision:**
* `dtype=torch.float16` or `torch.bfloat16` (A100/H100)
**Flash Attention:**
* Add `attn_implementation="flash_attention_2"` if supported.
**Device:**
* `device_map="auto"` (recommended)
* `device_map={"":0}` (single GPU)
### Troubleshooting
#### Issue: Out of memory (OOM)
**Symptoms:** CUDA OOM error during model load or inference.
**Resolution:** Reduce `max_new_tokens`, switch to `dtype=torch.float16`, or enable bitsandbytes quantization.
#### Issue: Slow model loading
**Symptoms:** Model takes several minutes to load.
**Resolution:** Cache models locally, use NVMe storage, and enable `use_safetensors=True`.
#### Issue: CUDA errors
**Symptoms:** CUDA version mismatch errors.
**Resolution:** Verify that your PyTorch and CUDA versions match. Run `nvidia-smi` to check the installed CUDA version.
### What's next
* [Qwen3-VL on HuggingFace](https://huggingface.co/Qwen/Qwen3-VL-4B-Thinking)
* [Multimodal Models](/quick-guides/llms/multimodal): Other vision-language model guides
* [Getting Started](/getting-started): Spheron deployment basics
* [Instance Types](/concepts/instance-types): GPU selection for vision-language models
## Inference Frameworks
Choose the right LLM serving stack for your workload. All frameworks listed here expose an OpenAI-compatible `/v1` API unless otherwise noted.
### Framework comparison
| Framework | Interface | Best For | Key Differentiator |
| --------------------- | ---------------- | ------------------------------------ | ------------------------------------- |
| vLLM | OpenAI REST | Production API, high throughput | PagedAttention; most widely used |
| SGLang | OpenAI REST | Agentic pipelines, structured output | RadixAttention; constrained decoding |
| TensorRT-LLM + Triton | Triton HTTP/gRPC | Maximum NVIDIA throughput | Engine compilation; NVIDIA-optimized |
| llama.cpp | OpenAI REST | Quantized models, CPU+GPU offload | GGUF format; runs on 8GB cards |
| LMDeploy | OpenAI REST | AWQ-quantized models | TurboMind engine; memory-efficient |
| LocalAI | OpenAI REST | Multi-modal drop-in replacement | Docker; LLMs + Whisper + SD |
| Ollama | OpenAI REST | Interactive local usage | Browser WebUI; one-command model pull |
### Available guides
#### [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server)
OpenAI-compatible inference server using vLLM on H100 or A100. Includes systemd service, SSH tunnel access, and performance tuning flags (`--tensor-parallel-size`, `--dtype`, `--max-model-len`).
**Best for:** Production API workloads; drop-in replacement for the OpenAI API.
#### [Ollama + Open WebUI](/quick-guides/llms/frameworks/ollama)
Browser-based chat interface backed by Ollama on an RTX 4090. Docker Compose setup with NVIDIA GPU passthrough; pull any model with a single command.
**Best for:** Interactive local model usage; exploring models without writing code.
#### [SGLang](/quick-guides/llms/frameworks/sglang)
Agentic LLM serving with RadixAttention for KV cache reuse across requests, constrained decoding for JSON output, and torch.compile support.
**Best for:** Agentic pipelines, multi-turn workloads, and structured output generation.
#### [TensorRT-LLM + Triton](/quick-guides/llms/frameworks/tensorrt-llm)
NVIDIA-optimized engine compilation via TensorRT-LLM with Triton Inference Server for production-grade serving. Requires an engine-build step before inference.
**Best for:** Maximum throughput on NVIDIA GPUs; latency-critical production deployments.
#### [llama.cpp Server](/quick-guides/llms/frameworks/llama-cpp)
GGUF model serving with CPU+GPU offload. Supports Q4, Q8, and F16 quantizations. Runs on GPUs as small as 8GB VRAM.
**Best for:** Running quantized models on consumer GPUs; mixed CPU/GPU inference; minimal dependencies.
#### [LMDeploy](/quick-guides/llms/frameworks/lmdeploy)
LMDeploy TurboMind inference toolkit with AWQ quantization support and OpenAI-compatible API.
**Best for:** Memory-efficient deployment of AWQ-quantized models on A100/H100.
#### [LocalAI](/quick-guides/llms/frameworks/localai)
OpenAI-compatible drop-in replacement via Docker with support for LLMs, Whisper speech-to-text, and Stable Diffusion image generation.
**Best for:** Multi-modal local inference with a single OpenAI-compatible endpoint; replacing OpenAI calls without code changes.
### What's next
* [LLM Inference Overview](/quick-guides/llms): Model guides and hardware recommendations
* [Instance Types](/concepts/instance-types): Spot vs Dedicated vs Cluster
* [Networking](/concepts/networking): SSH tunneling and port access
* [Cost Optimization](/cost-optimization): Reducing inference costs with Spot instances
## llama.cpp Server
Deploy [llama.cpp](https://github.com/ggerganov/llama.cpp) as an OpenAI-compatible HTTP server on Spheron GPU instances. llama.cpp supports GGUF-quantized models and can offload layers between CPU and GPU, making it ideal for consumer-grade GPUs and quantized inference.
### Recommended hardware
| Model Size | Quantization | VRAM Required | Recommended GPU |
| ---------- | ------------ | ------------- | ----------------------- |
| 7B | Q4\_K\_M | \~4GB | RTX 4090 or any 8GB GPU |
| 7B | Q8\_0 | \~8GB | RTX 4090 |
| 7B | F16 | \~14GB | RTX 4090 (24GB) |
| 13B | Q4\_K\_M | \~8GB | RTX 4090 |
| 30B | Q4\_K\_M | \~20GB | RTX 4090 (24GB, tight) |
| 70B | Q4\_K\_M | \~40GB | A100 80GB |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with your instance username (e.g., `root` or `ubuntu`) and `` with your instance's public IP.
#### Step 2: Install dependencies
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip cmake build-essential
pip install "llama-cpp-python[server]" --extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cu121
```
#### Step 3: Download a GGUF model
```bash
mkdir -p /opt/llama-models
# Example: download a GGUF model using huggingface-cli
pip install huggingface_hub
huggingface-cli download TheBloke/Llama-2-7B-Chat-GGUF llama-2-7b-chat.Q4_K_M.gguf \
--local-dir /opt/llama-models
```
Or copy your own GGUF file to `/opt/llama-models/model.gguf`.
#### Step 4: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m llama_cpp.server \
--model /opt/llama-models/model.gguf \
--n_gpu_layers -1 \
--port 8080
```
Press `Ctrl+C` to stop.
#### Step 5: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/llama-cpp.service > /dev/null << 'EOF'
[Unit]
Description=llama.cpp Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m llama_cpp.server \
--model /opt/llama-models/model.gguf \
--n_gpu_layers -1 \
--port 8080
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable llama-cpp
sudo systemctl start llama-cpp
```
Replace `/opt/llama-models/model.gguf` with your downloaded GGUF file path. Set `--n_gpu_layers -1` to offload all layers to GPU; reduce this number for CPU+GPU mixed inference.
### Accessing the server
:::warning[Port 8080 is publicly accessible by default]
Use SSH tunneling during development to keep the endpoint private.
:::
#### SSH tunnel
```bash
ssh -L 8080:localhost:8080 @
```
#### Test completion
```bash
curl http://localhost:8080/v1/completions \
-H "Content-Type: application/json" \
-d '{
"prompt": "Explain GGUF quantization briefly.",
"max_tokens": 100
}'
```
### Usage example
```python
from openai import OpenAI
client = OpenAI(
base_url="http://localhost:8080/v1",
api_key="not-needed",
)
response = client.chat.completions.create(
model="model",
messages=[{"role": "user", "content": "What is GGUF quantization?"}],
)
print(response.choices[0].message.content)
```
### GPU layer offload
| `--n_gpu_layers` | Behavior |
| ---------------- | ----------------------------------- |
| `-1` | All layers on GPU (fastest) |
| `0` | CPU only (no GPU) |
| `20` | First 20 layers on GPU, rest on CPU |
Use partial offload when VRAM is insufficient for the full model.
### Check server logs
```bash
journalctl -u llama-cpp -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip cmake build-essential
- pip install "llama-cpp-python[server]" --extra-index-url https://abetlen.github.io/llama-cpp-python/whl/cu121
- pip install huggingface_hub
- mkdir -p /opt/llama-models
- huggingface-cli download TheBloke/Llama-2-7B-Chat-GGUF llama-2-7b-chat.Q4_K_M.gguf --local-dir /opt/llama-models
- mv /opt/llama-models/llama-2-7b-chat.Q4_K_M.gguf /opt/llama-models/model.gguf
- |
cat > /etc/systemd/system/llama-cpp.service << 'EOF'
[Unit]
Description=llama.cpp Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m llama_cpp.server \
--model /opt/llama-models/model.gguf \
--n_gpu_layers -1 \
--port 8080
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable llama-cpp
- systemctl start llama-cpp
```
The script downloads `llama-2-7b-chat.Q4_K_M.gguf` (\~4GB) as `model.gguf` before starting the service. To use a different model, replace the `huggingface-cli download` and `mv` lines with your preferred model download, ensuring the final file is saved to `/opt/llama-models/model.gguf`.
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Higher throughput for production workloads
* [Inference Frameworks](/quick-guides/llms/frameworks): Compare all serving stacks
* [Networking](/concepts/networking): SSH tunneling and port access
* [Instance Types](/concepts/instance-types): Choosing the right GPU for your model
## LMDeploy
Deploy [LMDeploy](https://github.com/InternLM/lmdeploy) with the TurboMind inference engine on Spheron A100 or H100 instances. LMDeploy supports AWQ quantization for memory-efficient inference and exposes an OpenAI-compatible API.
### Recommended hardware
| Model Size | Recommended GPU | Instance Type | Notes |
| ---------- | ---------------------- | ----------------- | ----------------------------------- |
| 7B (AWQ) | RTX 4090 (24GB) | Dedicated or Spot | \~8GB VRAM with W4A16 AWQ |
| 7B (FP16) | A100 40GB | Dedicated | Full precision |
| 30B+ | A100 80GB (1–2×) | Dedicated | Use `--tp 2` for tensor parallelism |
| 70B+ | H100 80GB (2× or more) | Cluster | TurboMind multi-GPU |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install LMDeploy
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install lmdeploy
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m lmdeploy serve api_server \
Qwen/Qwen2.5-7B-Instruct \
--server-port 23333 \
--backend turbomind
```
Press `Ctrl+C` to stop. Replace `Qwen/Qwen2.5-7B-Instruct` with your target model.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/lmdeploy.service > /dev/null << 'EOF'
[Unit]
Description=LMDeploy Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m lmdeploy serve api_server \
Qwen/Qwen2.5-7B-Instruct \
--server-port 23333 \
--backend turbomind
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable lmdeploy
sudo systemctl start lmdeploy
```
### AWQ quantization
To convert a model to AWQ 4-bit before serving (reduces VRAM by \~50%):
```bash
lmdeploy lite auto_awq \
Qwen/Qwen2.5-7B-Instruct \
--calib-dataset ptb \
--calib-samples 128 \
--work-dir ./qwen-7b-awq
```
Then serve the quantized model:
```bash
lmdeploy serve api_server ./qwen-7b-awq \
--server-port 23333 \
--backend turbomind
```
### Accessing the server
:::warning[Port 23333 is publicly accessible by default]
Use SSH tunneling during development to keep the endpoint private.
:::
#### SSH tunnel
```bash
ssh -L 23333:localhost:23333 @
```
### Usage example
```python
from openai import OpenAI
client = OpenAI(
base_url="http://localhost:23333/v1",
api_key="not-needed",
)
response = client.chat.completions.create(
model="Qwen/Qwen2.5-7B-Instruct",
messages=[{"role": "user", "content": "What is AWQ quantization?"}],
)
print(response.choices[0].message.content)
```
### Performance flags
| Flag | Description |
| ------------------------- | --------------------------------------- |
| `--backend turbomind` | Use TurboMind engine (default, fastest) |
| `--tp` | Tensor parallel degree |
| `--cache-max-entry-count` | KV cache size fraction |
### Check server logs
```bash
journalctl -u lmdeploy -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install lmdeploy
- |
cat > /etc/systemd/system/lmdeploy.service << 'EOF'
[Unit]
Description=LMDeploy Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m lmdeploy serve api_server \
Qwen/Qwen2.5-7B-Instruct \
--server-port 23333 \
--backend turbomind
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable lmdeploy
- systemctl start lmdeploy
```
Replace `Qwen/Qwen2.5-7B-Instruct` with your target model.
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Wider model compatibility
* [Inference Frameworks](/quick-guides/llms/frameworks): Compare all serving stacks
* [Networking](/concepts/networking): SSH tunneling and port access
* [Instance Types](/concepts/instance-types): A100 vs H100 for inference workloads
## LocalAI
Deploy [LocalAI](https://github.com/mudler/LocalAI) on a Spheron GPU instance. LocalAI is an OpenAI-compatible drop-in replacement that supports LLMs, Whisper speech-to-text, and Stable Diffusion image generation through a single Docker container with NVIDIA GPU passthrough.
### Recommended hardware
| Workload | Recommended GPU | Instance Type | Notes |
| ---------------------- | --------------- | ----------------- | ---------------------------- |
| LLM inference (7B Q4) | RTX 4090 (24GB) | Dedicated or Spot | \~4GB VRAM |
| LLM + image generation | A100 40GB | Dedicated | Separate VRAM budgets |
| Whisper only | Any GPU | Spot | CPU-capable, GPU accelerated |
### Supported model types
| Type | Example Models | Notes |
| ---------------- | -------------------------- | -------------------------------- |
| LLMs (GGUF) | Llama, Mistral, Qwen | Download GGUF files to `/models` |
| Speech-to-text | Whisper base/small/large | Auto-downloaded |
| Image generation | Stable Diffusion 1.5, SDXL | Requires 8–16GB VRAM |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install Docker and NVIDIA container toolkit
```bash
sudo apt-get update -y
sudo apt-get install -y docker.io nvidia-container-toolkit
sudo nvidia-ctk runtime configure --runtime=docker
sudo systemctl restart docker
```
#### Step 3: Create the models directory
```bash
sudo mkdir -p /opt/localai/models
```
Place GGUF model files in `/opt/localai/models/` before or after startup. LocalAI auto-discovers any `.gguf` file placed in the models directory.
#### Step 4: Start the LocalAI container
```bash
docker run -d \
--gpus all \
--name localai \
-p 8080:8080 \
-v /opt/localai/models:/models \
-e DEBUG=true \
quay.io/go-skynet/local-ai:latest-gpu-nvidia-cuda-12
```
Verify it is running:
```bash
docker ps
docker logs -f localai
```
### Accessing the server
:::warning[Port 8080 is publicly accessible by default]
Use SSH tunneling during development or add an authentication proxy.
:::
#### SSH tunnel
```bash
ssh -L 8080:localhost:8080 @
```
#### List available models
```bash
curl http://localhost:8080/v1/models
```
### Usage example
```python
from openai import OpenAI
client = OpenAI(
base_url="http://localhost:8080/v1",
api_key="not-needed",
)
response = client.chat.completions.create(
model="my-model.gguf", # filename of the GGUF file in /models
messages=[{"role": "user", "content": "Hello from LocalAI!"}],
)
print(response.choices[0].message.content)
```
### Check container logs
```bash
docker logs -f localai
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y docker.io nvidia-container-toolkit
- nvidia-ctk runtime configure --runtime=docker
- systemctl restart docker
- mkdir -p /opt/localai/models
- |
docker run -d \
--gpus all \
--name localai \
-p 8080:8080 \
-v /opt/localai/models:/models \
-e DEBUG=true \
quay.io/go-skynet/local-ai:latest-gpu-nvidia-cuda-12
```
Place GGUF model files in `/opt/localai/models/` before or after startup.
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Higher throughput for production API workloads
* [Inference Frameworks](/quick-guides/llms/frameworks): Compare all serving stacks
* [Networking](/concepts/networking): SSH tunneling and port access
* [Templates & Images](/templates): Additional startup script templates
## Ollama + Open WebUI
Run [Ollama](https://ollama.com) with [Open WebUI](https://github.com/open-webui/open-webui) on an RTX 4090 Spheron instance. Open WebUI provides a browser-based chat interface backed by any model Ollama can load into VRAM.
### Recommended hardware
**GPU:** RTX 4090 (24GB VRAM)
**Instance Type:** Dedicated or Spot
**OS:** Ubuntu 22.04 LTS
The RTX 4090 supports:
* Models up to \~13B parameters at Q4 quantization
* Models up to \~7B parameters in full precision (FP16)
For larger models (30B+), use an A100 or H100 instead.
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install Docker
```bash
sudo apt-get update -y
sudo apt-get install -y ca-certificates curl gnupg
sudo install -m 0755 -d /etc/apt/keyrings
curl -fsSL https://download.docker.com/linux/ubuntu/gpg | sudo gpg --dearmor -o /etc/apt/keyrings/docker.gpg
sudo chmod a+r /etc/apt/keyrings/docker.gpg
echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://download.docker.com/linux/ubuntu $(. /etc/os-release && echo $VERSION_CODENAME) stable" | sudo tee /etc/apt/sources.list.d/docker.list > /dev/null
sudo apt-get update -y
sudo apt-get install -y docker-ce docker-ce-cli containerd.io docker-compose-plugin
```
#### Step 3: Install NVIDIA container toolkit
```bash
curl -fsSL https://nvidia.github.io/libnvidia-container/gpgkey | sudo gpg --dearmor -o /usr/share/keyrings/nvidia-container-toolkit-keyring.gpg
curl -s -L https://nvidia.github.io/libnvidia-container/stable/deb/nvidia-container-toolkit.list | sed 's#deb https://#deb [signed-by=/usr/share/keyrings/nvidia-container-toolkit-keyring.gpg] https://#g' | sudo tee /etc/apt/sources.list.d/nvidia-container-toolkit.list
sudo apt-get update -y
sudo apt-get install -y nvidia-container-toolkit
sudo nvidia-ctk runtime configure --runtime=docker
sudo systemctl restart docker
```
#### Step 4: Create Docker Compose file
```bash
mkdir -p /opt/ollama
cat > /opt/ollama/docker-compose.yml << 'EOF'
services:
ollama:
image: ollama/ollama:latest
container_name: ollama
runtime: nvidia
environment:
- NVIDIA_VISIBLE_DEVICES=all
volumes:
- ollama_data:/root/.ollama
ports:
- "11434:11434"
restart: unless-stopped
open-webui:
image: ghcr.io/open-webui/open-webui:main
container_name: open-webui
ports:
- "3000:8080"
environment:
- OLLAMA_BASE_URL=http://ollama:11434
volumes:
- webui_data:/app/backend/data
depends_on:
- ollama
restart: unless-stopped
volumes:
ollama_data:
webui_data:
EOF
```
#### Step 5: Start the services
```bash
docker compose -f /opt/ollama/docker-compose.yml up -d
```
Verify both containers are running:
```bash
docker compose -f /opt/ollama/docker-compose.yml ps
```
### Access the web UI
:::warning[Port 3000 is publicly accessible by default; enable authentication]
All ports on your instance are open by default via its dedicated public IP. Open WebUI on port 3000 is reachable from the public internet. Enable authentication in Open WebUI settings before sharing the URL with others, or use SSH tunneling for development to keep it private.
:::
#### SSH tunnel (recommended)
```bash
ssh -L 3000:localhost:3000 @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances). Then open [http://localhost:3000](http://localhost:3000) in your browser. On first launch, create an admin account.
### Pull and use models
#### Pull a model
```bash
docker exec -it ollama ollama pull llama3.2
```
Popular models for RTX 4090:
```bash
docker exec -it ollama ollama pull llama3.2 # 3B, fast
docker exec -it ollama ollama pull llama3.1:8b # 8B, good balance
docker exec -it ollama ollama pull mistral:7b # 7B, good quality
docker exec -it ollama ollama pull codellama:13b # 13B coding model
```
#### CLI usage
```bash
docker exec -it ollama ollama run llama3.2
```
#### API usage
Ollama exposes an OpenAI-compatible API on port 11434. It is published to the host, so you can tunnel it the same way:
```bash
ssh -L 11434:localhost:11434 @
```
Then query it:
```bash
curl http://localhost:11434/api/generate \
-d '{
"model": "llama3.2",
"prompt": "Why is the sky blue?",
"stream": false
}'
```
### Memory guidelines for RTX 4090 (24GB VRAM)
| Model | Quantization | VRAM | Fits on 4090? |
| ----- | ------------ | ------ | ----------------- |
| 7B | FP16 | \~14GB | Yes |
| 7B | Q4 | \~4GB | Yes |
| 13B | Q4 | \~8GB | Yes |
| 30B | Q4 | \~20GB | Yes (tight) |
| 70B | Q4 | \~40GB | No; use A100/H100 |
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying. It installs Docker with the NVIDIA Container Toolkit, writes a `docker-compose.yml`, and starts both services.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y ca-certificates curl gnupg
- install -m 0755 -d /etc/apt/keyrings
- curl -fsSL https://download.docker.com/linux/ubuntu/gpg | gpg --dearmor -o /etc/apt/keyrings/docker.gpg
- chmod a+r /etc/apt/keyrings/docker.gpg
- echo "deb [arch=$(dpkg --print-architecture) signed-by=/etc/apt/keyrings/docker.gpg] https://download.docker.com/linux/ubuntu $(. /etc/os-release && echo $VERSION_CODENAME) stable" > /etc/apt/sources.list.d/docker.list
- apt-get update -y
- apt-get install -y docker-ce docker-ce-cli containerd.io docker-compose-plugin
- curl -fsSL https://nvidia.github.io/libnvidia-container/gpgkey | gpg --dearmor -o /usr/share/keyrings/nvidia-container-toolkit-keyring.gpg
- curl -s -L https://nvidia.github.io/libnvidia-container/stable/deb/nvidia-container-toolkit.list | sed 's#deb https://#deb [signed-by=/usr/share/keyrings/nvidia-container-toolkit-keyring.gpg] https://#g' > /etc/apt/sources.list.d/nvidia-container-toolkit.list
- apt-get update -y
- apt-get install -y nvidia-container-toolkit
- nvidia-ctk runtime configure --runtime=docker
- systemctl restart docker
- mkdir -p /opt/ollama
- |
cat > /opt/ollama/docker-compose.yml << 'EOF'
services:
ollama:
image: ollama/ollama:latest
container_name: ollama
runtime: nvidia
environment:
- NVIDIA_VISIBLE_DEVICES=all
volumes:
- ollama_data:/root/.ollama
ports:
- "11434:11434"
restart: unless-stopped
open-webui:
image: ghcr.io/open-webui/open-webui:main
container_name: open-webui
ports:
- "3000:8080"
environment:
- OLLAMA_BASE_URL=http://ollama:11434
volumes:
- webui_data:/app/backend/data
depends_on:
- ollama
restart: unless-stopped
volumes:
ollama_data:
webui_data:
EOF
- chmod 644 /opt/ollama/docker-compose.yml
- docker compose -f /opt/ollama/docker-compose.yml up -d
```
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): OpenAI-compatible API for production workloads
* [Templates & Images](/templates): Additional startup script templates
* [Networking](/concepts/networking): SSH tunneling and port access
* [Instance Types](/concepts/instance-types): Choosing the right GPU for your model
## SGLang Inference Server
Deploy an [SGLang](https://github.com/sgl-project/sglang) OpenAI-compatible inference server on Spheron GPU instances. SGLang features RadixAttention for KV cache reuse across requests and native support for constrained decoding and structured output.
### Recommended hardware
| Model Size | Recommended GPU | Instance Type | Notes |
| ---------- | ---------------------- | ------------------- | --------------------------------- |
| 7B–13B | RTX 4090 (24GB) | Dedicated or Spot | Single-GPU, fast iteration |
| 30B–70B | A100 80GB (1×) | Dedicated | Full-precision or AWQ |
| 70B+ | H100 80GB (2× or more) | Dedicated / Cluster | Use `--tp` for tensor parallelism |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install SGLang
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install "sglang[all]"
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m sglang.launch_server \
--model-path meta-llama/Llama-3.1-8B-Instruct \
--port 30000 \
--tp 1
```
Press `Ctrl+C` to stop. Replace `meta-llama/Llama-3.1-8B-Instruct` with your target model and adjust `--tp` to match the number of GPUs.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/sglang.service > /dev/null << 'EOF'
[Unit]
Description=SGLang Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m sglang.launch_server \
--model-path meta-llama/Llama-3.1-8B-Instruct \
--port 30000 \
--tp 1
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable sglang
sudo systemctl start sglang
```
### Accessing the server
:::warning[Port 30000 is publicly accessible by default; add authentication]
All ports on your instance are open by default. Use SSH tunneling during development to keep the endpoint private, or add `--api-key ` to the launch command.
:::
#### SSH tunnel (recommended)
```bash
ssh -L 30000:localhost:30000 @
```
#### List available models
```bash
curl http://localhost:30000/v1/models
```
### Usage example
```python
from openai import OpenAI
client = OpenAI(
base_url="http://localhost:30000/v1",
api_key="not-needed",
)
response = client.chat.completions.create(
model="meta-llama/Llama-3.1-8B-Instruct",
messages=[{"role": "user", "content": "Explain RadixAttention briefly."}],
)
print(response.choices[0].message.content)
```
### Performance flags
| Flag | Description | Recommended Value |
| ------------------------ | ----------------------------------- | -------------------------------- |
| `--tp` | Tensor parallel degree | Match GPU count |
| `--chunked-prefill-size` | Chunked prefill token budget | `512` or `1024` |
| `--enable-torch-compile` | torch.compile for kernel fusion | Slower startup, faster inference |
| `--mem-fraction-static` | Fraction of GPU memory for KV cache | `0.85` |
### Check server logs
```bash
journalctl -u sglang -f
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying to automate the setup above.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y python3-pip
- pip install "sglang[all]"
- |
cat > /etc/systemd/system/sglang.service << 'EOF'
[Unit]
Description=SGLang Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m sglang.launch_server \
--model-path meta-llama/Llama-3.1-8B-Instruct \
--port 30000 \
--tp 1
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
- systemctl daemon-reload
- systemctl enable sglang
- systemctl start sglang
```
Replace `meta-llama/Llama-3.1-8B-Instruct` with your target model and adjust `--tp` to match the number of GPUs.
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Alternative for production API workloads
* [Inference Frameworks](/quick-guides/llms/frameworks): Compare all serving stacks
* [Networking](/concepts/networking): SSH tunneling and port access
* [Cost Optimization](/cost-optimization): GPU tier selection for inference workloads
## TensorRT-LLM + Triton Inference Server
Deploy [TensorRT-LLM](https://github.com/NVIDIA/TensorRT-LLM) with [Triton Inference Server](https://github.com/triton-inference-server/server) on Spheron H100 instances for maximum NVIDIA GPU throughput. TensorRT-LLM compiles model weights into an optimized engine before inference, yielding best-in-class token generation rates.
### Recommended hardware
| Model Size | Recommended GPU | Instance Type | Notes |
| ---------- | -------------------- | ------------- | -------------------------------------- |
| 7B–13B | H100 80GB (1×) | Dedicated | FP8 precision, highest throughput |
| 30B–70B | H100 80GB (2× or 4×) | Cluster | Multi-GPU engine with `--tp_size` |
| 70B+ | H100 NVLink (8×) | Cluster | Requires NVLink for tensor parallelism |
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install dependencies
```bash
sudo apt-get update -y
sudo apt-get install -y docker.io nvidia-container-toolkit git python3-pip
sudo nvidia-ctk runtime configure --runtime=docker
sudo systemctl restart docker
```
#### Step 3: Pull the TensorRT-LLM Docker image
```bash
docker pull nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3
```
#### Step 4: Prepare directories and download model
```bash
sudo mkdir -p /opt/trtllm/engines /opt/trtllm/model_repo /opt/trtllm/hf_model
pip install huggingface_hub
# Store the token in a file readable only by root
sudo mkdir -p /etc/trtllm
sudo install -m 600 /dev/null /etc/trtllm/hf-token
echo "HF_TOKEN=" | sudo tee /etc/trtllm/hf-token > /dev/null
# Load and use the token without exposing it in the process list or shell history
. /etc/trtllm/hf-token
huggingface-cli download meta-llama/Meta-Llama-3.1-8B-Instruct \
--local-dir /opt/trtllm/hf_model
```
Replace `` with your HuggingFace token. The token is stored in `/etc/trtllm/hf-token` (mode 600) and loaded via `. /etc/trtllm/hf-token` so it never appears inline on the command line.
#### Step 5: Build the TensorRT engine
:::info[Engine Build Time]
Engine compilation can take 15–60 minutes depending on model size. The compiled engine is cached on disk and reused on restart.
:::
```bash
docker run --rm --gpus all \
-v /opt/trtllm:/workspace \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
bash -c "
pip install tensorrt_llm -U && \
python3 -m tensorrt_llm.commands.build \
--model_dir /workspace/hf_model \
--output_dir /workspace/engines/llama-8b \
--dtype float16 \
--tp_size 1
"
```
#### Step 6: Configure Triton model repository
```bash
git clone --depth 1 https://github.com/triton-inference-server/tensorrtllm_backend.git /opt/trtllm/tensorrtllm_backend
cp -r /opt/trtllm/tensorrtllm_backend/all_models/inflight_batcher_llm/* /opt/trtllm/model_repo/
docker run --rm \
-v /opt/trtllm:/workspace \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
bash -c "
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/tensorrt_llm/config.pbtxt \
'decoupled_mode:false,engine_dir:/engines/llama-8b,max_tokens_in_paged_kv_cache:2560,max_attention_window_size:2560,kv_cache_free_gpu_mem_fraction:0.5,exclude_input_in_output:true,enable_kv_cache_reuse:false,batching_strategy:inflight_fused_batching,max_beam_width:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/preprocessing/config.pbtxt \
'tokenizer_dir:/hf_model,tokenizer_type:auto,triton_max_batch_size:64,preprocessing_instance_count:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/postprocessing/config.pbtxt \
'tokenizer_dir:/hf_model,tokenizer_type:auto,triton_max_batch_size:64,postprocessing_instance_count:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/ensemble/config.pbtxt \
'triton_max_batch_size:64' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/tensorrt_llm_bls/config.pbtxt \
'triton_max_batch_size:64,decoupled_mode:false,bls_instance_count:1,accumulate_tokens:false'
"
```
#### Step 7: Start Triton server
```bash
docker run -d --gpus all \
-p 8000:8000 -p 8001:8001 -p 8002:8002 \
-v /opt/trtllm/model_repo:/opt/tritonserver/model_repo \
-v /opt/trtllm/engines:/engines \
-v /opt/trtllm/hf_model:/hf_model \
--name triton \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
tritonserver --model-repository=/opt/tritonserver/model_repo
```
Monitor startup:
```bash
docker logs -f triton
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default]
Use SSH tunneling during development or add an authentication proxy in front of Triton.
:::
#### SSH tunnel
```bash
ssh -L 8000:localhost:8000 @
```
#### Health check
```bash
curl http://localhost:8000/v2/health/ready
```
### Usage example
```python
import requests
response = requests.post(
"http://localhost:8000/v2/models/ensemble/generate",
json={
"text_input": "Explain GPU tensor parallelism.",
"max_tokens": 200,
"bad_words": "",
"stop_words": "",
},
)
response.raise_for_status()
print(response.json()["text_output"])
```
### Engine build flags
| Flag | Description |
| ------------------ | ------------------------------------------------- |
| `--dtype` | Weight precision: `float16`, `bfloat16`, `float8` |
| `--tp_size` | Tensor parallel degree (match GPU count) |
| `--max_batch_size` | Maximum concurrent requests |
| `--max_input_len` | Maximum input sequence length |
### Check container logs
```bash
docker logs -f triton
```
### Cloud-init startup script (optional)
If your provider supports cloud-init, you can paste this into the **Startup Script** field when deploying. This script pulls the NVIDIA Triton + TensorRT-LLM Docker image, builds an engine for Llama-3-8B in FP16, configures the Triton model repository from the official `tensorrtllm_backend` templates, and starts the Triton HTTP server on port 8000.
```yaml
#cloud-config
runcmd:
- apt-get update -y
- apt-get install -y docker.io nvidia-container-toolkit git python3-pip
- nvidia-ctk runtime configure --runtime=docker
- systemctl restart docker
- docker pull nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3
- mkdir -p /opt/trtllm/engines /opt/trtllm/model_repo /opt/trtllm/hf_model /etc/trtllm
- pip install huggingface_hub
- install -m 600 /dev/null /etc/trtllm/hf-token
- echo "HF_TOKEN=" > /etc/trtllm/hf-token
- sh -c '. /etc/trtllm/hf-token && huggingface-cli download meta-llama/Meta-Llama-3.1-8B-Instruct --local-dir /opt/trtllm/hf_model'
- |
docker run --rm --gpus all \
-v /opt/trtllm:/workspace \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
bash -c "
pip install tensorrt_llm -U && \
python3 -m tensorrt_llm.commands.build \
--model_dir /workspace/hf_model \
--output_dir /workspace/engines/llama-8b \
--dtype float16 \
--tp_size 1
"
- git clone --depth 1 https://github.com/triton-inference-server/tensorrtllm_backend.git /opt/trtllm/tensorrtllm_backend
- cp -r /opt/trtllm/tensorrtllm_backend/all_models/inflight_batcher_llm/* /opt/trtllm/model_repo/
- |
docker run --rm \
-v /opt/trtllm:/workspace \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
bash -c "
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/tensorrt_llm/config.pbtxt \
'decoupled_mode:false,engine_dir:/engines/llama-8b,max_tokens_in_paged_kv_cache:2560,max_attention_window_size:2560,kv_cache_free_gpu_mem_fraction:0.5,exclude_input_in_output:true,enable_kv_cache_reuse:false,batching_strategy:inflight_fused_batching,max_beam_width:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/preprocessing/config.pbtxt \
'tokenizer_dir:/hf_model,tokenizer_type:auto,triton_max_batch_size:64,preprocessing_instance_count:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/postprocessing/config.pbtxt \
'tokenizer_dir:/hf_model,tokenizer_type:auto,triton_max_batch_size:64,postprocessing_instance_count:1' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/ensemble/config.pbtxt \
'triton_max_batch_size:64' && \
python3 /workspace/tensorrtllm_backend/tools/fill_template.py \
--in_place \
/workspace/model_repo/tensorrt_llm_bls/config.pbtxt \
'triton_max_batch_size:64,decoupled_mode:false,bls_instance_count:1,accumulate_tokens:false'
"
- |
docker run -d --gpus all \
-p 8000:8000 -p 8001:8001 -p 8002:8002 \
-v /opt/trtllm/model_repo:/opt/tritonserver/model_repo \
-v /opt/trtllm/engines:/engines \
-v /opt/trtllm/hf_model:/hf_model \
--name triton \
nvcr.io/nvidia/tritonserver:25.08-trtllm-python-py3 \
tritonserver --model-repository=/opt/tritonserver/model_repo
```
### What's next
* [vLLM Inference Server](/quick-guides/llms/frameworks/vllm-server): Easier setup for most use cases
* [Inference Frameworks](/quick-guides/llms/frameworks): Compare all serving stacks
* [Instance Types](/concepts/instance-types): H100 NVLink cluster requirements
* [Networking](/concepts/networking): SSH tunneling and port access
## vLLM Inference Server
Deploy an OpenAI-compatible inference server using [vLLM](https://github.com/vllm-project/vllm) on Spheron H100 or A100 instances.
### Recommended hardware
| Model Size | Recommended GPU | Instance Type | Notes |
| ---------- | ---------------------- | ------------- | ------------------------------------ |
| 7B–13B | H100 80GB (1×) | Dedicated | Single-GPU, fastest throughput |
| 30B+ | A100 80GB (2×) | Dedicated | Use `tensor_parallel_size=2` |
| 70B+ | H100 NVLink (4× or 8×) | Cluster | Use NVLink offers for best bandwidth |
For multi-GPU offers, select an offer with `interconnectType: "NVLink"` for maximum tensor-parallel performance.
### Manual setup
Use these steps to set up the server manually after SSH-ing into your instance. This works on any provider regardless of cloud-init support.
#### Step 1: Connect to your instance
```bash
ssh @
```
Replace `` with the username shown in the instance details panel in the dashboard (e.g., `ubuntu` for Spheron AI instances) and `` with your instance's public IP.
#### Step 2: Install vLLM
```bash
sudo apt-get update -y
sudo apt-get install -y python3-pip
pip install vllm
```
#### Step 3: Start the server
Run the server in the foreground to verify it works:
```bash
python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-8B-Instruct \
--tensor-parallel-size 1 \
--port 8000 \
--gpu-memory-utilization 0.9
```
Press `Ctrl+C` to stop. Replace `meta-llama/Meta-Llama-3.1-8B-Instruct` with your target model and adjust `--tensor-parallel-size` to match the number of GPUs on your instance.
#### Step 4: Run as a background service
To keep the server running after you close your SSH session, create a systemd service:
```bash
sudo tee /etc/systemd/system/vllm.service > /dev/null << 'EOF'
[Unit]
Description=vLLM Inference Server
After=network.target
[Service]
Type=simple
ExecStart=/usr/bin/python3 -m vllm.entrypoints.openai.api_server \
--model meta-llama/Meta-Llama-3.1-8B-Instruct \
--tensor-parallel-size 1 \
--port 8000 \
--gpu-memory-utilization 0.9
Restart=on-failure
RestartSec=10
[Install]
WantedBy=multi-user.target
EOF
sudo systemctl daemon-reload
sudo systemctl enable vllm
sudo systemctl start vllm
```
### Accessing the server
:::warning[Port 8000 is publicly accessible by default; add authentication]
All ports on your instance are open by default via its dedicated public IP. Anyone who can reach your IP can send requests to the vLLM server. Add token-based authentication (`--api-key `) to the vLLM startup command before exposing the server publicly, or use SSH tunneling for development to keep the endpoint private.
:::
#### SSH tunnel (recommended)
```bash
ssh -L 8000:localhost:8000